This is the multi-page printable view of this section. Click here to print.
Activities
1 - Django Channels Tutorial
Channels allows you to use WebSockets and other non-HTTP protocols in your Django site. For example you might want to use WebSockets to allow a page on your site to immediately receive updates from your Django server without using HTTP long-polling or other expensive techniques.
In this tutorial we will build a simple chat server, where you can join an online room, post messages to the room, and have others in the same room see those messages immediately.
- Part 1: Basic Setup
- Part 2: Implement a Chat Server
- Part 3: Rewrite Chat Server as Asynchronous
- Part 4: Automated Testing
How this copy differs from the original
This is a copy of the official Channels tutorial, changed to match the way we have worked in our fork of the MDN Django Tutorial:
- You don’t create a new project. The
chatapp goes into your existing locallibrary repository, next tocatalog. Everywhere the original saysmysite, this copy sayslocallibrary_config. - Dependencies are managed with uv.
pip installbecomesuv add, and every command is run withuv run python …. - Edits to existing files are additions. The original shows complete
settings.pyandurls.pycontents because it assumes a new, empty project. Here you only add lines, so you keep what you built forcatalog. - Part 4’s tests use a separate database file. The original’s test settings would delete your development database; this copy’s don’t.
- Part 4 doesn’t need a manual chromedriver install. Selenium downloads the right driver itself.
This copy was checked on 2026-09-29 with Channels 4.3.2, Daphne 4.2.3, channels-redis 4.3.0, Selenium 4.49, Django 6.1.1, and Python 3.14.
The original tutorial is Copyright (c) Django Software Foundation and individual contributors, and is used under its BSD 3-Clause license.
1.1 - Tutorial Part 1: Basic Setup
If you encounter any issue during your coding session, please see the Channels troubleshooting section.
In this tutorial we will build a simple chat server. It will have two pages:
- An index view that lets you type the name of a chat room to join.
- A room view that lets you see messages posted in a particular chat room.
The room view will use a WebSocket to communicate with the Django server and listen for any messages that are posted.
We assume that you have completed our fork of the MDN Django Tutorial
so far, and that you have your locallibrary repository: a uv project with manage.py,
pyproject.toml, and uv.lock at its root, the locallibrary_config project package,
and the catalog app. Every command in this tutorial is run from that root folder.
You can check which version of Django your project uses by running the following command in your terminal:
uv run python -m django --version
Installing Channels and Daphne
Add Channels, together with the Daphne server, to your project:
uv add "channels[daphne]"
Just like uv add "django" did when you set up your project, this records the dependency
in pyproject.toml, installs it into .venv, and pins the exact versions in uv.lock.
Commit both files.
You can check that they’re installed by running the following command:
uv run python -c "import channels; import daphne; print(channels.__version__, daphne.__version__)"
This tutorial was checked with Channels 4.3.2 and Daphne 4.2.3, on Django 6.1 and Python 3.14.
Redis
This tutorial also uses Docker to install and run Redis. We use Redis as the backing store for the channel layer, which is an optional component of the Channels library that we use in the tutorial. Install Docker from its official website - there are official runtimes for Mac OS and Windows that make it easy to use, and packages for many Linux distributions where it can run natively.
While you can run the standard Django runserver without the need
for Docker, the channels features we’ll be using in later parts of the
tutorial will need Redis to run, and we recommend Docker as the easiest
way to do this. If you’d rather not use Docker, Part 2 also shows
how to run Redis without it.
Creating the Chat app
You don’t need to create a project: you already have one. We will put the code
for the chat server in its own app, alongside catalog.
Make sure you’re in the same directory as manage.py and type this command:
uv run python manage.py startapp chat
That’ll create a directory chat next to catalog, which is laid out like this:
chat/
    __init__.py
    admin.py
    apps.py
    migrations/
        __init__.py
    models.py
    tests.py
    views.py
For the purposes of this tutorial, we will only be working with chat/views.py
and chat/__init__.py. So remove all other files from the chat directory.
After removing unnecessary files, the chat directory should look like:
chat/
    __init__.py
    views.py
We need to tell our project that the chat app is installed. Edit the
locallibrary_config/settings.py file and add 'chat' to the end of the
INSTALLED_APPS setting, after catalog. Don’t remove anything that’s already there.
It’ll look like this:
# locallibrary_config/settings.py
INSTALLED_APPS = [
    'django.contrib.admin',
    'django.contrib.auth',
    'django.contrib.contenttypes',
    'django.contrib.sessions',
    'django.contrib.messages',
    'django.contrib.staticfiles',
    # Add our new application
    'catalog.apps.CatalogConfig', # This object was created for us in /catalog/apps.py
    'chat',
]
Add the index view
We will now create the first view, an index view that lets you type the name of a chat room to join.
Create a templates directory in your chat directory. Within the
templates directory you have just created, create another directory called
chat, and within that create a file called index.html to hold the
template for the index view.
Your chat directory should now look like:
chat/
    __init__.py
    templates/
        chat/
            index.html
    views.py
Put the following code in chat/templates/chat/index.html:
<!-- chat/templates/chat/index.html -->
<!DOCTYPE html>
<html lang="en">

<head>
    <meta charset="UTF-8">
    <meta name="viewport" content="width=device-width, initial-scale=1.0">
    <title>Chat Rooms</title>
    <link rel="icon" href="https://fav.mhciael.com/💬">
</head>

<body>
    <form>
        What chat room would you like to enter?<br>
        <input id="room-name-input" type="text" size="100"><br>
        <button id="room-name-submit" type="submit">Enter</button>
    </form>
    <script>
        document.querySelector('#room-name-input').focus();
        const form = document.querySelector('form');

        form.addEventListener('submit', function (e) {
            e.preventDefault();
            var roomName = document.querySelector('#room-name-input').value;
            window.location.pathname = '/chat/' + roomName + '/';
        });
    </script>
</body>

</html>
Create the view function for the room view.
Put the following code in chat/views.py:
# chat/views.py
from django.shortcuts import render


def index(request):
    return render(request, "chat/index.html")
To call the view, we need to map it to a URL - and for this we need a URLconf.
To create a URLconf in the chat directory, create a file called urls.py.
Your app directory should now look like:
chat/
    __init__.py
    templates/
        chat/
            index.html
    urls.py
    views.py
In the chat/urls.py file include the following code:
# chat/urls.py
from django.urls import path

from . import views


urlpatterns = [
    path("", views.index, name="chat-index"),
]
The Channels tutorial names this URL index, but your catalog app already has
a URL named index (the catalog home page). URL names are shared across the
whole project, so a second index could make {% url 'index' %} in your sidebar’s
Home link point at /chat/ instead of /catalog/. Naming it chat-index avoids
the collision.
The next step is to point the root URLconf at the chat.urls module.
Your locallibrary_config/urls.py already imports include() and already includes
catalog.urls. Add the chat app in the same style, right after the catalog block:
# locallibrary_config/urls.py
# (after the existing catalog block)
urlpatterns += [
    path('chat/', include('chat.urls')),
]
Leave the admin, catalog, redirect, and static-files entries as they are.
Let’s verify that the index view works. Run the following command:
uv run python manage.py runserver
You’ll see output like the following on the command line:
Watching for file changes with StatReloader
Performing system checks...

System check identified no issues (0 silenced).
September 29, 2026 - 09:28:06
Django version 6.1.1, using settings 'locallibrary_config.settings'
Starting development server at http://127.0.0.1:8000/
Quit the server with CONTROL-C.
Unlike in the original tutorial, you won’t see a warning about unapplied migrations, because
you already ran migrate for catalog.
Go to http://127.0.0.1:8000/chat/ 🔗 in your browser and you should see the text
“What chat room would you like to enter?” along with a text input to provide a
room name. (The site root still redirects to catalog/, so type the /chat/ path yourself.)
Type in “lobby” as the room name and press enter. You should be redirected to
the room view at http://127.0.0.1:8000/chat/lobby/ but we haven’t written the
room view yet, so you’ll get a “Page not found” error page.
Go to the terminal where you ran the runserver command and press Control-C
to stop the server.
Integrate the Channels library
So far we’ve just created a regular Django app; we haven’t used the Channels library at all. Now it’s time to integrate Channels.
Let’s start by creating a routing configuration for Channels. A Channels routing configuration is an ASGI application that is similar to a Django URLconf, in that it tells Channels what code to run when an HTTP request is received by the Channels server.
Start by replacing the contents of the locallibrary_config/asgi.py file with the following code:
# locallibrary_config/asgi.py
import os

from channels.routing import ProtocolTypeRouter
from django.core.asgi import get_asgi_application

os.environ.setdefault("DJANGO_SETTINGS_MODULE", "locallibrary_config.settings")

application = ProtocolTypeRouter(
    {
        "http": get_asgi_application(),
        # Just HTTP for now. (We can add other protocols later.)
    }
)
Now add the Daphne library to the list of installed apps, in order to enable
an ASGI version of the runserver command.
Edit the locallibrary_config/settings.py file and add 'daphne' to the top of the
INSTALLED_APPS setting. It’ll look like this:
# locallibrary_config/settings.py
INSTALLED_APPS = [
    'daphne',
    'django.contrib.admin',
    'django.contrib.auth',
    'django.contrib.contenttypes',
    'django.contrib.sessions',
    'django.contrib.messages',
    'django.contrib.staticfiles',
    # Add our new application
    'catalog.apps.CatalogConfig', # This object was created for us in /catalog/apps.py
    'chat',
]
You’ll also need to point Daphne at the root routing configuration.
Edit the locallibrary_config/settings.py file again and add the following to the bottom
of it:
# locallibrary_config/settings.py
# Daphne
ASGI_APPLICATION = "locallibrary_config.asgi.application"
With Daphne now in the installed apps, it will take control of the
runserver command, replacing the standard Django development server with
the ASGI compatible version.
The Daphne development server will conflict with any other third-party
apps that require an overloaded or replacement runserver command.
In order to solve such issues, make sure daphne is at the top of your
INSTALLED_APPS, or remove the offending app altogether.
Let’s ensure that the Channels development server is working correctly. Run the following command:
uv run python manage.py runserver
You’ll see output like the following on the command line:
Watching for file changes with StatReloader
Performing system checks...

System check identified no issues (0 silenced).
September 29, 2026 - 09:28:06
Django version 6.1.1, using settings 'locallibrary_config.settings'
Starting ASGI/Daphne version 4.2.3 development server at http://127.0.0.1:8000/
Quit the server with CONTROL-C.
Notice the line beginning with Starting ASGI/Daphne …. This indicates that the
Daphne development server has taken over from the Django development server.
Go to http://127.0.0.1:8000/chat/ 🔗 in your browser and you should still see the
index page that we created before. Your catalog pages at http://127.0.0.1:8000/catalog/ 🔗
still work too: Daphne serves them the same way.
Go to the terminal where you ran the runserver command and press Control-C
to stop the server.
This tutorial continues in Tutorial 2.
1.2 - Tutorial Part 2: Implement a Chat Server
This tutorial begins where Tutorial 1 left off. We’ll get the room page working so that you can chat with yourself and others in the same room.
Add the room view
We will now create the second view, a room view that lets you see messages posted in a particular chat room.
Create a new file chat/templates/chat/room.html.
Your app directory should now look like:
chat/
    __init__.py
    templates/
        chat/
            index.html
            room.html
    urls.py
    views.py
Create the view template for the room view in chat/templates/chat/room.html:
<!-- chat/templates/chat/room.html -->
<!DOCTYPE html>
<html lang="en">

<head>
    <meta charset="UTF-8">
    <meta name="viewport" content="width=device-width, initial-scale=1.0">
    <title>Chat Room</title>
    <link rel="icon" href="https://fav.mhciael.com/💬">
</head>

<body>
    <form>
        <textarea id="chat-log" cols="100" rows="20"></textarea><br>
        <input id="chat-message-input" type="text" size="100"><br>
        <button id="chat-message-submit" type="submit" value="Send">Send</button>
        {{ room_name|json_script:"room-name" }}
    </form>
    <script>
        const roomName = JSON.parse(document.getElementById('room-name').textContent);

        // Use wss:// when the page was loaded over https://, otherwise ws://
        const wsScheme = window.location.protocol === 'https:' ? 'wss://' : 'ws://';

        const chatSocket = new WebSocket(
            wsScheme
            + window.location.host
            + '/ws/chat/'
            + roomName
            + '/'
        );

        chatSocket.onmessage = function (e) {
            const data = JSON.parse(e.data);
            document.querySelector('#chat-log').value += (data.message + '\n');
        };

        chatSocket.onclose = function (e) {
            console.error('Chat socket closed unexpectedly');
        };

        document.querySelector('#chat-message-input').focus();


        document.querySelector('form').addEventListener('submit', (e) => {
            e.preventDefault();
            const messageInputDom = document.querySelector('#chat-message-input');
            const message = messageInputDom.value;
            chatSocket.send(JSON.stringify({
                'message': message
            }));
            messageInputDom.value = '';
        });
    </script>
</body>

</html>
Create the view function for the room view in chat/views.py:
# chat/views.py
from django.shortcuts import render


def index(request):
    return render(request, "chat/index.html")


def room(request, room_name):
    return render(request, "chat/room.html", {"room_name": room_name})
Create the route for the room view in chat/urls.py:
# chat/urls.py
from django.urls import path

from . import views

urlpatterns = [
    path("", views.index, name="chat-index"),
    path("<str:room_name>/", views.room, name="chat-room"),
]
Start the Channels development server:
uv run python manage.py runserver
Go to http://127.0.0.1:8000/chat/ 🔗 in your browser to see the index page.
Type in “lobby” as the room name and press enter. You should be redirected to
the room page at http://127.0.0.1:8000/chat/lobby 🔗 which now displays an empty
chat log.
Type the message “hello” and press enter. Nothing happens. In particular the message does not appear in the chat log. Why?
The room view is trying to open a WebSocket to the URL
ws://127.0.0.1:8000/ws/chat/lobby/ but we haven’t created a consumer that
accepts WebSocket connections yet. If you open your browser’s JavaScript
console, you should see an error that looks like:
WebSocket connection to 'ws://127.0.0.1:8000/ws/chat/lobby/' failed: Unexpected response code: 500
Write your first consumer
When Django accepts an HTTP request, it consults the root URLconf to lookup a view function, and then calls the view function to handle the request. Similarly, when Channels accepts a WebSocket connection, it consults the root routing configuration to lookup a consumer, and then calls various functions on the consumer to handle events from the connection.
We will write a basic consumer that accepts WebSocket connections on the path
/ws/chat/ROOM_NAME/ that takes any message it receives on the WebSocket and
echos it back to the same WebSocket.
It is good practice to use a common path prefix like /ws/ to distinguish
WebSocket connections from ordinary HTTP connections because it will make
deploying Channels to a production environment in certain configurations
easier.
In particular for large sites it will be possible to configure a production-grade HTTP server like nginx to route requests based on path to either (1) a production-grade WSGI server like Gunicorn+Django for ordinary HTTP requests or (2) a production-grade ASGI server like Daphne+Channels for WebSocket requests.
Note that for smaller sites you can use a simpler deployment strategy where
Daphne serves all requests - HTTP and WebSocket - rather than having a
separate WSGI server. In this deployment configuration no common path prefix
like /ws/ is necessary.
Create a new file chat/consumers.py. Your app directory should now look like:
chat/
    __init__.py
    consumers.py
    templates/
        chat/
            index.html
            room.html
    urls.py
    views.py
Put the following code in chat/consumers.py:
# chat/consumers.py
import json

from channels.generic.websocket import WebsocketConsumer


class ChatConsumer(WebsocketConsumer):
    def connect(self):
        self.accept()

    def disconnect(self, close_code):
        pass

    def receive(self, text_data):
        text_data_json = json.loads(text_data)
        message = text_data_json["message"]

        self.send(text_data=json.dumps({"message": message}))
This is a synchronous WebSocket consumer that accepts all connections, receives messages from its client, and echos those messages back to the same client. For now it does not broadcast messages to other clients in the same room.
Channels also supports writing asynchronous consumers for greater performance. However any asynchronous consumer must be careful to avoid directly performing blocking operations, such as accessing a Django model. See the Consumers reference for more information about writing asynchronous consumers.
We need to create a routing configuration for the chat app that has a route to
the consumer. Create a new file chat/routing.py. Your app directory should now
look like:
chat/
    __init__.py
    consumers.py
    routing.py
    templates/
        chat/
            index.html
            room.html
    urls.py
    views.py
Put the following code in chat/routing.py:
# chat/routing.py
from django.urls import re_path

from . import consumers

websocket_urlpatterns = [
    re_path(r"ws/chat/(?P<room_name>\w+)/$", consumers.ChatConsumer.as_asgi()),
]
We call the as_asgi() classmethod in order to get an ASGI application that
will instantiate an instance of our consumer for each user-connection. This is
similar to Django’s as_view(), which plays the same role for per-request
Django view instances.
(Note we use re_path() due to limitations in URLRouter.)
The next step is to point the main ASGI configuration at the
chat.routing module. Replace the contents of locallibrary_config/asgi.py with the code
below. The highlighted lines are what changed since you edited this file in
Part 1:
- Imports:
AuthMiddlewareStackandAllowedHostsOriginValidatorare new, andURLRouterjoinsProtocolTypeRouteron the existingchannels.routingline. django_asgi_app:get_asgi_application()is now called beforechat.routingis imported, and its result is saved indjango_asgi_app. The comment above it explains why the order matters.from chat.routing import websocket_urlpatterns: this import is new. It deliberately sits below theget_asgi_application()call rather than at the top of the file with the other imports."http": now uses the saveddjango_asgi_appinstead of callingget_asgi_application()again."websocket": this key is new and replaces the# Just HTTP for nowcomment.
# locallibrary_config/asgi.py
import os

from channels.auth import AuthMiddlewareStack
from channels.routing import ProtocolTypeRouter, URLRouter
from channels.security.websocket import AllowedHostsOriginValidator
from django.core.asgi import get_asgi_application

os.environ.setdefault("DJANGO_SETTINGS_MODULE", "locallibrary_config.settings")
# Initialize Django ASGI application early to ensure the AppRegistry
# is populated before importing code that may import ORM models.
django_asgi_app = get_asgi_application()

from chat.routing import websocket_urlpatterns

application = ProtocolTypeRouter(
    {
        "http": django_asgi_app,
        "websocket": AllowedHostsOriginValidator(
            AuthMiddlewareStack(URLRouter(websocket_urlpatterns))
        ),
    }
)
This root routing configuration specifies that when a connection is made to the
Channels development server, the ProtocolTypeRouter will first inspect the type
of connection. If it is a WebSocket connection (ws:// or wss://), the connection
will be given to the AuthMiddlewareStack.
The AuthMiddlewareStack will populate the connection’s scope with a reference to
the currently authenticated user, similar to how Django’s
AuthenticationMiddleware populates the request object of a view function with
the currently authenticated user. (Scopes will be discussed later in this
tutorial.) Then the connection will be given to the URLRouter.
The URLRouter will examine the HTTP path of the connection to route it to a
particular consumer, based on the provided url patterns.
Let’s verify that the consumer for the /ws/chat/ROOM_NAME/ path works. Django’s session
framework needs the database, which you already migrated while building catalog. Run
migrate anyway to be sure, and then start the Channels development server:
uv run python manage.py migrate
You should see:
Operations to perform:
  Apply all migrations: admin, auth, catalog, contenttypes, sessions
Running migrations:
  No migrations to apply.
Then start the server:
uv run python manage.py runserver
Go to the room page at http://127.0.0.1:8000/chat/lobby 🔗 which now displays an
empty chat log.
Type the message “hello” and press enter. You should now see “hello” echoed in the chat log.
However if you open a second browser tab to the same room page at
http://127.0.0.1:8000/chat/lobby 🔗 and type in a message, the message will not
appear in the first tab. For that to work, we need to have multiple instances of
the same ChatConsumer be able to talk to each other. Channels provides a
channel layer abstraction that enables this kind of communication between
consumers.
Go to the terminal where you ran the runserver command and press Control-C to
stop the server.
Enable a channel layer
A channel layer is a kind of communication system. It allows multiple consumer instances to talk with each other, and with other parts of Django.
A channel layer provides the following abstractions:
-
A channel is a mailbox where messages can be sent to. Each channel has a name. Anyone who has the name of a channel can send a message to the channel.
-
A group is a group of related channels. A group has a name. Anyone who has the name of a group can add/remove a channel to the group by name and send a message to all channels in the group. It is not possible to enumerate what channels are in a particular group.
Every consumer instance has an automatically generated unique channel name, and so can be communicated with via a channel layer.
In our chat application we want to have multiple instances of ChatConsumer in
the same room communicate with each other. To do that we will have each
ChatConsumer add its channel to a group whose name is based on the room name.
That will allow ChatConsumers to transmit messages to all other ChatConsumers in
the same room.
We will use a channel layer that uses Redis as its backing store. To start a Redis server on port 6379, run the following command in a separate terminal (press Control-C to stop it):
docker run --rm -p 6379:6379 redis:7
Any Redis server listening on port 6379 works. Instead of Docker you can install Redis with your system’s package manager and run it directly:
- macOS:
brew install redis, thenredis-server - Ubuntu/Debian (including WSL):
sudo apt install redis-server, thenredis-server
Leave it running in its own terminal while you work through the rest of the tutorial.
We need to install channels_redis so that Channels knows how to interface with Redis. Run the following command:
uv add channels-redis
Commit the updated pyproject.toml and uv.lock again.
Before we can use a channel layer, we must configure it. Where Redis lives is
configuration that differs between machines (your laptop vs. a deployed server),
so it belongs in your env file rather than hard-coded in settings.py. You set up
.env, .env.example, and django-environ back in
Prep 02.
At that point your env file only held the DJANGO_SUPERUSER_* values, so now
you’ll add two new variables: REDIS_URL, which tells Django how to reach the Redis
server you just started, and REDIS_SOCKET_TIMEOUT, which sets how many seconds
to wait on Redis before giving up.
A Redis URL has the form redis://HOST:PORT/DB:
redis://is the scheme (userediss://, with two s’s, for a TLS connection to a hosted Redis)HOSTis the machine Redis runs on. Your Docker container (orredis-server) is on your own machine, so use127.0.0.1PORTis the port Redis listens on. The-p 6379:6379in thedocker runcommand above publishes Redis on port6379DBis the Redis database number. A fresh Redis server has databases0–15; we’ll use0
-
Open
.env(in the root of your project, next tomanage.py) and add these lines below the existingDJANGO_SUPERUSER_*lines:DJANGO_SUPERUSER_USERNAME="me" DJANGO_SUPERUSER_PASSWORD="me" DJANGO_SUPERUSER_EMAIL="me@me.me" REDIS_URL="redis://127.0.0.1:6379/0" REDIS_SOCKET_TIMEOUT=10 -
Add the same
REDIS_URLandREDIS_SOCKET_TIMEOUTlines to.env.example, so anyone who copies it to create their own.envgets a working value. -
Commit
.env.example(but never.env; it should already be listed in your.gitignore).
If you ran Redis on a different port (e.g. docker run --rm -p 6380:6379 redis:7
because something else was using 6379), change only the port in your .env, for
example REDIS_URL="redis://127.0.0.1:6380/0". Your settings.py won’t need to change.
Likewise, if you still see Redis timeouts, try raising REDIS_SOCKET_TIMEOUT in your .env.
Next, edit the locallibrary_config/settings.py file and add a CHANNEL_LAYERS
setting to the bottom, below the ASGI_APPLICATION line you added in Part 1.
Instead of hard-coding the host and port, read the URL and timeout from your env file with
the env object defined near the top of settings.py.
It should look like:
# locallibrary_config/settings.py
# Channels
ASGI_APPLICATION = "locallibrary_config.asgi.application"
CHANNEL_LAYERS = {
    "default": {
        "BACKEND": "channels_redis.core.RedisChannelLayer",
        "CONFIG": {
            "hosts": [
                {
                    "address": env("REDIS_URL"),
                    "socket_timeout": env.int("REDIS_SOCKET_TIMEOUT"),
                }
            ],
        },
    },
}
The official Channels tutorial writes "hosts": [("127.0.0.1", 6379)]. channels_redis
accepts each entry in hosts in any of three forms:
- a
(host, port)tuple, e.g.("127.0.0.1", 6379) - a URL string, e.g.
"redis://127.0.0.1:6379/0" - a dict with an
"address"key (a URL) plus extra Redis connection options
We use the dict form so that we can set socket_timeout (in seconds) as well as
the address, both read from .env. A longer timeout gives the connection to Redis
more time before giving up; without it, some setups hit timeout errors talking to Redis.
env.int(...) converts the value to an integer, since everything read from .env starts out as a string.
If Django fails to start with ImproperlyConfigured: Set the REDIS_URL environment variable
(or REDIS_SOCKET_TIMEOUT), check that the variable is in your .env (not just .env.example)
and that .env sits next to manage.py.
It is possible to have multiple channel layers configured.
However most projects will just use a single 'default' channel layer.
Let’s make sure that the channel layer can communicate with Redis. Open a Django shell and run the following commands:
uv run python manage.py shell
import channels.layers
channel_layer = channels.layers.get_channel_layer()
from asgiref.sync import async_to_sync
async_to_sync(channel_layer.send)('test_channel', {'type': 'hello'})
async_to_sync(channel_layer.receive)('test_channel')
You should see:
{'type': 'hello'}
(The number of objects the shell imports automatically depends on your models; that’s the same auto-import you’ve seen in the shell before.)
Type Control-D (or exit()) to exit the Django shell.
Now that we have a channel layer, let’s use it in ChatConsumer. Put the
following code in chat/consumers.py, replacing the old code:
# chat/consumers.py
import json

from asgiref.sync import async_to_sync
from channels.generic.websocket import WebsocketConsumer


class ChatConsumer(WebsocketConsumer):
    def connect(self):
        self.room_name = self.scope["url_route"]["kwargs"]["room_name"]
        self.room_group_name = f"chat_{self.room_name}"

        # Join room group
        async_to_sync(self.channel_layer.group_add)(
            self.room_group_name, self.channel_name
        )

        self.accept()

    def disconnect(self, close_code):
        # Leave room group
        async_to_sync(self.channel_layer.group_discard)(
            self.room_group_name, self.channel_name
        )

    # Receive message from WebSocket
    def receive(self, text_data):
        text_data_json = json.loads(text_data)
        message = text_data_json["message"]

        # Send message to room group
        async_to_sync(self.channel_layer.group_send)(
            self.room_group_name, {"type": "chat.message", "message": message}
        )

    # Receive message from room group
    def chat_message(self, event):
        message = event["message"]

        # Send message to WebSocket
        self.send(text_data=json.dumps({"message": message}))
When a user posts a message, a JavaScript function will transmit the message over WebSocket to a ChatConsumer. The ChatConsumer will receive that message and forward it to the group corresponding to the room name. Every ChatConsumer in the same group (and thus in the same room) will then receive the message from the group and forward it over WebSocket back to JavaScript, where it will be appended to the chat log.
Several parts of the new ChatConsumer code deserve further explanation:
-
self.scope["url_route"]["kwargs"]["room_name"]- Obtains the
'room_name'parameter from the URL route inchat/routing.pythat opened the WebSocket connection to the consumer. - Every consumer has a scope that contains information about its connection, including in particular any positional or keyword arguments from the URL route and the currently authenticated user if any.
- Obtains the
-
self.room_group_name = f"chat_{self.room_name}"- Constructs a Channels group name directly from the user-specified room name, without any quoting or escaping.
- Group names may only contain alphanumerics, hyphens, underscores, or periods. Therefore this example code will fail on room names that have other characters.
-
async_to_sync(self.channel_layer.group_add)(...)- Joins a group.
- The
async_to_sync(...)wrapper is required because ChatConsumer is a synchronous WebsocketConsumer but it is calling an asynchronous channel layer method. (All channel layer methods are asynchronous.) - Group names are restricted to ASCII alphanumerics, hyphens, and periods only and are limited to a maximum length of 100 in the default backend. Since this code constructs a group name directly from the room name, it will fail if the room name contains any characters that aren’t valid in a group name or exceeds the length limit.
-
self.accept()- Accepts the WebSocket connection.
- If you do not call
accept()within theconnect()method then the connection will be rejected and closed. You might want to reject a connection for example because the requesting user is not authorized to perform the requested action. - It is recommended that
accept()be called as the last action inconnect()if you choose to accept the connection.
-
async_to_sync(self.channel_layer.group_discard)(...)- Leaves a group.
-
async_to_sync(self.channel_layer.group_send)- Sends an event to a group.
- An event has a special
'type'key corresponding to the name of the method that should be invoked on consumers that receive the event. This translation is done by replacing.with_, thus in this example,chat.messagecalls thechat_messagemethod.
Let’s verify that the new consumer for the /ws/chat/ROOM_NAME/ path works.
To start the Channels development server, run the following command:
uv run python manage.py runserver
Open a browser tab to the room page at http://127.0.0.1:8000/chat/lobby/. Open a second browser tab to the same room page.
In the second browser tab, type the message “hello” and press enter. You should now see “hello” echoed in the chat log in both the second browser tab and in the first browser tab.
You now have a basic fully-functional chat server!
This tutorial continues in Tutorial 3.
1.3 - Tutorial Part 3: Rewrite Chat Server as Asynchronous
This tutorial begins where Tutorial 2 left off. We’ll rewrite the consumer code to be asynchronous rather than synchronous to improve its performance.
Rewrite the consumer to be asynchronous
The ChatConsumer that we have written is currently synchronous. Synchronous
consumers are convenient because they can call regular synchronous I/O functions
such as those that access Django models without writing special code. However
asynchronous consumers can provide a higher level of performance since they
don’t need to create additional threads when handling requests.
ChatConsumer only uses async-native libraries (Channels and the channel layer)
and in particular it does not access synchronous code. Therefore it can
be rewritten to be asynchronous without complications.
Even if ChatConsumer did access Django models or synchronous code it
would still be possible to rewrite it as asynchronous. Utilities like
asgiref.sync.sync_to_async and
channels.db.database_sync_to_async can be
used to call synchronous code from an asynchronous consumer. The performance
gains however would be less than if it only used async-native libraries. Django
models include methods prefixed with a that can be used safely from async
contexts, provided that
channels.db.aclose_old_connections is called
occasionally.
Let’s rewrite ChatConsumer to be asynchronous.
Put the following code in chat/consumers.py:
# chat/consumers.py
import json

from channels.generic.websocket import AsyncWebsocketConsumer


class ChatConsumer(AsyncWebsocketConsumer):
    async def connect(self):
        self.room_name = self.scope["url_route"]["kwargs"]["room_name"]
        self.room_group_name = f"chat_{self.room_name}"

        # Join room group
        await self.channel_layer.group_add(self.room_group_name, self.channel_name)

        await self.accept()

    async def disconnect(self, close_code):
        # Leave room group
        await self.channel_layer.group_discard(self.room_group_name, self.channel_name)

    # Receive message from WebSocket
    async def receive(self, text_data):
        text_data_json = json.loads(text_data)
        message = text_data_json["message"]

        # Send message to room group
        await self.channel_layer.group_send(
            self.room_group_name, {"type": "chat.message", "message": message}
        )

    # Receive message from room group
    async def chat_message(self, event):
        message = event["message"]

        # Send message to WebSocket
        await self.send(text_data=json.dumps({"message": message}))
This new code for ChatConsumer is very similar to the original code, with the following differences:
ChatConsumernow inherits fromAsyncWebsocketConsumerrather thanWebsocketConsumer.- All methods are
async defrather than justdef. awaitis used to call asynchronous functions that perform I/O.async_to_syncis no longer needed when calling methods on the channel layer.
Let’s verify that the consumer for the /ws/chat/ROOM_NAME/ path still works.
Make sure Redis is still running, then start the Channels development server:
uv run python manage.py runserver
Open a browser tab to the room page at http://127.0.0.1:8000/chat/lobby/. Open a second browser tab to the same room page.
In the second browser tab, type the message “hello” and press enter. You should now see “hello” echoed in the chat log in both the second browser tab and in the first browser tab.
Now your chat server is fully asynchronous!
This tutorial continues in Tutorial 4.
1.4 - Tutorial Part 4: Automated Testing
This tutorial begins where Tutorial 3 left off. We’ve built a simple chat server and now we’ll create some automated tests for it.
Testing the views
To ensure that the chat server keeps working, we will write some tests.
We will write a suite of end-to-end tests using Selenium to control a Chrome web browser. These tests will ensure that:
- when a chat message is posted then it is seen by everyone in the same room
- when a chat message is posted then it is not seen by anyone in a different room
Install the Chrome web browser, if you do not already have it.
Install Selenium as a development dependency, like the testing tools in the MDN tutorial, so that it is never installed on your production server. Run the following command:
uv add --dev selenium
Commit the updated pyproject.toml and uv.lock.
You don’t need to install chromedriver yourself. The first time the tests start Chrome, Selenium finds a matching chromedriver or downloads one automatically.
Create a new file chat/tests.py. Your app directory should now look like:
chat/
    __init__.py
    consumers.py
    routing.py
    templates/
        chat/
            index.html
            room.html
    tests.py
    urls.py
    views.py
Put the following code in chat/tests.py:
# chat/tests.py
from channels.testing import ChannelsLiveServerTestCase
from selenium import webdriver
from selenium.webdriver.common.action_chains import ActionChains
from selenium.webdriver.common.by import By
from selenium.webdriver.common.keys import Keys
from selenium.webdriver.support.wait import WebDriverWait


class ChatTests(ChannelsLiveServerTestCase):
    serve_static = True  # emulate StaticLiveServerTestCase

    @classmethod
    def setUpClass(cls):
        super().setUpClass()
        try:
            # NOTE: Selenium finds or downloads a matching chromedriver automatically
            cls.driver = webdriver.Chrome()
        except:
            super().tearDownClass()
            raise

    @classmethod
    def tearDownClass(cls):
        cls.driver.quit()
        super().tearDownClass()

    def test_when_chat_message_posted_then_seen_by_everyone_in_same_room(self):
        try:
            self._enter_chat_room("room_1")

            self._open_new_window()
            self._enter_chat_room("room_1")

            self._switch_to_window(0)
            self._post_message("hello")
            WebDriverWait(self.driver, 2).until(
                lambda _: "hello" in self._chat_log_value,
                "Message was not received by window 1 from window 1",
            )
            self._switch_to_window(1)
            WebDriverWait(self.driver, 2).until(
                lambda _: "hello" in self._chat_log_value,
                "Message was not received by window 2 from window 1",
            )
        finally:
            self._close_all_new_windows()

    def test_when_chat_message_posted_then_not_seen_by_anyone_in_different_room(self):
        try:
            self._enter_chat_room("room_1")

            self._open_new_window()
            self._enter_chat_room("room_2")

            self._switch_to_window(0)
            self._post_message("hello")
            WebDriverWait(self.driver, 2).until(
                lambda _: "hello" in self._chat_log_value,
                "Message was not received by window 1 from window 1",
            )

            self._switch_to_window(1)
            self._post_message("world")
            WebDriverWait(self.driver, 2).until(
                lambda _: "world" in self._chat_log_value,
                "Message was not received by window 2 from window 2",
            )
            self.assertTrue(
                "hello" not in self._chat_log_value,
                "Message was improperly received by window 2 from window 1",
            )
        finally:
            self._close_all_new_windows()

    # === Utility ===

    def _enter_chat_room(self, room_name):
        self.driver.get(self.live_server_url + "/chat/")
        ActionChains(self.driver).send_keys(room_name, Keys.ENTER).perform()
        WebDriverWait(self.driver, 2).until(
            lambda _: room_name in self.driver.current_url
        )

    def _open_new_window(self):
        self.driver.execute_script('window.open("about:blank", "_blank");')
        self._switch_to_window(-1)

    def _close_all_new_windows(self):
        while len(self.driver.window_handles) > 1:
            self._switch_to_window(-1)
            self.driver.execute_script("window.close();")
        if len(self.driver.window_handles) == 1:
            self._switch_to_window(0)

    def _switch_to_window(self, window_index):
        self.driver.switch_to.window(self.driver.window_handles[window_index])

    def _post_message(self, message):
        ActionChains(self.driver).send_keys(message, Keys.ENTER).perform()

    @property
    def _chat_log_value(self):
        return self.driver.find_element(
            by=By.CSS_SELECTOR, value="#chat-log"
        ).get_property("value")
Our test suite extends ChannelsLiveServerTestCase rather than Django’s usual
suites for end-to-end tests (StaticLiveServerTestCase or LiveServerTestCase) so
that URLs inside the Channels routing configuration like /ws/chat/ROOM_NAME/
will work inside the suite.
We are using sqlite3, which for testing is run as an in-memory database, and therefore the
tests will not run correctly. We need to tell our project that the test database should be a
file instead. Edit the DATABASES setting in locallibrary_config/settings.py and add a
TEST entry, keeping the ENGINE and NAME lines you already have:
# locallibrary_config/settings.py
DATABASES = {
    'default': {
        'ENGINE': 'django.db.backends.sqlite3',
        'NAME': BASE_DIR / 'db.sqlite3',
        'TEST': {
            'NAME': BASE_DIR / 'test_db.sqlite3',
        },
    }
}
The original tutorial sets the test NAME to db.sqlite3, the same file as your development
database. Django deletes the test database when the tests finish, so that setting would
delete your development database: your superuser, and every book, author, and genre you’ve
created. Make sure the TEST name above is test_db.sqlite3.
Django creates test_db.sqlite3 while the tests run, and it should never be committed. If you
started your .gitignore from GitHub’s Python template, its *.sqlite3 line already ignores
it. Otherwise, add this line:
test_db.sqlite3
The tests use your real channel layer, so Redis must be running (see Part 2). To run the tests, run the following command:
uv run python manage.py test chat.tests
You should see output that looks like:
Creating test database for alias 'default'...
Found 2 test(s).
System check identified no issues (0 silenced).
Not Found: /favicon.ico
..
----------------------------------------------------------------------
Ran 2 tests in 8.953s

OK
Destroying test database for alias 'default'...
Chrome windows will open and close by themselves while the tests run. The Not Found: /favicon.ico line is Chrome asking for an icon the chat pages don’t have; you can ignore it.
You now have a tested chat server!
What’s next?
Congratulations! You’ve fully implemented a chat server, made it performant by writing it in asynchronous style, and written automated tests to ensure it won’t break.
This is the end of the tutorial. At this point you should know enough to start an app of your own that uses Channels and start fooling around. As you need to learn new tricks, come back to the rest of the Channels documentation.
2 - Django Ninja Quickstart
In three short pages you’ll build a small chat API for the chat rooms in your locallibrary: people can browse rooms, filter and paginate them, read a room’s messages, sign in, and post a message that shows up live in the chat page. Along the way you’ll see most of what makes Django Ninja pleasant to use: type hints that validate input, schemas generated from your models, interactive docs, auth, and routers.
This guide assumes you already know Django: projects, apps, models and migrations. It won’t explain those; it only shows the Django Ninja parts.
| Page | What you’ll do |
|---|---|
| 1. First API | Install, create an API, write an endpoint, open the interactive docs |
| 2. Models & Schemas | Save chat rooms and messages to the database, then full CRUD for the Room model, plus pagination and filtering |
| 3. Auth, Routers & Next Steps | Split the API into a router, require login, let users post messages to a room |
Before you start
We assume that you have completed preps 01-06 (our fork of the MDN Django Tutorial through Part 8) and all four parts of our Channels tutorial. You have your locallibrary repository: a uv project with manage.py, pyproject.toml, and uv.lock at its root, the locallibrary_config project package, the catalog app, and the asynchronous chat app. Every command in this guide is run from that root folder.
The chat app works, but it forgets everything: a message exists only while it travels through Redis to the browsers in the room. An API that lists rooms and messages needs them in the database. So before the Django Ninja parts, page 2 adds Room and Message models to the chat app, saves every message to the database, and shows a room’s history when you open it.
How this copy differs from the original
This is a copy of the official Django Ninja Quick Start, changed to match the way we have worked in our fork of the MDN Django Tutorial and our Channels tutorial:
- You don’t create a new project or app. The API goes into your existing locallibrary repository. Everywhere the original says
mysite, this copy sayslocallibrary_config, and the original’seventsapp is yourchatapp. - Chat rooms instead of events. The original builds an API for an
Eventmodel, and users register for events. This copy builds the same API for aRoommodel, and users postMessages to rooms. Each piece of the original has a counterpart here:EventFilter’supcomingfilter becomesRoomFilter’srecentfilter, the409for an event that clashes with another becomes a409for a room name that’s taken, and the nestedRegistrationOutschema becomes a nestedMessageOutschema. - You add models to the chat app first. Page 2 starts with
RoomandMessagemodels, saves messages from the WebSocket consumer, and shows a room’s saved messages when you open it. The original has nothing like this, because it starts from an empty app. - Posted messages go to the chat page. On page 3, a message posted through the API is also sent to everyone in the room over the channel layer, so it appears in the chat page right away.
- Dependencies are managed with uv.
pip installbecomesuv add, and every command is run withuv run python …. - Edits to existing files are additions. The original shows complete
urls.pycontents because it assumes a new, empty project. Here you only add lines, so you keep what you built forcatalogandchat.
This copy follows the Django Ninja documentation as of 2026-10-19 (Django Ninja 1.7.1), on Django 6.1, Channels 4.3, and Python 3.14. Once you finish, continue with our Django Ninja Tutorial.
The original Quick Start is Copyright (c) 2025 Vitaliy Kucheryaviy, and is used under its MIT license.
2.1 - Quick Start Part 1: First API
Install
Add Django Ninja to your project:
uv add django-ninja
Just like uv add "channels[daphne]" did in the Channels tutorial, this records the dependency in pyproject.toml, installs it into .venv, and pins the exact versions in uv.lock. Commit both files.
Django Ninja works with any Django project. The original Quick Start creates a new project and an events app at this point. You don’t: you already have a project, locallibrary_config, and the chat app plays the part of events for the rest of this guide.
Django Ninja itself doesn’t need to be in INSTALLED_APPS, but adding "ninja" lets Django’s runserver and collectstatic serve the interactive docs’ assets locally instead of from a CDN. Edit locallibrary_config/settings.py and add 'ninja' to the end of INSTALLED_APPS, after chat. Don’t remove anything that’s already there:
# locallibrary_config/settings.py
INSTALLED_APPS = [
    'daphne',
    'django.contrib.admin',
    'django.contrib.auth',
    'django.contrib.contenttypes',
    'django.contrib.sessions',
    'django.contrib.messages',
    'django.contrib.staticfiles',
    # Add our new application
    'catalog.apps.CatalogConfig', # This object was created for us in /catalog/apps.py
    'chat',
    'ninja',
]
Create the API
An API starts with a NinjaAPI instance. Create locallibrary_config/api.py next to urls.py:
# locallibrary_config/api.py
from ninja import NinjaAPI

api = NinjaAPI()


@api.get("/hello")
def hello(request, name: str = "world"):
    return {"message": f"Hello, {name}!"}
Then mount it in locallibrary_config/urls.py, like any other set of views. That file already includes catalog.urls and chat.urls. Add the API in the same style, at the end of the file:
# locallibrary_config/urls.py
# (after the existing blocks)
# Mount the Django Ninja API
from .api import api

urlpatterns += [
    path('api/', api.urls),
]
Leave the admin, catalog, chat, redirect, and static-files entries as they are.
Run the server:
uv run python manage.py runserver
This is the Daphne development server from the Channels tutorial. It serves your Django Ninja API the same way it serves your catalog pages. Redis doesn’t need to be running for this page; only the chat’s WebSockets use it.
Open http://127.0.0.1:8000/api/hello?name=Ninja 🔗:
{"message": "Hello, Ninja!"}
A few things happened with no extra code:
@api.get("/hello")registered aGETendpoint at/api/hello.- The
requestargument is a regular DjangoHttpRequest, sorequest.user, sessions and middleware all work as usual. name: str = "world"became an optional query parameter with a default value.- The returned
dictwas serialized to JSON.
Type hints are validation
Every argument’s type hint says what the endpoint accepts. Add an endpoint with two required integers to locallibrary_config/api.py:
# locallibrary_config/api.py
@api.get("/add")
def add(request, a: int, b: int):
    return {"result": a + b}
/api/add?a=2&b=3 🔗 returns {"result": 5}, and a and b arrive in your function as real ints, not strings. Invalid input never reaches your code. Try /api/add?a=2&b=three 🔗:
{
    "detail": [
        {
            "type": "int_parsing",
            "loc": ["query", "b"],
            "msg": "Input should be a valid integer, unable to parse string as an integer"
        }
    ]
}
The response has status code 422, and the error points to exactly which parameter failed and why. The same works for float, bool, date, datetime, UUID, enums, and more. See Query Parameters for the full list.
Interactive docs
Now open http://127.0.0.1:8000/api/docs 🔗:
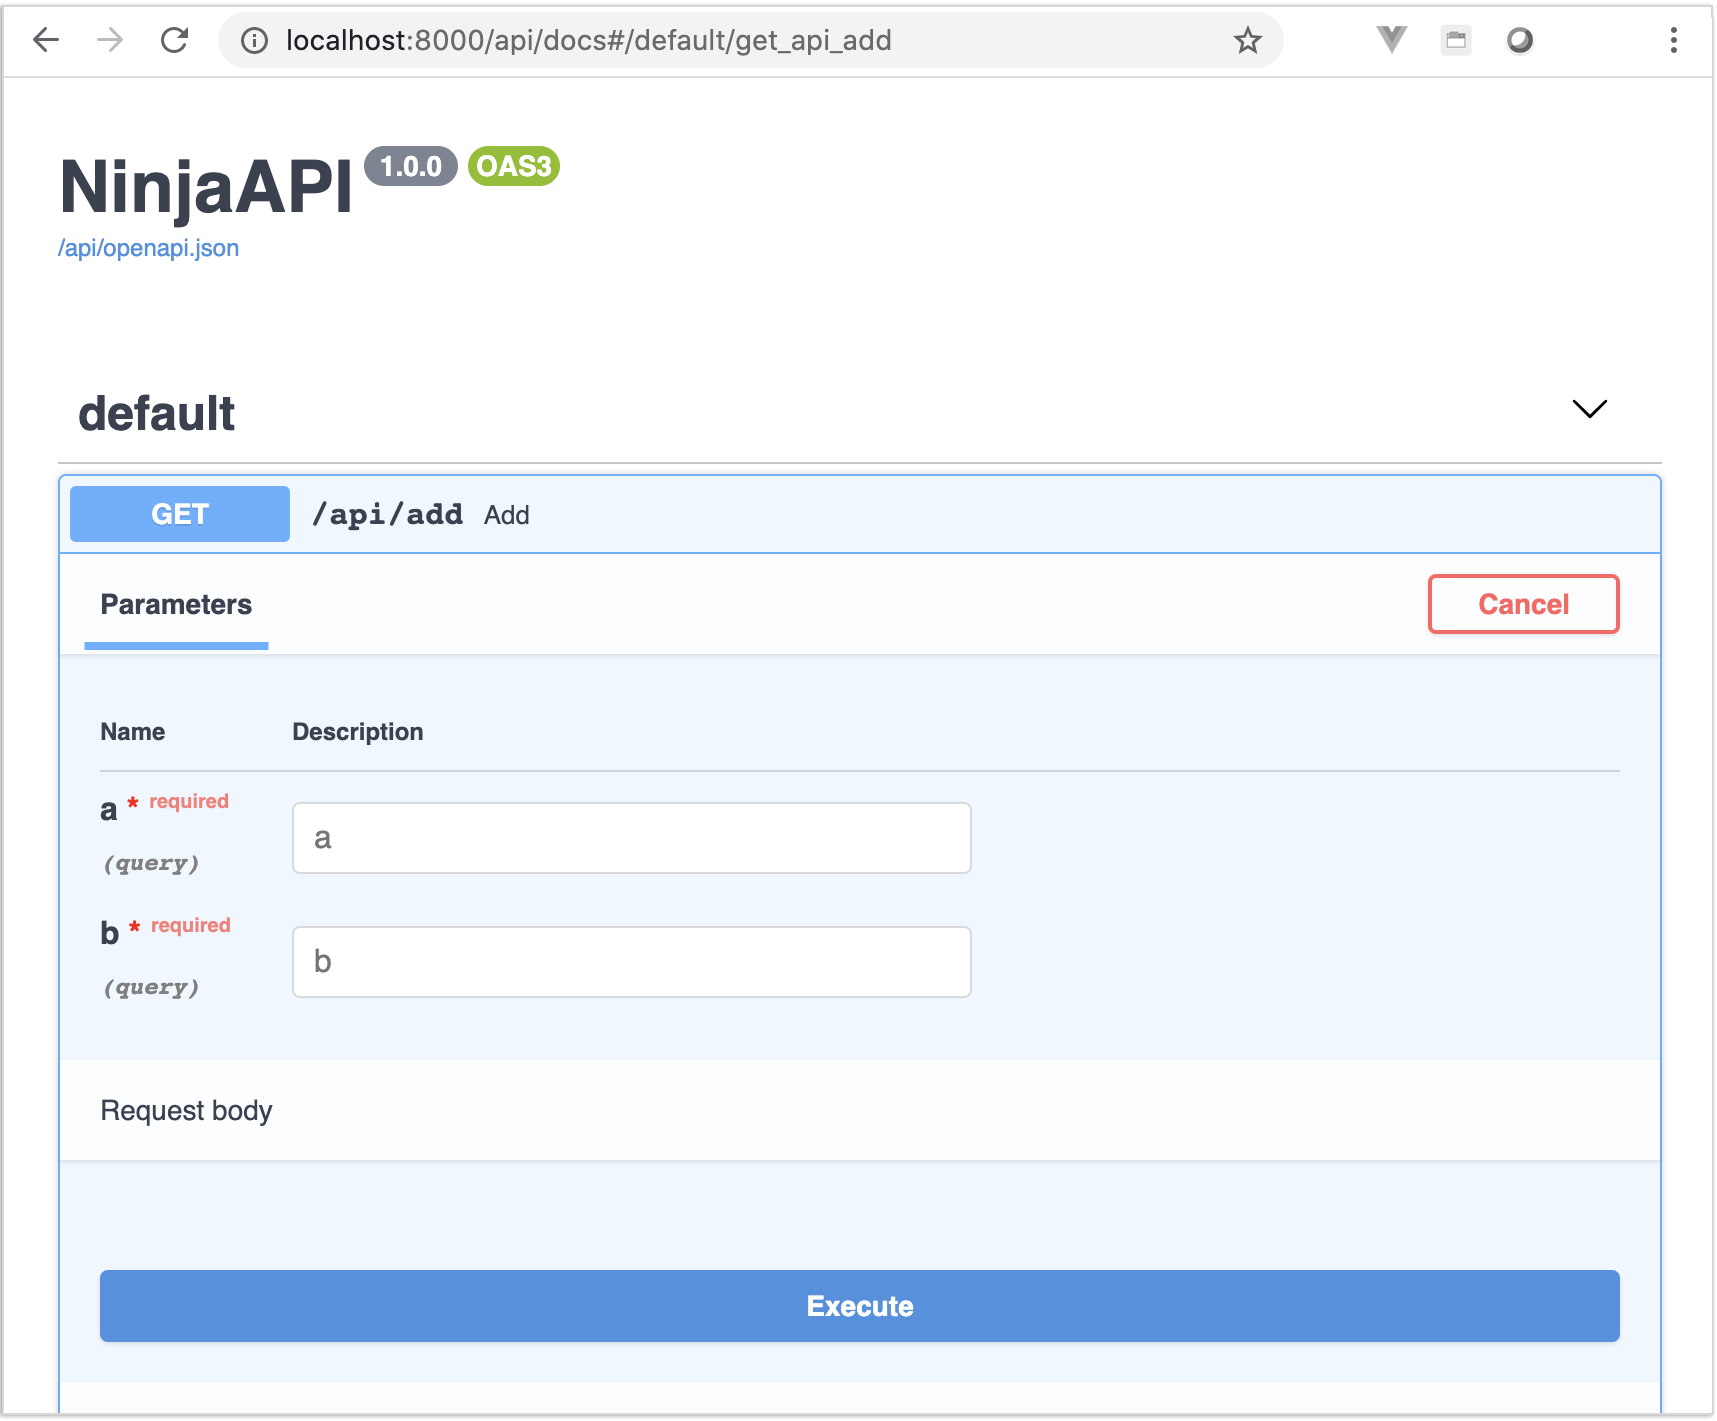
Django Ninja generates an OpenAPI schema from your code, including parameter types, required fields and responses, and serves it with Swagger UI. Click an endpoint, then Try it out to call it from the browser. The raw schema is at /api/openapi.json, ready for client generators and API tools.
The docs are never out of date, because they are built from the same type hints that validate your requests. See OpenAPI & Interactive Docs to customize them.
Next
So far the API only returns hand-built dicts. Next, give your chat rooms and messages a home in the database, connect the API to them, and build a real CRUD API: Models & Schemas.
2.2 - Quick Start Part 2: Models & Schemas
On this page you’ll give your chat rooms and messages a home in the database, then turn the Room model into a complete CRUD API, and add pagination and filtering. Along the way you’ll see how schemas are generated from your models.
The models
Nothing Ninja-specific here, just regular Django models. The original Quick Start has a single Event model. Your chat needs two: a Room, and the Messages posted in it.
In Part 1 of the Channels tutorial, you deleted chat/models.py because the chat didn’t store anything. Create it again, with this code:
# chat/models.py
from django.conf import settings
from django.db import models


class Room(models.Model):
    name = models.CharField(max_length=50, unique=True)
    topic = models.CharField(max_length=200, blank=True, default="")
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.name


class Message(models.Model):
    room = models.ForeignKey(Room, related_name="messages", on_delete=models.CASCADE)
    author = models.ForeignKey(
        settings.AUTH_USER_MODEL,
        null=True,
        blank=True,
        related_name="chat_messages",
        on_delete=models.SET_NULL,
    )
    content = models.TextField()
    created_at = models.DateTimeField(auto_now_add=True)

    class Meta:
        ordering = ["created_at", "id"]

    def __str__(self):
        return f"{self.author or 'anonymous'} in {self.room}: {self.content[:50]}"
- A room’s
nameis the name in its URL, likelobbyin/chat/lobby/, so two rooms can’t share one:unique=True. It’s also part of the room’s Channels group name (chat_lobby), and group names must be shorter than 100 characters, so 50 leaves plenty of room. topicis optional.blank=Truelets forms and the admin leave it empty, anddefault=""gives new rooms an empty topic.authoris optional too, because anyone can chat without logging in:AuthMiddlewareStackin yourasgi.pyputs an anonymous user in the scope for them. If a user is deleted, their messages stay, with no author (SET_NULL).related_name="chat_messages"lets you writeuser.chat_messages. Plainmessageswould read as if it had to do with Django’s messages framework, which is also installed.Meta.orderingkeeps every list of messages oldest first, the way a chat log reads.
You also deleted the chat/migrations/ folder in Part 1 of the Channels tutorial. Naming the app tells makemigrations to create it again:
uv run python manage.py makemigrations chat
uv run python manage.py migrate
You should see:
Migrations for 'chat':
  chat/migrations/0001_initial.py
    + Create model Room
    + Create model Message
Operations to perform:
  Apply all migrations: admin, auth, catalog, chat, contenttypes, sessions
Running migrations:
  Applying chat.0001_initial... OK
Your Channels tutorial also deleted chat/admin.py. Create it again, so you can look at rooms and messages in the admin site:
# chat/admin.py
from django.contrib import admin

from .models import Message, Room

admin.site.register(Room)
admin.site.register(Message)
Save messages from the consumer
The ChatConsumer you wrote in Part 3 of the Channels tutorial is asynchronous. As that page’s note said, an asynchronous consumer can still use Django models, through the model methods that start with a, like aget_or_create() and acreate(), as long as it calls channels.db.aclose_old_connections() before it uses the database. Put the following code in chat/consumers.py. The highlighted lines are new:
# chat/consumers.py
import json

from channels.db import aclose_old_connections
from channels.generic.websocket import AsyncWebsocketConsumer

from .models import Message, Room


class ChatConsumer(AsyncWebsocketConsumer):
    async def connect(self):
        self.room_name = self.scope["url_route"]["kwargs"]["room_name"]
        self.room_group_name = f"chat_{self.room_name}"

        # Find the room in the database, or create it the first time anyone joins
        await aclose_old_connections()
        self.room, _ = await Room.objects.aget_or_create(name=self.room_name)

        # Join room group
        await self.channel_layer.group_add(self.room_group_name, self.channel_name)

        await self.accept()

    async def disconnect(self, close_code):
        # Leave room group
        await self.channel_layer.group_discard(self.room_group_name, self.channel_name)

    # Receive message from WebSocket
    async def receive(self, text_data):
        text_data_json = json.loads(text_data)
        message = text_data_json["message"]

        # Save the message before anyone sees it
        await aclose_old_connections()
        user = self.scope["user"]
        await Message.objects.acreate(
            room=self.room,
            author=user if user.is_authenticated else None,
            content=message,
        )

        # Send message to room group
        await self.channel_layer.group_send(
            self.room_group_name, {"type": "chat.message", "message": message}
        )

    # Receive message from room group
    async def chat_message(self, event):
        message = event["message"]

        # Send message to WebSocket
        await self.send(text_data=json.dumps({"message": message}))
aget_or_create()returns a(room, created)tuple. The first person to open/chat/lobby/creates thelobbyroom, and everyone after that joins the same row. The consumer keeps the room inself.roomfor as long as the WebSocket is open.self.scope["user"]is the user thatAuthMiddlewareStackfound, the same asrequest.userin a view. If you’re logged in, for example at/accounts/login/from Prep 06, your messages get you as their author. Otherwise they’re saved with no author.- The message is saved before it’s sent to the group. If saving fails, nobody sees a message that won’t be there when they reload the page.
Show a room’s history
Saved messages are only useful if you can see them. Update the room view in chat/views.py to load the room’s messages:
# chat/views.py
from django.shortcuts import render

from .models import Room


def index(request):
    return render(request, "chat/index.html")


def room(request, room_name):
    room = Room.objects.filter(name=room_name).first()
    chat_messages = room.messages.all() if room else []
    return render(
        request,
        "chat/room.html",
        {"room_name": room_name, "chat_messages": chat_messages},
    )
The context variable is called chat_messages, not messages. Django’s messages framework already puts a messages variable in every template’s context, and yours would hide it.
The view doesn’t create the room: opening the page isn’t enough to make a room, but connecting the WebSocket is. If the room doesn’t exist yet, there’s no history to show.
In chat/templates/chat/room.html, change only the textarea line, so that it starts with one line per saved message:
<!-- chat/templates/chat/room.html -->
<textarea id="chat-log" cols="100" rows="20">{% for chat_message in chat_messages %}{{ chat_message.content }}
{% endfor %}</textarea><br>
That’s the same format the JavaScript in the page uses when a new message arrives: the message, then a newline. The line break inside the for loop is that newline, so keep it exactly where it is, and don’t add spaces or line breaks anywhere else between the textarea tags. In particular, the {% endfor %} line must start at the very beginning of the line, even though the rest of the file is indented: any spaces before it would end up at the start of every message but the first.
Try it
Make sure Redis is running (see Part 2 of the Channels tutorial), then start the server:
uv run python manage.py runserver
Open http://127.0.0.1:8000/chat/lobby/ 🔗 in two tabs, and send “hello” and “anyone here?” from one of them. Both show up in both tabs, as before. Now reload a tab: the messages are still there.
Go to http://127.0.0.1:8000/admin/chat/message/ 🔗 and log in with your superuser. Your messages are listed there, and the lobby room is under Rooms. Messages you sent while logged in show your username as their author.
Finally, run the Channels tutorial’s tests again, to make sure the chat still works end to end:
uv run python manage.py test chat.tests
The rest of this page is about Django Ninja again. Join two or three more rooms, such as books and random, so the API has a few rooms to work with.
Schemas
A schema describes the shape of data going in or out of your API. Django Ninja schemas are Pydantic models: a class with type-annotated fields.
# locallibrary_config/api.py
from datetime import datetime

from ninja import Schema


class RoomIn(Schema):
    name: str
    topic: str = ""


class RoomOut(Schema):
    id: int
    name: str
    topic: str
    created_at: datetime
RoomIn is what clients send, and RoomOut is what they get back. They’re separate so a client can’t set id or created_at (or, later, fields you’d rather keep private). topic has a default, so it’s optional in RoomIn.
A schema doesn’t have to match a model. You’ll use plain Schema classes for anything that isn’t a table: login payloads, computed results, aggregates.
The same, generated from the model
When a schema mirrors a model, as these do, it only repeats what the model already says. ModelSchema reads the fields from the model instead:
# locallibrary_config/api.py
from ninja import ModelSchema

from chat.models import Room


class RoomIn(ModelSchema):
    class Meta:
        model = Room
        fields = ["name", "topic"]


class RoomOut(ModelSchema):
    class Meta:
        model = Room
        fields = ["id", "name", "topic", "created_at"]
These two classes behave the same as the hand-written ones, with the types and the topic default taken from the model. You also get the model’s constraints: name is limited to 50 characters because of max_length=50. When you add or change a model field, the schema follows.
The rest of this Quick Start uses the ModelSchema versions. You can mix both kinds freely, and a ModelSchema can also declare extra fields of its own (see ModelSchema).
Read: list and detail
Use response= to tell Django Ninja what an endpoint returns:
# locallibrary_config/api.py
from django.shortcuts import get_object_or_404


@api.get("/rooms", response=list[RoomOut])
def list_rooms(request):
    return Room.objects.all()


@api.get("/rooms/{room_id}", response=RoomOut)
def get_room(request, room_id: int):
    return get_object_or_404(Room, id=room_id)
- You return querysets and model instances directly. Django Ninja reads the fields listed in the schema and serializes them to JSON. There’s no serializer to call.
{room_id}in the path becomes theroom_id: intargument, converted and validated like the query parameters on the previous page.- Django’s
get_object_or_404works as usual: a missing room is a404JSON response. - Only the fields in
RoomOutare sent back, even if the object has more. The schema is also the contract shown in the docs.
GET /api/rooms/1:
{
    "id": 1,
    "name": "lobby",
    "topic": "",
    "created_at": "2026-10-19T14:02:11.482Z"
}
Create, update, delete
A schema-typed argument is read from the JSON request body. The highlighted lines are the ones explained below:
# locallibrary_config/api.py
@api.post("/rooms", response={201: RoomOut})
def create_room(request, payload: RoomIn):
    return Room.objects.create(**payload.dict())


@api.put("/rooms/{room_id}", response=RoomOut)
def update_room(request, room_id: int, payload: RoomIn):
    room = get_object_or_404(Room, id=room_id)
    for attr, value in payload.dict().items():
        setattr(room, attr, value)
    room.save()
    return room


@api.delete("/rooms/{room_id}", response={204: None})
def delete_room(request, room_id: int):
    get_object_or_404(Room, id=room_id).delete()
payload: RoomInmeans “parse the body asRoomIn”. By the time your function runs, the data is valid and typed.response={201: RoomOut}maps a status code to a schema. With only one code listed, that’s the code every response gets, socreate_roomreturns201anddelete_roomreturns204with an empty body.update_roommixes a path parameter and a body in one signature. Django Ninja works out where each argument comes from.- Deleting a room also deletes its messages, because of
on_delete=models.CASCADEonMessage.room.
Send a bad body, such as {"topic": 42}, and the error lists every problem at once:
{
    "detail": [
        {"type": "missing", "loc": ["body", "payload", "name"], "msg": "Field required"},
        {"type": "string_type", "loc": ["body", "payload", "topic"], "msg": "Input should be a valid string"}
    ]
}
Open /api/docs again. All five room endpoints are there, with request and response schemas, and you can create a room from the browser with Try it out. A room you create there is a real room: open /chat/<its name>/ and chat in it.
More than one status code
Try creating a room called lobby with Try it out. You get a 500 error, not a helpful answer: the name column is unique, so the database refuses the second lobby with an IntegrityError.
When an endpoint can answer in different ways, list every status code in response and return Status(code, data) to pick one. Replace create_room with a version that creates a room, or reports a clash with an existing one:
# locallibrary_config/api.py
from ninja import Schema, Status


class Conflict(Schema):
    message: str
    existing_id: int


@api.post("/rooms", response={201: RoomOut, 409: Conflict})
def create_room(request, payload: RoomIn):
    existing = Room.objects.filter(name=payload.name).first()
    if existing:
        return Status(409, {"message": "A room with that name already exists", "existing_id": existing.id})
    return Status(201, Room.objects.create(**payload.dict()))
Each response is validated against the schema for its code, and both appear in the interactive docs. See Responses for more.
(Renaming a room to a name that’s taken with PUT has the same problem. Fixing update_room the same way is a good exercise.)
For PATCH, where the client sends only the fields that change, use PatchDict[RoomIn]. See Request Body.
Pagination
A list endpoint that returns every row won’t last long in production. Add one decorator:
# locallibrary_config/api.py
from ninja.pagination import paginate


@api.get("/rooms", response=list[RoomOut])
@paginate
def list_rooms(request):
    return Room.objects.all()
The view still returns a plain queryset. @paginate adds limit and offset query parameters, slices the queryset in the database, and wraps the result:
{
    "items": [{"id": 1, "name": "lobby", ...}],
    "count": 3
}
Page-number and cursor pagination, or your own class, are one argument away. See Pagination.
Filtering
Filters are also a schema: a FilterSchema, read from the query string. Each field maps to an ORM lookup:
# locallibrary_config/api.py
from datetime import timedelta
from typing import Annotated

from django.db.models import Q
from django.utils import timezone
from ninja import FilterLookup, FilterSchema, Query

...


class RoomFilter(FilterSchema):
    search: Annotated[str | None, FilterLookup("name__icontains")] = None
    topic: Annotated[str | None, FilterLookup("topic__icontains")] = None
    recent: bool | None = None

    def filter_recent(self, value: bool) -> Q:
        week_ago = timezone.now() - timedelta(days=7)
        return Q(created_at__gte=week_ago) if value else Q(created_at__lt=week_ago)


@api.get("/rooms", response=list[RoomOut])
@paginate
def list_rooms(request, filters: Query[RoomFilter]):
    return filters.filter(Room.objects.order_by("name"))
searchandtopicmap toicontainslookups on the room’s name and topic.recentneeds custom logic, so afilter_recentmethod returns aQobject: rooms created in the last week, or, withrecent=false, the ones before that.- Filters left out of the request are skipped, and everything is validated.
?recent=maybegets a422, not a server error.
Now these all work, and combine with pagination:
/api/rooms?search=lob
/api/rooms?recent=true&topic=books
/api/rooms?recent=true&limit=10&offset=20
See Filtering for combining filters with OR, filtering on related models, and more.
What you have so far
Saved chat messages, plus about 60 lines of code that give you a paginated, filterable, validated and documented CRUD API:
| Method | Path | |
|---|---|---|
GET |
/api/rooms |
list, with search, topic, recent, limit, offset |
POST |
/api/rooms |
create |
GET |
/api/rooms/{room_id} |
detail |
PUT |
/api/rooms/{room_id} |
update |
DELETE |
/api/rooms/{room_id} |
delete |
Right now, though, anyone can create or delete rooms, and the API can’t show or post messages. Next: Auth, Routers & Next Steps.
2.3 - Quick Start Part 3: Auth, Routers & Next Steps
The rooms API works, but it all lives in one file and anyone can change data. On this page you’ll move the endpoints into the chat app, require login for writes, and let signed-in users post messages that show up in the chat page right away.
Move the endpoints into a router
A Router is a group of endpoints that you mount on the API under a prefix, much like Django’s include(). Each app can own its endpoints and the project just wires them together.
First, move the schemas to chat/schemas.py, unchanged: RoomIn, RoomOut, Conflict and RoomFilter. Then chat/api.py gets the endpoints, with @api replaced by @router and /rooms dropped from the paths:
# chat/api.py
from ninja import Router

router = Router(tags=["rooms"])


@router.get("/", response=list[RoomOut])
@paginate
def list_rooms(request, filters: Query[RoomFilter]):
    ...


@router.get("/{room_id}", response=RoomOut)
def get_room(request, room_id: int):
    ...

# ... and the rest
The chat app now has both chat/views.py, with the views for its HTML pages, and chat/api.py, with its API endpoints. They don’t interfere: chat/urls.py routes to the views, and the API routes to the router.
locallibrary_config/api.py is now only wiring. The hello and add endpoints from page 1 were only for practice, so they go too:
# locallibrary_config/api.py
from ninja import NinjaAPI

from chat.api import router as rooms_router

api = NinjaAPI()

api.add_router("/rooms", rooms_router)
The router’s / becomes /api/rooms/ and /{room_id} becomes /api/rooms/{room_id}. Note the trailing slash on the list: from now on, list and create rooms at /api/rooms/. A GET of /api/rooms still works, because Django redirects it to /api/rooms/, but a POST to it fails, because Django can’t redirect a POST. Thanks to tags=["rooms"], the interactive docs now group these endpoints under a rooms heading. Routers can be nested, and each one can carry its own auth, tags and other settings. See Routers.
Messages
The original Quick Start adds a model here for “user X is going to event Y”. Your chat already has its counterpart, “user X said Y in room Z”: the Message model from page 2. All it needs is schemas. Add them to chat/schemas.py, with Message added to its model import, and the room nested inside each message:
# chat/schemas.py
class MessageIn(ModelSchema):
    class Meta:
        model = Message
        fields = ["content"]


class MessageOut(ModelSchema):
    room: RoomOut

    class Meta:
        model = Message
        fields = ["id", "author", "content", "created_at"]
Declaring room: RoomOut tells Django Ninja to serialize the related Room with RoomOut, instead of returning only its id. author isn’t declared, so it comes back the default way for a foreign key: as the user’s id, or null for a message posted by someone who wasn’t logged in.
Require login
Turn on auth for the whole API in locallibrary_config/api.py:
# locallibrary_config/api.py
from ninja import NinjaAPI
from ninja.security import django_auth

from chat.api import router as rooms_router

api = NinjaAPI(auth=django_auth)

api.add_router("/rooms", rooms_router)
Every endpoint now requires a logged-in user, so you have to opt the public ones back out. Here’s the complete chat/api.py:
# chat/api.py
from asgiref.sync import async_to_sync
from channels.layers import get_channel_layer
from django.shortcuts import get_object_or_404
from ninja import Query, Router, Status
from ninja.errors import HttpError
from ninja.pagination import paginate

from .models import Message, Room
from .schemas import Conflict, MessageIn, MessageOut, RoomFilter, RoomIn, RoomOut

router = Router(tags=["rooms"])


@router.get("/", response=list[RoomOut], auth=None)
@paginate
def list_rooms(request, filters: Query[RoomFilter]):
    return filters.filter(Room.objects.order_by("name"))


@router.get("/mine", response=list[MessageOut])
def my_messages(request):
    return Message.objects.filter(author=request.auth).select_related("room")


@router.get("/{room_id}", response=RoomOut, auth=None)
def get_room(request, room_id: int):
    return get_object_or_404(Room, id=room_id)


@router.post("/", response={201: RoomOut, 409: Conflict})
def create_room(request, payload: RoomIn):
    existing = Room.objects.filter(name=payload.name).first()
    if existing:
        return Status(409, {"message": "A room with that name already exists", "existing_id": existing.id})
    return Status(201, Room.objects.create(**payload.dict()))


@router.put("/{room_id}", response=RoomOut)
def update_room(request, room_id: int, payload: RoomIn):
    room = get_object_or_404(Room, id=room_id)
    for attr, value in payload.dict().items():
        setattr(room, attr, value)
    room.save()
    return room


@router.delete("/{room_id}", response={204: None})
def delete_room(request, room_id: int):
    get_object_or_404(Room, id=room_id).delete()


@router.get("/{room_id}/messages", response=list[MessageOut], auth=None)
@paginate
def list_messages(request, room_id: int):
    room = get_object_or_404(Room, id=room_id)
    return room.messages.select_related("room")


@router.post("/{room_id}/messages", response={201: MessageOut})
def post_message(request, room_id: int, payload: MessageIn):
    room = get_object_or_404(Room, id=room_id)
    if not payload.content.strip():
        raise HttpError(400, "Messages can't be blank")
    message = Message.objects.create(room=room, author=request.auth, content=payload.content)
    # Send it to everyone in the room's chat page, the way ChatConsumer.receive does
    async_to_sync(get_channel_layer().group_send)(
        f"chat_{room.name}", {"type": "chat.message", "message": message.content}
    )
    return message
What’s new:
NinjaAPI(auth=django_auth)requires a logged-in Django user for every endpoint, so new endpoints are protected unless you say otherwise.django_authuses the regular Django session, the same one the admin and your catalog’s login pages use.auth=Noneopts the three read endpoints back out, so anyone can browse rooms and read their messages, just as anyone can open a chat page. Auth can be set on the whole API, on a router (Router(auth=...)) or on a single endpoint, and the most specific one wins.request.authis whatever the authenticator returned. Fordjango_auththat’s theUser.my_messageslists the messages you posted, from the chat page while logged in or through the API, each with its room nested inside.HttpError(400, "...")stops the request and returns that status with a JSON{"detail": "..."}body. There’s no need to build error responses by hand.list_messagesreturns the messages oldest first, thanks toMeta.orderingonMessage, and pages them with@paginate.select_related("room")fetches each message’s room in the same query, sinceMessageOutnests it.post_messagesends the new message to the room’s group on the channel layer, exactly likeChatConsumer.receivedoes. EveryChatConsumerin that room receives thechat.messageevent, and itschat_messagemethod sends the message to its browser. The view is synchronous and channel layer methods are asynchronous, so it calls them throughasync_to_sync, like your first, synchronous consumer did in Part 2 of the Channels tutorial. That means Redis must be running forpost_messageto work.
An anonymous request to a protected endpoint gets a 401:
$ curl http://127.0.0.1:8000/api/rooms/mine
{"detail": "Unauthorized"}
To try it out, make sure Redis is running, log in at /admin/ (or at /accounts/login/, from Prep 06), and open /api/docs. Swagger UI reuses your session and sends the CSRF token for you, so you can post a message with Try it out.
In a second tab, open the chat page for the room you’ll post to, such as http://127.0.0.1:8000/chat/lobby/ 🔗. Find its id with GET /api/rooms/?search=lobby. Then, back in the docs, POST /api/rooms/1/messages (with your room’s id) and the body {"content": "hello from the API"}. The message appears in the chat tab right away, and the response has the nested schema:
{
    "room": {
        "id": 1,
        "name": "lobby",
        "topic": "",
        "created_at": "2026-10-19T14:02:11.482Z"
    },
    "id": 7,
    "author": 1,
    "content": "hello from the API",
    "created_at": "2026-10-19T15:21:40.913Z"
}
Your message and user ids will be different. Post {"content": " "} and you get 400 {"detail": "Messages can't be blank"}.
django_auth suits browser clients on the same site. For mobile apps or other servers, use an API key or bearer token instead. It’s a small class with one authenticate() method; see Authentication. Part 4 of our Django Ninja Tutorial builds one.
What you’ve built
In three pages, and without writing any serializers, URL patterns or docs by hand, you have a chat that remembers its messages, and an API with:
- typed, validated path, query and body parameters,
- schemas generated from Django models, including a nested one,
- full CRUD, pagination and filtering,
- session auth with public and protected endpoints,
- proper error responses,
- messages posted through the API that reach the chat page live, and
- interactive OpenAPI docs that always match the code.
Where to go next
Our Django Ninja Tutorial builds a larger project step by step, in your locallibrary next to everything you’ve built so far. The Guide covers each feature in depth. Here’s where to read more about everything used in this Quick Start:
| You used | Read more |
|---|---|
NinjaAPI, urls.py |
NinjaAPI, URLs & Reverse |
@api.get, @api.post, … |
Operations |
name: str, room_id: int |
Query Parameters, Path Parameters |
payload: RoomIn |
Request Body, plus Form Data and File Uploads |
ModelSchema, nested schemas |
ModelSchema, Schemas |
response={201: ...} |
Responses |
@paginate |
Pagination |
FilterSchema |
Filtering |
Router, add_router |
Routers |
auth=django_auth, request.auth |
Authentication, CSRF |
HttpError |
Errors & Exception Handling |
/api/docs |
OpenAPI & Interactive Docs |
async_to_sync, group_send |
Channel Layers in the Channels docs |
Features you haven’t seen yet: async views, throttling, API versioning, custom renderers and a test client.
3 - Django Ninja Tutorial
This tutorial builds one realistic API from start to finish: TaskFlow, a task tracker for teams. Users sign up, create projects, invite members with roles, and track tasks with assignees, labels, statuses, due dates, comments and file attachments. Each part adds a feature to the same codebase and shows the Django Ninja tools that make it work.
What you’ll build
By the end of Part 8, TaskFlow has these endpoints:
| Method | URL | What it does |
|---|---|---|
POST |
/taskflow/api/auth/signup |
Create an account |
POST |
/taskflow/api/auth/token, /taskflow/api/auth/refresh |
Get and refresh JWT access tokens |
GET, POST |
/taskflow/api/projects/ |
List your projects, create one |
GET, PUT, DELETE |
/taskflow/api/projects/{project_id} |
Read, update and delete a project |
POST |
/taskflow/api/projects/{project_id}/labels |
Add a label to a project |
GET, POST |
/taskflow/api/projects/{project_id}/members |
List and add members |
GET, POST |
/taskflow/api/projects/{project_id}/tasks/ |
Filter, search, sort and paginate tasks, create one |
GET, PATCH |
/taskflow/api/projects/{project_id}/tasks/{task_id} |
Read a task, update part of it |
POST |
/taskflow/api/projects/{project_id}/tasks/{task_id}/status |
Move a task through its workflow |
GET, POST |
/taskflow/api/projects/{project_id}/tasks/{task_id}/comments |
List comments with a cursor, add one |
PUT, DELETE |
/taskflow/api/projects/{project_id}/tasks/{task_id}/comments/{comment_id} |
Edit or delete a comment |
GET, POST |
/taskflow/api/projects/{project_id}/tasks/{task_id}/attachments |
List attachments, upload a file |
DELETE |
/taskflow/api/projects/{project_id}/tasks/{task_id}/attachments/{attachment_id} |
Delete an attachment |
Every endpoint except the auth ones needs a token, and users only ever see the projects they’re members of. A second version of the API runs next to the first at /taskflow/api/v2/, and a pytest suite covers the rules that matter.
Before you start
- You know Django: projects, apps, models, migrations and settings. The tutorial doesn’t explain those. It focuses on the Django Ninja parts.
- You’ve done our Django Ninja Quickstart, so
NinjaAPI, schemas and the interactive docs are familiar. That also means you’ve finished preps 01-06 and our Channels tutorial, and you have your locallibrary repository: a uv project withmanage.py,pyproject.toml, anduv.lockat its root, thelocallibrary_configproject package, and thecatalogandchatapps. Every command in this tutorial is run from that root folder. - You have Python 3.12 or newer. The code uses modern type hints such as
int | Noneandlist[int]. Your locallibrary uses Python 3.14.
The only packages TaskFlow needs are Django and Django Ninja, and both are already in your pyproject.toml: Django since Prep 01, and Django Ninja since the Quickstart. You can check:
uv run python -c "import django, ninja; print(django.__version__, ninja.__version__)"
Everything else, including JSON Web Tokens, is written with the standard library. Part 7 adds pytest and pytest-django as development tools. The database is the same SQLite db.sqlite3 your catalog and chat use, and all of TaskFlow’s views are synchronous.
How the parts work
- Each part starts with a What you’ll learn box and takes about 15 minutes to read and type.
- Each part builds on the code of the one before, so work through them in order. Changed files are shown in full, or as excerpts with
...where the rest of the file stays the same. - The example requests and responses are real output from the original tutorial. Your projects, labels, tasks, comments and attachments get new tables, so if you follow along exactly, their ids will match the ones on the pages. Your user ids won’t, because your database already has users. Part 2 explains what to do about that.
- Go deeper links at the end of each section point to the Django Ninja Guide page that covers the feature in full.
The parts
- Project setup & layout: one router per app, schemas from models, and task URLs nested under projects.
- Relations & computed fields: assignees and labels as nested output, computed and annotated fields, and fewer queries.
- Validation & workflows: status and priority choices, field and model validators,
PATCHupdates and status transitions. - Auth & permissions: JWT tokens from scratch, project memberships with roles, and object-level rules for comments.
- Filtering, search, ordering & pagination: a
FilterSchemafor tasks, safe sort orders, and page-number and cursor pagination. - File uploads & forms: multipart uploads with form fields, file validation, media files and absolute URLs.
- Testing: a pytest suite with fixtures and
TestClient, covering validation, permissions, filters and uploads. - OpenAPI polish & versioning: descriptions, examples and deprecations in the docs, and a version 2 next to version 1.
Ready? Start with Part 1: Project setup & layout.
How this copy differs from the original
This is a copy of the official Django Ninja tutorial, changed to match the way we have worked in our fork of the MDN Django Tutorial, our Channels tutorial, and our Django Ninja Quickstart:
- You don’t create a new project. The
projects,tasks, andaccountsapps go into your existing locallibrary repository, next tocatalogandchat. Everywhere the original editstaskflow/settings.pyortaskflow/urls.py, this copy editslocallibrary_config/settings.pyorlocallibrary_config/urls.py, and only adds lines. taskflowis a plain package. In the original,taskflowis the Django project package. Here it’s a small package next tomanage.pythat holds onlytaskflow/api.py, so imports likefrom taskflow.api import apiwork exactly as in the original.- TaskFlow lives at
/taskflow/api/, not/api/. Your Quickstart API already uses/api/. Every TaskFlow URL in this copy starts with/taskflow/api/, and version 2 is at/taskflow/api/v2/. Paths insideTestClientcalls are relative to the API, so they’re the same as in the original. - Each TaskFlow
NinjaAPIsetsurls_namespace=. That keeps TaskFlow’s URL names apart from the Quickstart API’s. Part 8 explains why. - Dependencies are managed with uv.
pip installbecomesuv add(uv add --devfor pytest), and every command is run withuv run. - You never delete
db.sqlite3. The original suggests it in Part 2 so the ids match. Yours holds your catalog and chat data, so this copy looks users up by username where the original uses their ids. - Part 6 adds
media/to your.gitignore. The original assumes it’s already there. - Part 7’s tests use your
test_db.sqlite3file. That’s theTESTdatabase setting you added in Part 4 of the Channels tutorial.
This copy follows the Django Ninja documentation as of 2026-10-19 (Django Ninja 1.7.1), on Django 6.1 and Python 3.14.
The original tutorial is Copyright (c) 2025 Vitaliy Kucheryaviy, and is used under its MIT license.
3.1 - Part 1: Project setup & layout
Over eight parts, you’ll build TaskFlow, a task tracker for teams: projects, members, tasks, labels, comments and file attachments. This first part sets up a project layout that stays tidy as the API grows. Each app gets its own router and schemas, and one small module wires them together.
- How to lay out a multi-app project: one
Routerper app, oneNinjaAPIfor the project - How to mount routers with
add_router()and group them in the docs with tags - How to generate input and output schemas with
ModelSchema - How to nest one app’s endpoints under another app’s URL, with
Path[...]for prefix parameters
Time: about 15 minutes
Create the apps
You don’t create a new project: TaskFlow goes into your existing locallibrary repository, next to catalog and chat. Django and Django Ninja are already in your pyproject.toml from the Django Ninja Quickstart, so there’s nothing to install. From the folder with manage.py, create the two apps:
uv run python manage.py startapp projects
uv run python manage.py startapp tasks
TaskFlow doesn’t use Django’s template views, so you can delete views.py and tests.py from both apps. The tests come back in Part 7, in their own place.
In the original tutorial, taskflow is the name of the Django project package, the folder with settings.py and urls.py. Yours is called locallibrary_config, and you’ll keep it. TaskFlow still gets a taskflow package of its own, though, to hold the module that wires its routers together. It’s a plain Python package, not an app, so create it by hand: a taskflow folder next to manage.py, with an empty __init__.py file inside.
Register the two apps in locallibrary_config/settings.py, at the end of INSTALLED_APPS. 'ninja' is already there from the Quickstart. Don’t remove anything:
# locallibrary_config/settings.py
INSTALLED_APPS = [
    'daphne',
    'django.contrib.admin',
    'django.contrib.auth',
    'django.contrib.contenttypes',
    'django.contrib.sessions',
    'django.contrib.messages',
    'django.contrib.staticfiles',
    'catalog.apps.CatalogConfig',
    'chat',
    'ninja',
    'projects',
    'tasks',
]
'ninja' is optional. With it, runserver serves the Swagger UI assets locally instead of from a CDN.
When this part is done, the new parts of your locallibrary will look like this:
catalog/            # (unchanged)
chat/               # (unchanged)
locallibrary_config/
├── settings.py
└── urls.py         # mounts the TaskFlow API next to the Quickstart's
taskflow/
├── __init__.py
└── api.py          # NinjaAPI: wires the routers together
projects/
├── api.py          # Router with the project endpoints
├── models.py
└── schemas.py
tasks/
├── api.py          # Router with the task endpoints
├── models.py
└── schemas.py
manage.py
The pattern is the same for every app: models in models.py, schemas in schemas.py, endpoints in api.py. The taskflow package holds only the wiring.
Models
A project, and a task that belongs to one:
# projects/models.py
from django.db import models


class Project(models.Model):
    name = models.CharField(max_length=100)
    description = models.TextField()
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.name
# tasks/models.py
from django.db import models

from projects.models import Project


class Task(models.Model):
    project = models.ForeignKey(Project, related_name="tasks", on_delete=models.CASCADE)
    title = models.CharField(max_length=200)
    description = models.TextField(default="")
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.title
$ uv run python manage.py makemigrations
Migrations for 'projects':
  projects/migrations/0001_initial.py
    + Create model Project
Migrations for 'tasks':
  tasks/migrations/0001_initial.py
    + Create model Task
$ uv run python manage.py migrate
Tasks will get assignees, labels, a status and more in later parts. For now, a title is enough.
Schemas
Each app keeps its schemas in schemas.py. As in the Quick Start, there’s an In schema for what clients send and an Out schema for what they get back:
# projects/schemas.py
from ninja import ModelSchema

from .models import Project


class ProjectIn(ModelSchema):
    class Meta:
        model = Project
        fields = ["name", "description"]


class ProjectOut(ModelSchema):
    class Meta:
        model = Project
        fields = ["id", "name", "description", "created_at"]
ProjectIn is generated entirely from the model. Neither name nor description has a default, so both are required.
The task schemas follow the same pattern:
# tasks/schemas.py
from ninja import ModelSchema

from .models import Task


class TaskIn(ModelSchema):
    class Meta:
        model = Task
        fields = ["title", "description"]


class TaskOut(ModelSchema):
    class Meta:
        model = Task
        fields = ["id", "project", "title", "description", "created_at"]
Task.description has default="", so TaskIn makes it optional, with an empty string as the default. TaskIn has no project field. The project comes from the URL, as you’ll see below. In TaskOut, the project foreign key is serialized as the project’s id. Part 2 replaces ids like this with nested objects where that helps.
Go deeper: ModelSchema
The projects router
Each app’s endpoints live on a Router in the app’s api.py. Here’s full CRUD for projects:
# projects/api.py
from django.shortcuts import get_object_or_404
from ninja import Router, Status

from .models import Project
from .schemas import ProjectIn, ProjectOut

router = Router(tags=["projects"])


@router.get("/", response=list[ProjectOut])
def list_projects(request):
    return Project.objects.order_by("id")


@router.post("/", response={201: ProjectOut})
def create_project(request, payload: ProjectIn):
    return Status(201, Project.objects.create(**payload.dict()))


@router.get("/{project_id}", response=ProjectOut)
def get_project(request, project_id: int):
    return get_object_or_404(Project, id=project_id)


@router.put("/{project_id}", response=ProjectOut)
def update_project(request, project_id: int, payload: ProjectIn):
    project = get_object_or_404(Project, id=project_id)
    for attr, value in payload.dict().items():
        setattr(project, attr, value)
    project.save()
    return project


@router.delete("/{project_id}", response={204: None})
def delete_project(request, project_id: int):
    get_object_or_404(Project, id=project_id).delete()
    return Status(204, None)
- The router doesn’t know where it will be mounted. Its paths are relative (
/,/{project_id}), and the prefix is set when the project wires it in. tags=["projects"]applies to every operation on the router. The interactive docs group endpoints by tag, so each app gets its own section.Status(201, ...)picks the status code from the ones declared inresponse=.Status(204, None)sends an empty response.
The Quick Start returned (status, body) tuples. They still work, but they’re deprecated in favor of Status(...), which is what TaskFlow uses throughout.
Wire the routers together
The taskflow/api.py module creates the NinjaAPI and mounts each app’s router under a prefix:
# taskflow/api.py
from ninja import NinjaAPI

api = NinjaAPI(title="TaskFlow API", urls_namespace="taskflow")

api.add_router("/projects", "projects.api.router")
api.add_router("/projects/{project_id}/tasks", "tasks.api.router")
add_router() accepts the router object or its dotted import path. With the string form, taskflow/api.py has no imports from the apps, and each router module is imported only when add_router() runs. As the apps start importing each other’s models, that helps you avoid circular imports.
The original tutorial writes NinjaAPI(title="TaskFlow API"). Your locallibrary already has a NinjaAPI, the one in locallibrary_config/api.py from the Quickstart. Each NinjaAPI registers its URLs under a Django URL namespace, which is api-<version> by default, and both APIs have the default version, 1.0.0. urls_namespace="taskflow" gives TaskFlow its own namespace, so the two APIs don’t get in each other’s way. Part 8 explains namespaces in more detail.
Your locallibrary_config/urls.py already mounts the Quickstart’s API at api/. Mount TaskFlow’s API once, like any other set of views, in the same style as the other blocks in that file. Add this to the end of the file:
# locallibrary_config/urls.py
# (after the existing blocks)
# Mount the TaskFlow API from the Django Ninja Tutorial
from taskflow.api import api as taskflow_api

urlpatterns += [
    path('taskflow/api/', taskflow_api.urls),
]
Both APIs are named api in their own modules, so this import renames TaskFlow’s to taskflow_api. Leave the admin, catalog, chat, redirect, static-files, and Quickstart api/ entries as they are.
The project routes now live at /taskflow/api/projects/ and /taskflow/api/projects/{project_id}. In the original tutorial they’re at /api/projects/. In this copy every TaskFlow URL starts with /taskflow/api/ instead, because /api/ already belongs to your Quickstart API.
Go deeper: The NinjaAPI Instance
Tasks under a project
Tasks always belong to a project, so their URLs sit under it: /taskflow/api/projects/{project_id}/tasks/. The second add_router() call above sets that up. Its prefix contains a {project_id} placeholder, and every operation on the tasks router can read it:
# tasks/api.py
from django.shortcuts import get_object_or_404
from ninja import Path, Router, Status

from projects.models import Project

from .models import Task
from .schemas import TaskIn, TaskOut

router = Router(tags=["tasks"])


@router.get("/", response=list[TaskOut])
def list_tasks(request, project_id: Path[int]):
    project = get_object_or_404(Project, id=project_id)
    return project.tasks.order_by("id")


@router.post("/", response={201: TaskOut})
def create_task(request, project_id: Path[int], payload: TaskIn):
    project = get_object_or_404(Project, id=project_id)
    return Status(201, Task.objects.create(project=project, **payload.dict()))


@router.get("/{task_id}", response=TaskOut)
def get_task(request, project_id: Path[int], task_id: int):
    return get_object_or_404(Task, id=task_id, project_id=project_id)
project_id: Path[int]reads the value from the URL prefix and converts it to anint.task_idis part of the operation’s own path (/{task_id}), so a plainintis enough, likeproject_idin the projects router.create_tasktakes the project from the URL, not from the body. A client can’t create a task in one project by posting it to another project’s URL.get_taskfilters on both ids, so/projects/3/tasks/2returns 404 when task 2 belongs to project 1.
Django Ninja only treats an argument as a path parameter automatically if it appears in the operation’s own path. It doesn’t look at the router’s prefix. If you write project_id: int in list_tasks, it becomes a required query parameter. The docs then ask for ?project_id=, and the {project_id} in the URL is ignored. GET /taskflow/api/projects/1/tasks/ fails:
{
    "detail": [
        {
            "type": "missing",
            "loc": ["query", "project_id"],
            "msg": "Field required"
        }
    ]
}
With Path[int], the value is read from the URL where it belongs.
Why not a nested router?
You could get the same URLs by nesting routers inside the projects app:
router.add_router("/{project_id}/tasks", tasks_router)
That works, but the projects app would then have to import the tasks app. Mounting both routers in taskflow/api.py keeps each app self-contained, and all the URL structure is in one file. Nested routers make more sense for sub-routers of a single app.
Go deeper: Path Parameters, Routers
Try it
uv run python manage.py runserver
The quickest way to send the requests below is the interactive docs at http://127.0.0.1:8000/taskflow/api/docs: click an endpoint, then Try it out. (You’ll see more of that page at the end of this section.)
Create a project with POST /taskflow/api/projects/. The body is {"name": "Website redesign", "description": "New marketing site"}, and the response is 201:
{
    "id": 1,
    "name": "Website redesign",
    "description": "New marketing site",
    "created_at": "2026-09-29T09:30:27.635Z"
}
A second project, {"name": "Mobile app", "description": "iOS and Android"}, gets id 2:
{
    "id": 2,
    "name": "Mobile app",
    "description": "iOS and Android",
    "created_at": "2026-09-29T09:30:27.636Z"
}
Leave out the required fields, as in {}, and you get a 422 that points at each missing one:
{
    "detail": [
        {
            "type": "missing",
            "loc": ["body", "payload", "name"],
            "msg": "Field required"
        },
        {
            "type": "missing",
            "loc": ["body", "payload", "description"],
            "msg": "Field required"
        }
    ]
}
Now add two tasks to project 1. POST /taskflow/api/projects/1/tasks/ with {"title": "Draft the sitemap"}, then again with {"title": "Pick a color palette", "description": "Two options"}. GET /taskflow/api/projects/1/tasks/ lists them:
[
    {
        "id": 1,
        "project": 1,
        "title": "Draft the sitemap",
        "description": "",
        "created_at": "2026-09-29T09:30:27.647Z"
    },
    {
        "id": 2,
        "project": 1,
        "title": "Pick a color palette",
        "description": "Two options",
        "created_at": "2026-09-29T09:30:27.649Z"
    }
]
Unknown ids, whether a missing project or a task under the wrong project, return a 404. GET /taskflow/api/projects/3/tasks/2:
{
    "detail": "Not Found: No Task matches the given query."
}
The message after Not Found only appears with DEBUG = True. In production, the body is just {"detail": "Not Found"}.
Open http://127.0.0.1:8000/taskflow/api/docs. The page title is TaskFlow API, and the endpoints are grouped under projects and tasks. Here’s the full list, with where each parameter comes from:
GET    /taskflow/api/projects/                                    ['projects']
POST   /taskflow/api/projects/                                    ['projects']
GET    /taskflow/api/projects/{project_id}                        ['projects']  project_id (path)
PUT    /taskflow/api/projects/{project_id}                        ['projects']  project_id (path)
DELETE /taskflow/api/projects/{project_id}                        ['projects']  project_id (path)
GET    /taskflow/api/projects/{project_id}/tasks/                 ['tasks']  project_id (path)
POST   /taskflow/api/projects/{project_id}/tasks/                 ['tasks']  project_id (path)
GET    /taskflow/api/projects/{project_id}/tasks/{task_id}        ['tasks']  project_id (path), task_id (path)
Go deeper: OpenAPI & Interactive Docs, Errors & Exception Handling
Recap
- Each app owns a
Routerinapi.pyand its schemas inschemas.py.taskflow/api.pyonly creates theNinjaAPIand mounts routers. add_router()sets the prefix and accepts a dotted path, which helps avoid circular imports.Router(tags=[...])groups each app’s endpoints in the docs.ModelSchemagenerates schemas from models. A model field without a default is required in the schema, anddefault=""makes it optional.- A router mounted under
/projects/{project_id}/tasksreads the prefix parameter withproject_id: Path[int]. WithoutPath, it would become a query parameter. Status(code, body)picks the response status code.
Next
Tasks are still flat records. In Part 2: Relations & computed fields, you’ll add assignees and labels, return nested objects, compute task counts, and keep the number of queries under control.
3.2 - Part 2: Relations & computed fields
In Part 1, a task was a flat record whose project came back as a bare id. Real tasks have an assignee and labels, and clients want to see who and what those are without making a request for each one. In this part you’ll add those relations, return them as nested objects, compute a few values the model doesn’t store, and check how many queries each list costs.
- How to return related objects as nested schemas, while clients send plain ids
- How to set a many-to-many relation after creating an object
- How to compute a field with a
resolve_<field>static method - How to read ORM annotations and reverse relations into a schema
- How to spot N+1 queries and fix them with
select_relatedandprefetch_related
Time: about 15 minutes
Assignees and labels
Labels belong to a project, so each project has its own set, like “bug” or “design”. The Label model goes in the projects app:
# projects/models.py
from django.db import models


class Project(models.Model):
    name = models.CharField(max_length=100)
    description = models.TextField()
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.name


class Label(models.Model):
    project = models.ForeignKey(Project, related_name="labels", on_delete=models.CASCADE)
    name = models.CharField(max_length=50)
    color = models.CharField(max_length=7, default="#808080")

    class Meta:
        ordering = ["name"]

    def __str__(self):
        return self.name
A task gets an optional assignee, which is a Django user, and any number of labels:
# tasks/models.py
from django.conf import settings
from django.db import models

from projects.models import Label, Project


class Task(models.Model):
    project = models.ForeignKey(Project, related_name="tasks", on_delete=models.CASCADE)
    title = models.CharField(max_length=200)
    description = models.TextField(default="")
    assignee = models.ForeignKey(
        settings.AUTH_USER_MODEL,
        null=True,
        blank=True,
        related_name="assigned_tasks",
        on_delete=models.SET_NULL,
    )
    labels = models.ManyToManyField(Label, blank=True, related_name="tasks")
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.title
$ uv run python manage.py makemigrations
Migrations for 'projects':
  projects/migrations/0002_label.py
    + Create model Label
Migrations for 'tasks':
  tasks/migrations/0002_task_assignee_task_labels.py
    + Add field assignee to task
    + Add field labels to task
$ uv run python manage.py migrate
TaskFlow has no user endpoints yet; sign-up and login come in Part 4. For now, create two users in the shell. Django’s shell imports your models, User included, automatically:
$ uv run python manage.py shell
>>> User.objects.create_user("alice", first_name="Alice", last_name="Martin")
<User: alice>
>>> User.objects.create_user("bob")
<User: bob>
>>> User.objects.get(username="alice").id, User.objects.get(username="bob").id
(4, 5)
The original tutorial suggests deleting db.sqlite3 so that your ids match the ones on the pages. Don’t. That file also holds your superuser, the users you made in Prep 06, every book, author, and genre in your catalog, and your chat rooms and messages.
You don’t need to delete it, either. Project, Label, Task, and the models from later parts get brand-new tables, so their ids start at 1 and match the pages as long as you follow along exactly. Only the user ids are different. In the original, alice is user 1 and bob is user 2 (and Carol, in Part 4, is user 3). Your locallibrary already has users, so yours come after them. The last line above prints them; yours may not be 4 and 5.
Write down alice’s and bob’s ids. Wherever this tutorial sends a user id in a request, use yours. Wherever it shows a user id in a response, expect yours.
Nested output, ids on input
By default, ModelSchema turns a foreign key into the related object’s id and a many-to-many field into a list of ids. That’s the right shape for input, since a client picks an assignee by id. For output, clients usually want the name as well, so they don’t have to look it up. The task schemas therefore use ids going in and nested objects coming out:
# tasks/schemas.py
from django.contrib.auth.models import User
from ninja import ModelSchema

from projects.schemas import LabelOut

from .models import Task


class UserOut(ModelSchema):
    display_name: str

    class Meta:
        model = User
        fields = ["id", "username"]

    @staticmethod
    def resolve_display_name(user):
        return user.get_full_name() or user.username


class TaskIn(ModelSchema):
    assignee_id: int | None = None
    label_ids: list[int] = []

    class Meta:
        model = Task
        fields = ["title", "description"]


class TaskOut(ModelSchema):
    assignee: UserOut | None
    labels: list[LabelOut]

    class Meta:
        model = Task
        fields = ["id", "project", "title", "description", "created_at"]
TaskOutdeclaresassigneeandlabelswith other schemas as their types. Django Ninja readstask.assigneeand serializes it withUserOut, or asnullwhen it’s empty. It readstask.labels, a related manager, and turns it into a list ofLabelOut. You don’t need to call.all().TaskIntakesassignee_idandlabel_ids, both optional.assignee_idmatches the column name Django uses for the foreign key, so it can go straight intoTask.objects.create().display_nameisn’t a field onUser.resolve_display_namecomputes it from the object being serialized: the full name if there is one, or else the username. A resolver must be a@staticmethodnamedresolve_<field>.
Fields you declare on a ModelSchema come first in the output, before the fields from Meta.fields. That’s why assignee and labels appear before id in the responses below.
LabelOut lives next to its model in projects/schemas.py, with a LabelIn for creating labels:
# projects/schemas.py
from ninja import ModelSchema

from .models import Label, Project


class LabelIn(ModelSchema):
    class Meta:
        model = Label
        fields = ["name", "color"]


class LabelOut(ModelSchema):
    class Meta:
        model = Label
        fields = ["id", "name", "color"]


class ProjectIn(ModelSchema):
    class Meta:
        model = Project
        fields = ["name", "description"]


class ProjectOut(ModelSchema):
    labels: list[LabelOut]
    task_count: int
    unassigned_task_count: int

    class Meta:
        model = Project
        fields = ["id", "name", "description", "created_at"]
color has a model default, so LabelIn makes it optional. The new ProjectOut fields are covered in Computed project fields below.
Go deeper: Schemas, ModelSchema
Creating tasks with relations
The ids in TaskIn come from the client, so check them before you use them. An unknown assignee_id would otherwise fail inside the database with an IntegrityError, and a label from another project doesn’t belong on this task:
# tasks/api.py
from django.contrib.auth.models import User
from django.shortcuts import get_object_or_404
from ninja import Path, Router, Status
from ninja.errors import HttpError

from projects.models import Project

from .models import Task
from .schemas import TaskIn, TaskOut

router = Router(tags=["tasks"])


def check_relations(project, payload):
    if payload.assignee_id is not None and not User.objects.filter(id=payload.assignee_id).exists():
        raise HttpError(400, f"User {payload.assignee_id} does not exist")
    labels = list(project.labels.filter(id__in=payload.label_ids))
    if len(labels) != len(set(payload.label_ids)):
        raise HttpError(400, "Unknown label id for this project")
    return labels


@router.get("/", response=list[TaskOut])
def list_tasks(request, project_id: Path[int]):
    project = get_object_or_404(Project, id=project_id)
    return project.tasks.select_related("assignee").prefetch_related("labels").order_by("id")


@router.post("/", response={201: TaskOut})
def create_task(request, project_id: Path[int], payload: TaskIn):
    project = get_object_or_404(Project, id=project_id)
    labels = check_relations(project, payload)
    task = Task.objects.create(project=project, **payload.dict(exclude={"label_ids"}))
    task.labels.set(labels)
    return Status(201, task)


@router.get("/{task_id}", response=TaskOut)
def get_task(request, project_id: Path[int], task_id: int):
    return get_object_or_404(Task, id=task_id, project_id=project_id)
check_relationsreturns theLabelobjects. It looks them up throughproject.labels, the reverse relation, so labels from other projects are never found.HttpError(400, ...)stops the request with a{"detail": ...}body. Part 3 covers validation and errors in more depth.- A many-to-many relation needs a saved row, so it’s set after
create().payload.dict(exclude={"label_ids"})leaves out the one key the model doesn’t accept. - The
select_relatedandprefetch_relatedcalls inlist_tasksare explained in Counting queries.
Labels are created on their project with POST /taskflow/api/projects/{project_id}/labels. That endpoint is create_label at the end of projects/api.py, shown in full in the next section.
Try it
Create a project with POST /taskflow/api/projects/ and {"name": "Website redesign", "description": "New marketing site"}, then add two labels to it: POST /taskflow/api/projects/1/labels with {"name": "bug", "color": "#d73a4a"}, then with {"name": "design"}. The second label gets the default color:
{
    "id": 2,
    "name": "design",
    "color": "#808080"
}
Now create a task. POST /taskflow/api/projects/1/tasks/ with {"title": "Draft the sitemap", "assignee_id": 1, "label_ids": [2]}, using alice’s id in place of 1, returns 201, with ids in and objects out:
{
    "assignee": {
        "display_name": "Alice Martin",
        "id": 1,
        "username": "alice"
    },
    "labels": [
        {
            "id": 2,
            "name": "design",
            "color": "#808080"
        }
    ],
    "id": 1,
    "project": 1,
    "title": "Draft the sitemap",
    "description": "",
    "created_at": "2026-09-28T10:45:47.345Z"
}
Add two more: {"title": "Fix broken footer links", "assignee_id": 2, "label_ids": [1, 2]}, with bob’s id in place of 2, and {"title": "Pick a color palette"} with neither field. The last one comes back with "assignee": null and "labels": []. Bob has no full name, so his display_name is "bob".
Bad ids get a 400. {"title": "Ghost", "assignee_id": 42} returns this, as long as none of your users has id 42:
{
    "detail": "User 42 does not exist"
}
To see the label check, create a second project, {"name": "Mobile app", "description": "iOS and Android"}, and give it a label, {"name": "ios"}. That label gets id 3. Back on project 1, {"title": "Wrong label", "label_ids": [3]} returns:
{
    "detail": "Unknown label id for this project"
}
Go deeper: Errors & Exception Handling
Computed project fields
A project list is more useful with a count of tasks next to each project. You could compute that in a resolver with project.tasks.count(), but that runs one query per project. Let the database compute it for the whole list with annotate():
# projects/api.py
from django.db.models import Count, Q
from django.shortcuts import get_object_or_404
from ninja import Router, Status

from .models import Project
from .schemas import LabelIn, LabelOut, ProjectIn, ProjectOut

router = Router(tags=["projects"])


def projects_with_counts():
    return Project.objects.annotate(
        task_count=Count("tasks"),
        unassigned_task_count=Count("tasks", filter=Q(tasks__assignee=None)),
    ).prefetch_related("labels")


@router.get("/", response=list[ProjectOut])
def list_projects(request):
    return projects_with_counts().order_by("id")


@router.post("/", response={201: ProjectOut})
def create_project(request, payload: ProjectIn):
    project = Project.objects.create(**payload.dict())
    return Status(201, projects_with_counts().get(id=project.id))


@router.get("/{project_id}", response=ProjectOut)
def get_project(request, project_id: int):
    return get_object_or_404(projects_with_counts(), id=project_id)


@router.put("/{project_id}", response=ProjectOut)
def update_project(request, project_id: int, payload: ProjectIn):
    project = get_object_or_404(projects_with_counts(), id=project_id)
    for attr, value in payload.dict().items():
        setattr(project, attr, value)
    project.save()
    return project


@router.delete("/{project_id}", response={204: None})
def delete_project(request, project_id: int):
    get_object_or_404(Project, id=project_id).delete()
    return Status(204, None)


@router.post("/{project_id}/labels", response={201: LabelOut})
def create_label(request, project_id: int, payload: LabelIn):
    project = get_object_or_404(Project, id=project_id)
    return Status(201, project.labels.create(**payload.dict()))
- An annotation becomes an attribute on each instance, so
ProjectOutreadstask_countandunassigned_task_countlike any other field. The schema doesn’t need to know they came fromannotate(). labels: list[LabelOut]onProjectOutreads the reverse relationproject.labels.ModelSchemanever includes reverse relations on its own, so you declare them yourself.- Every view that returns a
ProjectOutgets its project fromprojects_with_counts().create_projectfetches the new project again for that reason, andupdate_projectkeeps the annotated instance it loaded. create_labelcreates the label throughproject.labels, which sets itsprojectfor you.
If a view returns a plain Project, you don’t get a silent 0. The response fails validation with Field required for task_count and unassigned_task_count, and the client gets a server error. It’s easy to spot in development.
GET /taskflow/api/projects/1, with the three tasks from above:
{
    "labels": [
        {
            "id": 1,
            "name": "bug",
            "color": "#d73a4a"
        },
        {
            "id": 2,
            "name": "design",
            "color": "#808080"
        }
    ],
    "task_count": 3,
    "unassigned_task_count": 1,
    "id": 1,
    "name": "Website redesign",
    "description": "New marketing site",
    "created_at": "2026-09-28T10:45:47.335Z"
}
Go deeper: Schemas, ModelSchema
Counting queries
Nested output is convenient, but each nested object comes from somewhere. In Part 1, list_tasks returned project.tasks.order_by("id"). With the new TaskOut, every task in that list costs one extra query for its assignee and one for its labels. This is the N+1 problem.
To see it, temporarily change the last line of list_tasks back to Part 1’s return project.tasks.order_by("id"). Then count the queries from the shell. ninja.testing.TestClient calls the API directly, without a running server. Part 7 uses it for the test suite.
$ uv run python manage.py shell
>>> from django.db import connection
>>> from django.test.utils import CaptureQueriesContext
>>> from ninja.testing import TestClient
>>> from taskflow.api import api
>>> client = TestClient(api)
>>> with CaptureQueriesContext(connection) as ctx:
...     response = client.get("/projects/1/tasks/")
...
>>> len(ctx.captured_queries)
7
That’s 7 queries for three tasks with Part 1’s queryset: one for the project, one for the tasks, two for the assignees (the third task has none), and three for the labels. Every extra task adds up to two more, so ten tasks take 21 or 22. The fix is to fetch the related rows up front, which is the version of list_tasks you typed earlier:
# tasks/api.py
@router.get("/", response=list[TaskOut])
def list_tasks(request, project_id: Path[int]):
    project = get_object_or_404(Project, id=project_id)
    return project.tasks.select_related("assignee").prefetch_related("labels").order_by("id")
select_related("assignee")joins the user table into the tasks query. Use it for foreign keys.prefetch_related("labels")loads the labels of all the listed tasks in one extra query. Use it for many-to-many and reverse relations.
Restore that line, open a new shell, and run the same code again:
>>> len(ctx.captured_queries)
3
It’s 3 queries, for three tasks or ten: the project, the tasks joined with their assignees, and the labels. The projects list works the same way. projects_with_counts() computes both counts in the main query and adds .prefetch_related("labels"), so GET /taskflow/api/projects/ takes 2 queries however many projects there are.
A single get_task response has no N+1 problem, so it uses a plain get_object_or_404. Optimize the lists first. They’re where the query count grows with the data.
Recap
- Declare a related field with another schema as its type (
assignee: UserOut | None,labels: list[LabelOut]) to nest it in the output. Related managers are turned into lists for you. - Accept plain ids on input (
assignee_id,label_ids), check them, and set many-to-many relations aftercreate(). - A
@staticmethodnamedresolve_<field>computes a field in Python. Anannotate()in the queryset computes it in the database, and the schema reads it like any other attribute. - Reverse relations such as
project.labelsare never generated byModelSchema. Declare them on the schema. - Nested output can cause N+1 queries. Use
select_relatedfor foreign keys andprefetch_relatedfor many-to-many and reverse relations, and count queries withCaptureQueriesContext.
Next
Tasks still have no status, and nothing stops a client from sending a blank title. In Part 3: Validation & workflows, you’ll add status and priority choices, field and model validators, and a status transition endpoint.
3.3 - Part 3: Validation & workflows
So far, TaskFlow accepts almost anything a client sends: a title made of spaces is a valid task, and there’s no way to say a task is finished. In this part you’ll give tasks a status, a priority and a due date, validate input with field and model validators, add a PATCH endpoint for partial updates, and move tasks through a small workflow that rejects invalid status changes.
- How Django
choicesbecome enums in your schemas and in OpenAPI - How to write field validators and model validators, with your own error messages
- What a
422validation error looks like, and how to read it - How to accept partial updates with
PatchDict, and what it changes about validation - How to reject an invalid state change with
HttpError
Time: about 15 minutes
Status, priority and due date
Status and priority are fixed sets of values, so they’re Django choices. The allowed status changes go right next to them:
# tasks/models.py
from django.conf import settings
from django.db import models

from projects.models import Label, Project


class TaskStatus(models.TextChoices):
    TODO = "todo"
    IN_PROGRESS = "in_progress"
    DONE = "done"


class Priority(models.IntegerChoices):
    """1 = low, 2 = medium, 3 = high, 4 = urgent"""

    LOW = 1
    MEDIUM = 2
    HIGH = 3
    URGENT = 4


# The statuses a task may move to from each status
ALLOWED_TRANSITIONS = {
    TaskStatus.TODO: {TaskStatus.IN_PROGRESS},
    TaskStatus.IN_PROGRESS: {TaskStatus.TODO, TaskStatus.DONE},
    TaskStatus.DONE: {TaskStatus.IN_PROGRESS},
}


class Task(models.Model):
    project = models.ForeignKey(Project, related_name="tasks", on_delete=models.CASCADE)
    title = models.CharField(max_length=200)
    description = models.TextField(default="")
    status = models.CharField(max_length=20, choices=TaskStatus, default=TaskStatus.TODO)
    priority = models.IntegerField(choices=Priority, default=Priority.MEDIUM)
    due_date = models.DateField(null=True, blank=True)
    assignee = models.ForeignKey(
        settings.AUTH_USER_MODEL,
        null=True,
        blank=True,
        related_name="assigned_tasks",
        on_delete=models.SET_NULL,
    )
    labels = models.ManyToManyField(Label, blank=True, related_name="tasks")
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.title
- Priority is an integer, so that “most urgent first” is a plain
order_by("-priority")later on. ALLOWED_TRANSITIONSis the whole workflow: fromtodoyou can only start a task, and adonetask can only be reopened asin_progress. You’ll use it in Status transitions.
$ uv run python manage.py makemigrations
Migrations for 'tasks':
  tasks/migrations/0003_task_due_date_task_priority_task_status.py
    + Add field due_date to task
    + Add field priority to task
    + Add field status to task
$ uv run python manage.py migrate
The tasks you created in Part 2 get the model defaults. GET /taskflow/api/projects/1/tasks/1 now includes the new fields:
{
    "assignee": {
        "display_name": "Alice Martin",
        "id": 1,
        "username": "alice"
    },
    "labels": [
        {
            "id": 2,
            "name": "design",
            "color": "#808080"
        }
    ],
    "status": "todo",
    "priority": 2,
    "id": 1,
    "project": 1,
    "title": "Draft the sitemap",
    "description": "",
    "due_date": null,
    "created_at": "2026-09-28T10:53:40.574Z"
}
Validating input
ModelSchema doesn’t look at choices: a status field from Meta.fields is just a str, and priority is just an int. To have the schema accept only valid values, declare the field with the choices class as its type. TextChoices and IntegerChoices are Python enums, which Pydantic validates and OpenAPI describes.
The rest of the rules go into validators. Here’s the new tasks/schemas.py:
# tasks/schemas.py
from django.contrib.auth.models import User
from ninja import ModelSchema, Schema
from pydantic import field_validator, model_validator
from pydantic_core import PydanticCustomError

from projects.schemas import LabelOut

from .models import Priority, Task, TaskStatus


class UserOut(ModelSchema):
    display_name: str

    class Meta:
        model = User
        fields = ["id", "username"]

    @staticmethod
    def resolve_display_name(user):
        return user.get_full_name() or user.username


class TaskUpdate(ModelSchema):
    priority: Priority = Priority.MEDIUM

    class Meta:
        model = Task
        fields = ["title", "description", "priority", "due_date"]

    @field_validator("title", "description", "priority", check_fields=False)
    @classmethod
    def not_null(cls, value):
        if value is None:
            raise PydanticCustomError("not_null", "This field can't be null")
        return value

    @field_validator("title", check_fields=False)
    @classmethod
    def title_not_blank(cls, value: str) -> str:
        value = value.strip()
        if not value:
            raise PydanticCustomError("blank", "Title can't be blank")
        return value


class TaskIn(TaskUpdate):
    assignee_id: int | None = None
    label_ids: list[int] = []

    @model_validator(mode="after")
    def urgent_needs_due_date(self):
        if self.priority == Priority.URGENT and self.due_date is None:
            raise ValueError("Urgent tasks need a due date")
        return self


class StatusIn(Schema):
    status: TaskStatus


class TaskOut(ModelSchema):
    assignee: UserOut | None
    labels: list[LabelOut]
    status: TaskStatus
    priority: Priority

    class Meta:
        model = Task
        fields = ["id", "project", "title", "description", "due_date", "created_at"]
TaskUpdateholds the fields a client can edit: title, description, priority and due date.TaskInextends it with the fields you only set on create. AModelSchemasubclass inheritsMeta, fields and validators, soTaskInhas everythingTaskUpdatehas.statusisn’t in either input schema. New tasks always start astodo, and the only way to change the status is the transition endpoint below.title_not_blankis a field validator. It runs after the type check, gets the value, and returns what should be stored, here the stripped title.not_nulldoes nothing on a normal request, because the type check already rejectsnullfor these fields. It exists for thePATCHendpoint, explained in the next section.urgent_needs_due_dateis a model validator. Withmode="after"it runs once every field is valid, so it can compare fields. It returnsself.StatusInis the body of the transition endpoint.TaskOutdeclaresstatusandprioritywith their enums so the response schema lists the allowed values too.
Pydantic checks that a validator’s field names exist when the class is created. ModelSchema adds the Meta.fields afterwards, so without check_fields=False a validator for title fails with PydanticUserError: Decorators defined with incorrect fields. Fields you declare yourself, such as priority, don’t need it.
Error messages
A validator reports a problem by raising an exception, and Django Ninja turns it into a 422 response. What the client sees depends on what you raise:
ValueError("...")gives the typevalue_error, and Pydantic addsValue error,before your message.PydanticCustomError(type, message)uses your type and your message exactly as written. Clients can match on the type.
Try it
POST /taskflow/api/projects/1/tasks/ with {"title": " Write launch announcement ", "priority": 3, "due_date": "2026-10-15"} returns 201, with the title stripped:
{
    "assignee": null,
    "labels": [],
    "status": "todo",
    "priority": 3,
    "id": 4,
    "project": 1,
    "title": "Write launch announcement",
    "description": "",
    "due_date": "2026-10-15",
    "created_at": "2026-09-28T10:53:40.592Z"
}
Invalid input gets a 422 with a list of errors. When several fields are wrong, you get all of them in one response. {"title": "", "priority": 5, "due_date": "next friday"} returns:
{
    "detail": [
        {
            "type": "enum",
            "loc": [
                "body",
                "payload",
                "priority"
            ],
            "msg": "Input should be 1, 2, 3 or 4",
            "ctx": {
                "expected": "1, 2, 3 or 4"
            }
        },
        {
            "type": "blank",
            "loc": [
                "body",
                "payload",
                "title"
            ],
            "msg": "Title can't be blank"
        },
        {
            "type": "date_from_datetime_parsing",
            "loc": [
                "body",
                "payload",
                "due_date"
            ],
            "msg": "Input should be a valid date or datetime, invalid character in year",
            "ctx": {
                "error": "invalid character in year"
            }
        }
    ]
}
loc is the path to each bad value: the request body, the view argument payload, then the field. type and msg of the title error come from the PydanticCustomError in title_not_blank.
The model validator runs only when every field is valid. {"title": "Fix checkout bug", "priority": 4} has no due date, so it gets an error for the whole payload, with the Value error, prefix that comes from ValueError:
{
    "detail": [
        {
            "type": "value_error",
            "loc": [
                "body",
                "payload"
            ],
            "msg": "Value error, Urgent tasks need a due date",
            "ctx": {
                "error": "Urgent tasks need a due date"
            }
        }
    ]
}
None of these requests reach the view, so nothing is saved.
In the interactive docs at /taskflow/api/docs, the schemas now include both enums. Priority uses the class docstring as its description, which is the easiest way to explain what the numbers mean:
{
    "description": "1 = low, 2 = medium, 3 = high, 4 = urgent",
    "enum": [
        1,
        2,
        3,
        4
    ],
    "title": "Priority",
    "type": "integer"
}
Go deeper: Schemas, Errors & Exception Handling
Partial updates with PATCH
Part 1’s PUT for projects replaces every field. For tasks, a client usually changes one thing at a time, such as the priority. That’s a PATCH, and PatchDict handles it. Here’s the full tasks/api.py with the two new endpoints:
# tasks/api.py
from django.contrib.auth.models import User
from django.shortcuts import get_object_or_404
from ninja import PatchDict, Path, Router, Status
from ninja.errors import HttpError

from projects.models import Project

from .models import ALLOWED_TRANSITIONS, Priority, Task
from .schemas import StatusIn, TaskIn, TaskOut, TaskUpdate

router = Router(tags=["tasks"])


def check_relations(project, payload):
    if payload.assignee_id is not None and not User.objects.filter(id=payload.assignee_id).exists():
        raise HttpError(400, f"User {payload.assignee_id} does not exist")
    labels = list(project.labels.filter(id__in=payload.label_ids))
    if len(labels) != len(set(payload.label_ids)):
        raise HttpError(400, "Unknown label id for this project")
    return labels


@router.get("/", response=list[TaskOut])
def list_tasks(request, project_id: Path[int]):
    project = get_object_or_404(Project, id=project_id)
    return project.tasks.select_related("assignee").prefetch_related("labels").order_by("id")


@router.post("/", response={201: TaskOut})
def create_task(request, project_id: Path[int], payload: TaskIn):
    project = get_object_or_404(Project, id=project_id)
    labels = check_relations(project, payload)
    task = Task.objects.create(project=project, **payload.dict(exclude={"label_ids"}))
    task.labels.set(labels)
    return Status(201, task)


@router.get("/{task_id}", response=TaskOut)
def get_task(request, project_id: Path[int], task_id: int):
    return get_object_or_404(Task, id=task_id, project_id=project_id)


@router.patch("/{task_id}", response=TaskOut)
def update_task(request, project_id: Path[int], task_id: int, payload: PatchDict[TaskUpdate]):
    task = get_object_or_404(Task, id=task_id, project_id=project_id)
    for attr, value in payload.items():
        setattr(task, attr, value)
    if task.priority == Priority.URGENT and task.due_date is None:
        raise HttpError(400, "Urgent tasks need a due date")
    task.save()
    return task


@router.post("/{task_id}/status", response=TaskOut)
def change_status(request, project_id: Path[int], task_id: int, payload: StatusIn):
    task = get_object_or_404(Task, id=task_id, project_id=project_id)
    if payload.status not in ALLOWED_TRANSITIONS[task.status]:
        raise HttpError(409, f"Can't move a task from {task.status} to {payload.status}")
    task.status = payload.status
    task.save()
    return task
PatchDict[TaskUpdate]makes every field ofTaskUpdateoptional and gives the view a plaindictwith only the keys the client sent. The loop copies those onto the task and leaves the rest alone.- The field validators still run on the values that were sent, so a blank title is rejected on
PATCHas well. create_taskdidn’t change.payload.dict()now includespriorityanddue_date, andTask.objects.create()accepts them as they are.
PatchDict makes every field optional by also allowing null. For due_date, null is useful: it clears the date. For title, description and priority, the database column can’t hold NULL, and a null would reach task.save() and fail with an IntegrityError. The not_null validator stops it first. PATCH /taskflow/api/projects/1/tasks/4 with {"title": null} returns:
{
    "detail": [
        {
            "type": "not_null",
            "loc": [
                "body",
                "payload",
                "title"
            ],
            "msg": "This field can't be null"
        }
    ]
}
Rules that need the stored data
PATCH uses TaskUpdate, not TaskIn, so the urgent rule doesn’t run as a model validator there. It couldn’t work on a partial payload anyway: a validator only sees the request body, and {"priority": 4} doesn’t include the due date the task already has. So update_task checks the rule on the task itself, after the changes are applied and before anything is saved.
Task 4 has a due date, so PATCH /taskflow/api/projects/1/tasks/4 with {"priority": 4} returns 200 with "priority": 4, and the title and due date unchanged.
Clearing the due date of that urgent task with {"due_date": null} returns 400, and the task keeps its date:
{
    "detail": "Urgent tasks need a due date"
}
This error comes from HttpError, so it has the simple {"detail": "..."} shape rather than a list. Use validators for what the request alone can decide, and checks in the view for anything that depends on the database.
Go deeper: Request Body, ModelSchema
Status transitions
A status isn’t just another field to PATCH. Whether done is a valid new status depends on the current one. That’s why status has its own endpoint, POST /taskflow/api/projects/{project_id}/tasks/{task_id}/status:
# tasks/api.py
@router.post("/{task_id}/status", response=TaskOut)
def change_status(request, project_id: Path[int], task_id: int, payload: StatusIn):
    task = get_object_or_404(Task, id=task_id, project_id=project_id)
    if payload.status not in ALLOWED_TRANSITIONS[task.status]:
        raise HttpError(409, f"Can't move a task from {task.status} to {payload.status}")
    task.status = payload.status
    task.save()
    return task
StatusInmakes sure the value is one of the three statuses. The view only has to decide whether this change is allowed.ALLOWED_TRANSITIONS[task.status]is the set of statuses the task can move to.task.statusis a plain string when it’s loaded from the database, and it still finds theTaskStatuskey, because aTextChoicesmember compares and hashes like its string value.409 Conflictsays the request was well formed but clashes with the current state of the task. The message tells the client which move was refused.
Task 4 is still todo, so {"status": "done"} is refused:
{
    "detail": "Can't move a task from todo to done"
}
Starting it first with {"status": "in_progress"} returns 200 and the task with "status": "in_progress". After that, {"status": "done"} works. A status that doesn’t exist never reaches the view. {"status": "archived"} returns a 422 from the enum:
{
    "detail": [
        {
            "type": "enum",
            "loc": [
                "body",
                "payload",
                "status"
            ],
            "msg": "Input should be 'todo', 'in_progress' or 'done'",
            "ctx": {
                "expected": "'todo', 'in_progress' or 'done'"
            }
        }
    ]
}
Go deeper: Errors & Exception Handling
Recap
- Declare
TextChoicesandIntegerChoicesfields with the choices class as their type. The schema then accepts only valid values, and OpenAPI lists them. - A
@field_validatorchecks and cleans one field. A@model_validator(mode="after")compares fields once they’re all valid. Validators onMeta.fieldsneedcheck_fields=False. - Raise
PydanticCustomErrorfor your own error type and message, orValueErrorfor a quickvalue_error. Either way the client gets a422with every problem listed. PatchDict[Schema]gives the view a dict of only the fields sent. It also acceptsnullfor every field, so reject it where the column can’t be empty.- Validators only see the request. Check rules that depend on stored data, such as allowed status changes, in the view and raise
HttpError.
Next
Anyone can still read and change every project. In Part 4: Auth & permissions, you’ll add JWT authentication, project memberships with roles, and comments that only their author can edit.
3.4 - Part 4: Auth & permissions
Right now anyone who can reach the API can read and change every project. In this part you’ll add JSON Web Tokens, written from scratch with the standard library, require them on every endpoint, and then decide what each user may do: project memberships with roles, queries scoped to the user’s projects, and comments that only their author can edit.
- How to issue and verify JWT access and refresh tokens with nothing but the standard library
- How to protect a whole API with an
HttpBearerauthenticator, and open up a few endpoints withauth=None - How to read the current user from
request.auth - How to write one permission helper that returns
404to non-members and403to members without the right role - How to scope every query to the user’s projects, and add object-level rules for comments
Time: about 15 minutes
The accounts app
Users, tokens and the login endpoints get their own app:
uv run python manage.py startapp accounts
Delete views.py and tests.py again, and add the app to the end of INSTALLED_APPS:
# locallibrary_config/settings.py
INSTALLED_APPS = [
    'daphne',
    'django.contrib.admin',
    'django.contrib.auth',
    'django.contrib.contenttypes',
    'django.contrib.sessions',
    'django.contrib.messages',
    'django.contrib.staticfiles',
    'catalog.apps.CatalogConfig',
    'chat',
    'ninja',
    'projects',
    'tasks',
    'accounts',
]
This accounts app has nothing to do with the accounts/ URLs (accounts/login/ and friends) that you added in Prep 06. Those come from django.contrib.auth.urls, keep working as before, and log users in with a session. TaskFlow’s accounts app logs users in with tokens instead. Both use the same User table, so a user can log in either way.
UserOut from Part 2 moves here too. The projects app needs it in this part, and projects/schemas.py can’t import from tasks/schemas.py, which already imports LabelOut from projects/schemas.py. Cut it from tasks/schemas.py, along with its User import, and import it from the new module instead, so TaskOut keeps working:
# tasks/schemas.py
from accounts.schemas import UserOut
Then create accounts/schemas.py:
# accounts/schemas.py
from django.contrib.auth.models import User
from ninja import ModelSchema, Schema


class UserOut(ModelSchema):
    display_name: str

    class Meta:
        model = User
        fields = ["id", "username"]

    @staticmethod
    def resolve_display_name(user):
        return user.get_full_name() or user.username


class SignupIn(Schema):
    username: str
    password: str


class TokenIn(Schema):
    username: str
    password: str


class RefreshIn(Schema):
    refresh: str


class TokenOut(Schema):
    access: str
    refresh: str
JSON Web Tokens from scratch
A JWT is three base64url strings joined by dots: a header, a payload of claims, and a signature over the first two. With HS256, the signature is an HMAC-SHA256 made with a secret key, here settings.SECRET_KEY. Anyone can read the claims, but no one can change them without the key.
That’s short enough to write yourself:
# accounts/tokens.py
import base64
import hashlib
import hmac
import json
import time

from django.conf import settings

ACCESS_TOKEN_LIFETIME = 15 * 60  # 15 minutes
REFRESH_TOKEN_LIFETIME = 7 * 24 * 60 * 60  # 7 days


def b64encode(data: bytes) -> str:
    return base64.urlsafe_b64encode(data).rstrip(b"=").decode()


def b64decode(data: str) -> bytes:
    return base64.urlsafe_b64decode(data + "=" * (-len(data) % 4))


def sign(message: str) -> str:
    digest = hmac.new(settings.SECRET_KEY.encode(), message.encode(), hashlib.sha256).digest()
    return b64encode(digest)


def create_token(user_id: int, token_type: str, lifetime: int) -> str:
    header = b64encode(json.dumps({"alg": "HS256", "typ": "JWT"}).encode())
    claims = {"sub": str(user_id), "type": token_type, "exp": int(time.time()) + lifetime}
    payload = b64encode(json.dumps(claims).encode())
    return f"{header}.{payload}.{sign(f'{header}.{payload}')}"


def decode_token(token: str, token_type: str) -> dict | None:
    """Return the claims of a valid, unexpired token of the given type, else None."""
    try:
        header, payload, signature = token.split(".")
    except ValueError:
        return None
    if not hmac.compare_digest(signature.encode(), sign(f"{header}.{payload}").encode()):
        return None
    claims = json.loads(b64decode(payload))
    if claims["type"] != token_type or claims["exp"] < time.time():
        return None
    return claims


def create_token_pair(user_id: int) -> dict:
    return {
        "access": create_token(user_id, "access", ACCESS_TOKEN_LIFETIME),
        "refresh": create_token(user_id, "refresh", REFRESH_TOKEN_LIFETIME),
    }
- JWTs use base64url without the
=padding.b64decodeadds the padding back before decoding. sub(the user id) andexp(expiry, in Unix seconds) are standard claims.typeis a claim of your own that tells access and refresh tokens apart, so a refresh token can’t be used to call the API.decode_tokenchecks the signature before it reads the payload, so every claim it looks at was signed by you.hmac.compare_digestcompares in constant time, which doesn’t leak how many characters matched.- The header is signed, but never trusted: the code always verifies with HS256, whatever
algthe token claims. That rules out the classic"alg": "none"attack. - Anything wrong, whether a malformed token, a bad signature, the wrong type or an expired token, returns
None. The caller doesn’t need to know which.
The access token lives 15 minutes. The refresh token lives 7 days and can only be exchanged for a new pair.
Protecting the API
HttpBearer reads the Authorization: Bearer <token> header and passes the token to your authenticate() method. Whatever it returns becomes request.auth. None means the request is rejected with 401:
# accounts/auth.py
from django.contrib.auth.models import User
from ninja.security import HttpBearer

from .tokens import decode_token


class JWTAuth(HttpBearer):
    def authenticate(self, request, token):
        claims = decode_token(token, "access")
        if claims is None:
            return None
        return User.objects.filter(id=claims["sub"], is_active=True).first()
It returns the User, so every view can use request.auth as the current user. A deactivated user’s tokens stop working at once, even before they expire.
Set it on the NinjaAPI, so every operation requires a token, and mount the new router:
# taskflow/api.py
from ninja import NinjaAPI

from accounts.auth import JWTAuth

api = NinjaAPI(title="TaskFlow API", urls_namespace="taskflow", auth=JWTAuth())

api.add_router("/auth", "accounts.api.router")
api.add_router("/projects", "projects.api.router")
api.add_router("/projects/{project_id}/tasks", "tasks.api.router")
The auth endpoints themselves must work without a token. auth=None on their router opts them out:
# accounts/api.py
from django.contrib.auth import authenticate
from django.contrib.auth.models import User
from django.contrib.auth.password_validation import validate_password
from django.core.exceptions import ValidationError
from ninja import Router, Status
from ninja.errors import HttpError

from .schemas import RefreshIn, SignupIn, TokenIn, TokenOut, UserOut
from .tokens import create_token_pair, decode_token

router = Router(tags=["auth"], auth=None)


@router.post("/signup", response={201: UserOut})
def signup(request, payload: SignupIn):
    if User.objects.filter(username=payload.username).exists():
        raise HttpError(409, "This username is taken")
    try:
        validate_password(payload.password)
    except ValidationError as e:
        raise HttpError(400, " ".join(e.messages))
    user = User.objects.create_user(payload.username, password=payload.password)
    return Status(201, user)


@router.post("/token", response=TokenOut)
def obtain_token(request, payload: TokenIn):
    user = authenticate(username=payload.username, password=payload.password)
    if user is None:
        raise HttpError(401, "Invalid username or password")
    return create_token_pair(user.id)


@router.post("/refresh", response=TokenOut)
def refresh_token(request, payload: RefreshIn):
    claims = decode_token(payload.refresh, "refresh")
    if claims is None or not User.objects.filter(id=claims["sub"], is_active=True).exists():
        raise HttpError(401, "Invalid or expired refresh token")
    return create_token_pair(int(claims["sub"]))
authresolves from the most specific level: operation, then router, then API.auth=Noneis how you turn it off for part of an API that sets it globally.signupruns Django’sAUTH_PASSWORD_VALIDATORSand returns their messages as a400.obtain_tokenuses Django’sauthenticate(), so it respects inactive users and any authentication backends you configure.
Try it
Alice and Bob from Part 2 have no passwords yet. Set them in the shell:
$ uv run python manage.py shell
>>> alice = User.objects.get(username="alice")
>>> alice.set_password("wonderland-42")
>>> alice.save()
>>> bob = User.objects.get(username="bob")
>>> bob.set_password("builder-42")
>>> bob.save()
Without a token, every endpoint except the three under /taskflow/api/auth/ now returns 401:
$ curl http://127.0.0.1:8000/taskflow/api/projects/
{"detail": "Unauthorized"}
Log in:
$ curl -X POST http://127.0.0.1:8000/taskflow/api/auth/token -H "Content-Type: application/json" -d '{"username": "alice", "password": "wonderland-42"}'
{"access": "eyJhbGciOiAiSFMyNTYiLCAidHlwIjogIkpXVCJ9.eyJzdWIiOiAiMSIsICJ0eXBlIjogImFjY2VzcyIsICJleHAiOiAxNzkwNTk0MTkwfQ.GaiXckAgDYsFg8sT9aw69lVVvTQicl6jgm8B6EOvkec", "refresh": "eyJhbGciOiAiSFMyNTYiLCAidHlwIjogIkpXVCJ9.eyJzdWIiOiAiMSIsICJ0eXBlIjogInJlZnJlc2giLCAiZXhwIjogMTc5MTE5ODA5MH0.2T6GPT9KOTlhyGKNlGgs74W1LmviG5UneZA_K4gwgvc"}
A wrong password gives 401 with {"detail": "Invalid username or password"}. The middle part of the access token is the payload, readable by anyone:
>>> from accounts.tokens import b64decode
>>> b64decode("eyJzdWIiOiAiMSIsICJ0eXBlIjogImFjY2VzcyIsICJleHAiOiAxNzkwNTk0MTkwfQ")
b'{"sub": "1", "type": "access", "exp": 1790594190}'
Your sub is alice’s id, not 1, so your token won’t match the one above.
Send the access token in the Authorization header. With TOKEN set to the access value, GET /taskflow/api/projects/ returns the projects again:
$ curl http://127.0.0.1:8000/taskflow/api/projects/ -H "Authorization: Bearer $TOKEN"
When it expires, post the refresh token as {"refresh": "..."} to /taskflow/api/auth/refresh for a new pair. An access token is refused there, because its type claim is wrong:
{
    "detail": "Invalid or expired refresh token"
}
In the interactive docs at /taskflow/api/docs, the operations now show a lock, and an Authorize button appears at the top. Paste an access token there (without the Bearer prefix) and Swagger UI sends it with every request you try. The three auth endpoints have no lock, because they have no auth.
TaskFlow ignores the session cookie that the Quickstart’s API uses. Even if you’re logged in to the admin or at /accounts/login/, TaskFlow only knows who you are from the bearer token.
Go deeper: Authentication, Authentication: auth at different levels
Memberships and roles
Authentication tells you who is calling. Authorization decides what they may do. In TaskFlow that depends on the project: a user can be the owner of one project and a plain member of another. That’s a Membership with a role. Add it between Project and Label, along with the settings import:
# projects/models.py
from django.conf import settings
from django.db import models

...

class Role(models.TextChoices):
    OWNER = "owner"
    ADMIN = "admin"
    MEMBER = "member"


class Membership(models.Model):
    project = models.ForeignKey(Project, related_name="memberships", on_delete=models.CASCADE)
    user = models.ForeignKey(
        settings.AUTH_USER_MODEL, related_name="memberships", on_delete=models.CASCADE
    )
    role = models.CharField(max_length=10, choices=Role, default=Role.MEMBER)

    class Meta:
        constraints = [
            models.UniqueConstraint(fields=["project", "user"], name="unique_membership"),
        ]

    def __str__(self):
        return f"{self.user} in {self.project} ({self.role})"
$ uv run python manage.py makemigrations
Migrations for 'projects':
  projects/migrations/0003_membership.py
    + Create model Membership
$ uv run python manage.py migrate
The roles in TaskFlow:
| Role | Can |
|---|---|
member |
see the project, work on its tasks, comment |
admin |
also edit the project and create labels |
owner |
also delete the project, add members, and delete anyone’s comments |
Your existing projects have no members yet, so once the next step is in place nobody would see them. Make Alice their owner:
$ uv run python manage.py shell
>>> alice = User.objects.get(username="alice")
>>> for project in Project.objects.all():
...     Membership.objects.create(project=project, user=alice, role="owner")
...
<Membership: alice in Website redesign (owner)>
<Membership: alice in Mobile app (owner)>
One helper for every check
Almost every endpoint needs the same check: is this user a member of this project, and does their role allow the action? Put it in one function:
# projects/permissions.py
from django.shortcuts import get_object_or_404
from ninja.errors import HttpError

from .models import Membership


def get_project_or_404(user, project_id, roles=None):
    """Return the project if `user` is a member, with one of `roles` if given.

    Non-members get a 404, so they can't tell the project exists.
    Members without the right role get a 403.
    """
    membership = get_object_or_404(
        Membership.objects.select_related("project"), project_id=project_id, user=user
    )
    if roles and membership.role not in roles:
        raise HttpError(403, f"This needs the {' or '.join(roles)} role")
    return membership.project
- One query finds the membership and the project together.
- A non-member gets exactly the same
404as for a project id that doesn’t exist. A403would confirm that project 1 exists. - A member who lacks the role gets a
403that says which role is needed. They can already see the project, so there’s nothing to hide.
It’s a plain function, not a decorator: the view calls it and gets the project back, which it needs anyway.
Scoping projects
Now rewrite the projects endpoints so every query starts from the user’s memberships. Two schemas for managing members go at the end of projects/schemas.py, which now imports UserOut and Role:
# projects/schemas.py
from ninja import ModelSchema, Schema

from accounts.schemas import UserOut

from .models import Label, Project, Role

...

class MemberIn(Schema):
    username: str
    role: Role = Role.MEMBER


class MemberOut(Schema):
    user: UserOut
    role: Role
# projects/api.py
from django.contrib.auth.models import User
from django.db.models import Count, Q
from django.shortcuts import get_object_or_404
from ninja import Router, Status
from ninja.errors import HttpError

from .models import Project, Role
from .permissions import get_project_or_404
from .schemas import LabelIn, LabelOut, MemberIn, MemberOut, ProjectIn, ProjectOut

router = Router(tags=["projects"])


def projects_with_counts(user):
    return (
        Project.objects.filter(memberships__user=user)
        .annotate(
            task_count=Count("tasks"),
            unassigned_task_count=Count("tasks", filter=Q(tasks__assignee=None)),
        )
        .prefetch_related("labels")
    )


@router.get("/", response=list[ProjectOut])
def list_projects(request):
    return projects_with_counts(request.auth).order_by("id")


@router.post("/", response={201: ProjectOut})
def create_project(request, payload: ProjectIn):
    project = Project.objects.create(**payload.dict())
    project.memberships.create(user=request.auth, role=Role.OWNER)
    return Status(201, projects_with_counts(request.auth).get(id=project.id))


@router.get("/{project_id}", response=ProjectOut)
def get_project(request, project_id: int):
    return get_object_or_404(projects_with_counts(request.auth), id=project_id)


@router.put("/{project_id}", response=ProjectOut)
def update_project(request, project_id: int, payload: ProjectIn):
    project = get_project_or_404(request.auth, project_id, roles=[Role.OWNER, Role.ADMIN])
    for attr, value in payload.dict().items():
        setattr(project, attr, value)
    project.save()
    return projects_with_counts(request.auth).get(id=project.id)


@router.delete("/{project_id}", response={204: None})
def delete_project(request, project_id: int):
    get_project_or_404(request.auth, project_id, roles=[Role.OWNER]).delete()
    return Status(204, None)


@router.post("/{project_id}/labels", response={201: LabelOut})
def create_label(request, project_id: int, payload: LabelIn):
    project = get_project_or_404(request.auth, project_id, roles=[Role.OWNER, Role.ADMIN])
    return Status(201, project.labels.create(**payload.dict()))


@router.get("/{project_id}/members", response=list[MemberOut])
def list_members(request, project_id: int):
    project = get_project_or_404(request.auth, project_id)
    return project.memberships.select_related("user").order_by("id")


@router.post("/{project_id}/members", response={201: MemberOut})
def add_member(request, project_id: int, payload: MemberIn):
    project = get_project_or_404(request.auth, project_id, roles=[Role.OWNER])
    user = User.objects.filter(username=payload.username).first()
    if user is None:
        raise HttpError(400, f"User {payload.username} does not exist")
    if project.memberships.filter(user=user).exists():
        raise HttpError(409, f"{user.username} is already a member")
    return Status(201, project.memberships.create(user=user, role=payload.role))
projects_with_counts()takes the user and filters on their memberships, so list and get only ever see the user’s projects. The filter comes beforeannotate(), and a user has at most one membership per project, so the task counts stay correct.- The user who creates a project becomes its owner.
- Update, delete and labels call
get_project_or_404()with the roles they need. MemberOutis a plainSchema, andlist_membersreturnsMembershipobjects. Django Ninja readsuserandrolefrom each one as attributes.
Try it
Sign up a third user with POST /taskflow/api/auth/signup. A weak password, as in {"username": "carol", "password": "carol"}, is rejected with the validators’ messages:
{
    "detail": "This password is too short. It must contain at least 8 characters. This password is too common."
}
{"username": "carol", "password": "sunflower-77"} returns 201 (with your next user id, not 3):
{
    "display_name": "carol",
    "id": 3,
    "username": "carol"
}
Log in as Carol. GET /taskflow/api/projects/ returns [], and GET /taskflow/api/projects/1 returns 404:
{
    "detail": "Not Found: No Project matches the given query."
}
The part after Not Found comes from Django’s Http404 message, and Django Ninja only adds it while DEBUG is on. With DEBUG = False, every 404 here is just {"detail": "Not Found"}, so it doesn’t matter which query didn’t find anything. Carol can create her own project, and she’s its owner.
As Alice, add Bob to project 1 with POST /taskflow/api/projects/1/members and {"username": "bob"}:
{
    "user": {
        "display_name": "bob",
        "id": 2,
        "username": "bob"
    },
    "role": "member"
}
Bob can now see the project and its tasks. He can’t rename it with PUT /taskflow/api/projects/1:
{
    "detail": "This needs the owner or admin role"
}
and DELETE /taskflow/api/projects/1 gives {"detail": "This needs the owner role"}.
Go deeper: Authentication, Errors & Exception Handling
Tasks and comments
Tasks belong to a project, so they’re covered by the same check. The new piece is comments, where the rule depends on the comment itself. Add the model to tasks/models.py:
# tasks/models.py
class Comment(models.Model):
    task = models.ForeignKey(Task, related_name="comments", on_delete=models.CASCADE)
    author = models.ForeignKey(
        settings.AUTH_USER_MODEL, related_name="comments", on_delete=models.CASCADE
    )
    body = models.TextField()
    created_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return f"Comment by {self.author} on {self.task}"
$ uv run python manage.py makemigrations
Migrations for 'tasks':
  tasks/migrations/0004_comment.py
    + Create model Comment
$ uv run python manage.py migrate
Add the comment schemas to tasks/schemas.py, and Comment to its model import:
# tasks/schemas.py
from ninja import ModelSchema, Schema
from pydantic import field_validator, model_validator
from pydantic_core import PydanticCustomError

from accounts.schemas import UserOut
from projects.schemas import LabelOut

from .models import Comment, Priority, Task, TaskStatus

...

class CommentIn(ModelSchema):
    class Meta:
        model = Comment
        fields = ["body"]


class CommentOut(ModelSchema):
    author: UserOut

    class Meta:
        model = Comment
        fields = ["id", "body", "created_at"]
Here’s the full tasks/api.py:
# tasks/api.py
from django.shortcuts import get_object_or_404
from ninja import PatchDict, Path, Router, Status
from ninja.errors import HttpError

from projects.models import Role
from projects.permissions import get_project_or_404

from .models import ALLOWED_TRANSITIONS, Priority, Task
from .schemas import CommentIn, CommentOut, StatusIn, TaskIn, TaskOut, TaskUpdate

router = Router(tags=["tasks"])


def get_task_or_404(user, project_id, task_id):
    project = get_project_or_404(user, project_id)
    return get_object_or_404(project.tasks, id=task_id)


def check_relations(project, payload):
    assignee_id = payload.assignee_id
    if assignee_id is not None and not project.memberships.filter(user_id=assignee_id).exists():
        raise HttpError(400, f"User {assignee_id} is not a member of this project")
    labels = list(project.labels.filter(id__in=payload.label_ids))
    if len(labels) != len(set(payload.label_ids)):
        raise HttpError(400, "Unknown label id for this project")
    return labels


@router.get("/", response=list[TaskOut])
def list_tasks(request, project_id: Path[int]):
    project = get_project_or_404(request.auth, project_id)
    return project.tasks.select_related("assignee").prefetch_related("labels").order_by("id")


@router.post("/", response={201: TaskOut})
def create_task(request, project_id: Path[int], payload: TaskIn):
    project = get_project_or_404(request.auth, project_id)
    labels = check_relations(project, payload)
    task = Task.objects.create(project=project, **payload.dict(exclude={"label_ids"}))
    task.labels.set(labels)
    return Status(201, task)


@router.get("/{task_id}", response=TaskOut)
def get_task(request, project_id: Path[int], task_id: int):
    return get_task_or_404(request.auth, project_id, task_id)


@router.patch("/{task_id}", response=TaskOut)
def update_task(request, project_id: Path[int], task_id: int, payload: PatchDict[TaskUpdate]):
    task = get_task_or_404(request.auth, project_id, task_id)
    for attr, value in payload.items():
        setattr(task, attr, value)
    if task.priority == Priority.URGENT and task.due_date is None:
        raise HttpError(400, "Urgent tasks need a due date")
    task.save()
    return task


@router.post("/{task_id}/status", response=TaskOut)
def change_status(request, project_id: Path[int], task_id: int, payload: StatusIn):
    task = get_task_or_404(request.auth, project_id, task_id)
    if payload.status not in ALLOWED_TRANSITIONS[task.status]:
        raise HttpError(409, f"Can't move a task from {task.status} to {payload.status}")
    task.status = payload.status
    task.save()
    return task


@router.get("/{task_id}/comments", response=list[CommentOut])
def list_comments(request, project_id: Path[int], task_id: int):
    task = get_task_or_404(request.auth, project_id, task_id)
    return task.comments.select_related("author").order_by("id")


@router.post("/{task_id}/comments", response={201: CommentOut})
def add_comment(request, project_id: Path[int], task_id: int, payload: CommentIn):
    task = get_task_or_404(request.auth, project_id, task_id)
    return Status(201, task.comments.create(author=request.auth, body=payload.body))


@router.put("/{task_id}/comments/{comment_id}", response=CommentOut)
def update_comment(
    request, project_id: Path[int], task_id: int, comment_id: int, payload: CommentIn
):
    task = get_task_or_404(request.auth, project_id, task_id)
    comment = get_object_or_404(task.comments, id=comment_id)
    if comment.author != request.auth:
        raise HttpError(403, "Only the author can edit a comment")
    comment.body = payload.body
    comment.save()
    return comment


@router.delete("/{task_id}/comments/{comment_id}", response={204: None})
def delete_comment(request, project_id: Path[int], task_id: int, comment_id: int):
    task = get_task_or_404(request.auth, project_id, task_id)
    comment = get_object_or_404(task.comments, id=comment_id)
    if comment.author != request.auth:
        # Anyone else needs to own the project
        get_project_or_404(request.auth, project_id, roles=[Role.OWNER])
    comment.delete()
    return Status(204, None)
get_task_or_404()goes through the project check first, then looks the task up inproject.tasks. Every task and comment endpoint uses it, so none of them can reach another project’s data.check_relations()now only accepts assignees who are members of the project. Part 2’s check for any existing user would let you assign tasks to strangers.- Comments are looked up through
task.comments, so a comment id from another task is a404. - The comment author comes from
request.auth, never from the request body. - These are object-level rules: they depend on the comment, not only on the project role. Only the author may edit a comment. The author or the project owner may delete it, and for anyone else the view reuses
get_project_or_404()withroles=[Role.OWNER].
Try it
As Bob, post a comment on task 2 with POST /taskflow/api/projects/1/tasks/2/comments and {"body": "The footer links point to the old domain."}:
{
    "author": {
        "display_name": "bob",
        "id": 2,
        "username": "bob"
    },
    "id": 1,
    "body": "The footer links point to the old domain.",
    "created_at": "2026-09-28T11:00:54.225Z"
}
Alice replies with a comment of her own, {"body": "Good catch, thanks!"} (id 2). She owns the project, but that doesn’t let her edit Bob’s words. PUT /taskflow/api/projects/1/tasks/2/comments/1 as Alice returns:
{
    "detail": "Only the author can edit a comment"
}
The same request as Bob returns 200 with the new body. Bob can’t delete Alice’s comment 2:
{
    "detail": "This needs the owner role"
}
But Alice, as the owner, can delete Bob’s comment 1: DELETE /taskflow/api/projects/1/tasks/2/comments/1 returns 204. And Carol, who isn’t a member, gets a 404 for the task’s comments, like for everything else in the project.
Go deeper: Authentication, Decorators
Recap
- A JWT is a signed, readable payload. HS256 with
hmac,hashlib,base64andjsonfits in a module of about 50 lines. Verify the signature before reading the claims, and check the expiry and the token type. HttpBearerreads theAuthorization: Bearerheader. Whatauthenticate()returns becomesrequest.auth, andNonemeans401.NinjaAPI(auth=...)protects every endpoint.auth=Noneon a router or an operation opts it out, as for login and refresh.- One helper,
get_project_or_404(user, project_id, roles=...), answers404to non-members and403to members without the right role. - Start every query from the user’s memberships, and take ownership fields such as a comment’s author from
request.auth. - Rules about a single object, such as who may edit a comment, go in the view, after the object is loaded.
Next
The task list returns everything at once. In Part 5: Filtering, search, ordering & pagination, you’ll filter tasks by status, assignee and label, search them, sort them, and paginate tasks and comments.
3.5 - Part 5: Filtering, search, ordering & pagination
GET /taskflow/api/projects/{project_id}/tasks/ returns every task of a project in one response. That’s fine for a handful, but a real team wants the tasks assigned to them, the overdue ones, or the ones mentioning “checkout”, and it doesn’t want a thousand of them at once. In this part you’ll add filters and search with a FilterSchema, let clients pick the sort order from a fixed list, and paginate tasks by page number and comments with a cursor.
- How to turn query parameters into ORM lookups with
FilterSchemaandFilterLookup - How to search several fields at once, and accept a list of values for one parameter
- How to restrict an
orderingparameter to a fixed set of values withLiteral - How to paginate a list with
@paginateandPageNumberPagination - How cursor pagination works, and when to prefer it
Time: about 15 minutes
Some tasks to work with
Filters are more interesting with more than four tasks. Add three to the “Website redesign” project, plus a few comments on task 2. Django’s shell imports your models automatically:
$ uv run python manage.py shell
>>> bob = User.objects.get(username="bob")
>>> fix = Task.objects.create(
...     project_id=1, title="Fix mobile menu overlap", assignee=bob, priority=4,
...     due_date="2026-10-01", description="The menu covers the logo on small screens",
... )
>>> fix.labels.add(1)
>>> Task.objects.create(project_id=1, title="Set up analytics", description="Page views and the signup funnel", due_date="2026-10-20")
<Task: Set up analytics>
>>> Task.objects.create(project_id=1, title="Compress hero images", assignee=bob, priority=3, due_date="2026-10-03")
<Task: Compress hero images>
>>> for body in ["Found three more on the pricing page.", "Fixed on staging.", "Looks good, closing."]:
...     Comment.objects.create(task_id=2, author=bob, body=body)
...
<Comment: Comment by bob on Fix broken footer links>
<Comment: Comment by bob on Fix broken footer links>
<Comment: Comment by bob on Fix broken footer links>
The original tutorial writes assignee_id=2 and author_id=2, which is bob’s id there. Looking bob up by his username works whatever his id is in your database.
The project now has seven tasks: 1 to 4 from the earlier parts and the new 5, 6 and 7. Task 2 has four comments, with ids 2 to 5. Nothing in this part changes a model, so there are no migrations.
A filter schema
A FilterSchema is a Schema whose fields are query parameters, with a .filter() method that turns them into a Q expression. Add one to tasks/schemas.py, together with the list of allowed sort orders:
# tasks/schemas.py
from datetime import date
from typing import Annotated, Literal

from ninja import FilterLookup, FilterSchema, ModelSchema, Schema
from pydantic import field_validator, model_validator
from pydantic_core import PydanticCustomError

from accounts.schemas import UserOut
from projects.schemas import LabelOut

from .models import Comment, Priority, Task, TaskStatus

...


class TaskFilter(FilterSchema):
    status: Annotated[list[TaskStatus] | None, FilterLookup("status__in")] = None
    assignee: Annotated[str | None, FilterLookup("assignee__username")] = None
    label: Annotated[str | None, FilterLookup("labels__name")] = None
    due_before: Annotated[date | None, FilterLookup("due_date__lt")] = None
    search: Annotated[
        str | None, FilterLookup(["title__icontains", "description__icontains"])
    ] = None


TaskOrdering = Literal[
    "created_at", "-created_at", "due_date", "-due_date", "priority", "-priority"
]
- Every field defaults to
None, and aNonefield is skipped. A request without query parameters is not filtered at all. FilterLookupsets the ORM lookup for a field. Without it, the field name is used, as inQ(status=value). The public parameter names stay short (assignee,label), while the lookups follow relations (assignee__username,labels__name).statusis a list, so a client can repeat the parameter:?status=todo&status=in_progressbecomesQ(status__in=[...]). The items areTaskStatusvalues, so an unknown status is a422.searchhas a list of lookups. They’re combined withOR, so the term can appear in the title or the description. The different fields are combined withAND.due_beforeis adate, parsed and validated like any other schema field.TaskOrderingis used in the view below.
Go deeper: Filtering: custom lookups, Filtering: combining expressions
Filters, ordering and pages in the view
Here’s the new list_tasks, with the imports it needs:
# tasks/api.py
from django.shortcuts import get_object_or_404
from ninja import PatchDict, Path, Query, Router, Status
from ninja.errors import HttpError
from ninja.pagination import CursorPagination, PageNumberPagination, paginate

from projects.models import Role
from projects.permissions import get_project_or_404

from .models import ALLOWED_TRANSITIONS, Priority, Task
from .schemas import (
    CommentIn,
    CommentOut,
    StatusIn,
    TaskFilter,
    TaskIn,
    TaskOrdering,
    TaskOut,
    TaskUpdate,
)

...


@router.get("/", response=list[TaskOut])
@paginate(PageNumberPagination, page_size=20)
def list_tasks(
    request,
    project_id: Path[int],
    filters: Query[TaskFilter],
    ordering: TaskOrdering = "created_at",
):
    project = get_project_or_404(request.auth, project_id)
    tasks = filters.filter(project.tasks.select_related("assignee").prefetch_related("labels"))
    return tasks.order_by(ordering, "id")
Query[TaskFilter]reads the schema’s fields from the query string, so the parameters are?status=...&search=..., not?filters=....filters.filter()applies the filters to the queryset it’s given. That queryset is already scoped to a project the user belongs to, so the filters can only narrow Part 4’s permissions, never widen them.orderingis a plain query parameter typed with theLiteral. Only the six listed values get through, which matters because the value goes straight intoorder_by(). Never pass a client’s string toorder_by()unchecked. It would let them sort by any field, including ones they can’t see, such as a related user’s password hash."id"comes second inorder_by(), so tasks with the same priority or due date always come back in the same order. Stable ordering matters once results are split into pages.@paginategoes below the router decorator. The view still returns a queryset, andresponsestill sayslist[TaskOut]. The next section covers what it changes.
Try it
The shell is quicker than curl for a series of queries. TestClient from Part 2 can send the token as a default header. With a small helper that prints only the titles:
$ uv run python manage.py shell
>>> from accounts.tokens import create_token_pair
>>> from ninja.testing import TestClient
>>> from taskflow.api import api
>>> token = create_token_pair(User.objects.get(username="alice").id)["access"]
>>> client = TestClient(api, headers={"Authorization": f"Bearer {token}"})
>>> def titles(query):
...     return [task["title"] for task in client.get(f"/projects/1/tasks/?{query}").json()["items"]]
...
>>> titles("assignee=bob")
['Fix broken footer links', 'Fix mobile menu overlap', 'Compress hero images']
>>> titles("status=in_progress&status=done")
['Write launch announcement']
>>> titles("label=bug")
['Fix broken footer links', 'Fix mobile menu overlap']
>>> titles("search=fix")
['Fix broken footer links', 'Fix mobile menu overlap']
>>> titles("search=SIGNUP")
['Set up analytics']
>>> titles("due_before=2026-10-10&ordering=due_date")
['Fix mobile menu overlap', 'Compress hero images']
>>> titles("status=todo&ordering=-priority")
['Fix mobile menu overlap', 'Compress hero images', 'Draft the sitemap', 'Fix broken footer links', 'Pick a color palette', 'Set up analytics']
search=SIGNUPfinds “Set up analytics” through its description, becauseicontainsignores case.- Filtering on
label=bugonly selects the tasks. Theirlabelsin the response still list every label, becauseprefetch_relatedloads them in a separate query. - With
-priority, the four tasks with priority 2 come out inidorder, thanks to the secondorder_by()field. - On SQLite, tasks without a due date come first with
ordering=due_date. PostgreSQL puts them last. Combine the ordering withdue_before, as above, to leave them out.
Values that don’t fit the types are rejected before the view runs. ?ordering=oldest returns a 422:
{
    "detail": [
        {
            "type": "literal_error",
            "loc": [
                "query",
                "ordering"
            ],
            "msg": "Input should be 'created_at', '-created_at', 'due_date', '-due_date', 'priority' or '-priority'",
            "ctx": {
                "expected": "'created_at', '-created_at', 'due_date', '-due_date', 'priority' or '-priority'"
            }
        }
    ]
}
And ?status=archived fails on the first list item. The loc includes filters, the name of the view parameter that holds the schema:
{
    "detail": [
        {
            "type": "enum",
            "loc": [
                "query",
                "filters",
                "status",
                0
            ],
            "msg": "Input should be 'todo', 'in_progress' or 'done'",
            "ctx": {
                "expected": "'todo', 'in_progress' or 'done'"
            }
        }
    ]
}
In the interactive docs, each filter shows up as its own query parameter, and ordering as a dropdown with the six values.
Go deeper: Filtering, Query Parameters
Page numbers
@paginate(PageNumberPagination, page_size=20) adds two query parameters, page (starting at 1) and page_size, and wraps the result in an object with the page’s items and the total count. The shell helper above already read ["items"]. With TOKEN set as in Part 4 (access tokens expire after 15 minutes, so get a fresh one from POST /taskflow/api/auth/token if you get a 401), ask for the third page of three tasks, sorted by priority:
$ curl "http://127.0.0.1:8000/taskflow/api/projects/1/tasks/?ordering=-priority&page=3&page_size=3" -H "Authorization: Bearer $TOKEN"
{
    "items": [
        {
            "assignee": null,
            "labels": [],
            "status": "todo",
            "priority": 2,
            "id": 6,
            "project": 1,
            "title": "Set up analytics",
            "description": "Page views and the signup funnel",
            "due_date": "2026-10-20",
            "created_at": "2026-09-28T11:08:55.867Z"
        }
    ],
    "count": 7
}
- The paginator slices the queryset, so the database only returns the rows of the requested page.
countis one extraCOUNTquery with the same filters. The filtered, paginated list takes 5 queries in total: the user from the token, the membership, the count, the tasks with their assignees, and the labels. - Without
page_size, a page has 20 tasks. A client can ask for more, up tomax_page_size, which defaults to 100.?page_size=500returns at most 100 tasks. - A page past the end, such as
?page=9, is not an error. It returns{"items": [], "count": 7}.?page=0is a422, becausepagemust be at least 1. - In the OpenAPI schema, the response is now
PagedTaskOut, withitemsandcount. Django Ninja generates it fromlist[TaskOut].
Page numbers are what most UIs need: “page 3 of 5”, with a total. Their weak point is data that changes while someone is paging. If a task is added at the top between two requests, every page shifts by one, and the client sees one task twice.
Go deeper: Pagination
Cursor pagination for comments
Comments grow at the end, and clients load them as a feed, “show more” by “show more”. That’s what CursorPagination is for. Instead of a page number, each response has a next link that points just past the last item seen. In tasks/api.py, add the decorator to list_comments and drop the .order_by("id"):
# tasks/api.py
@router.get("/{task_id}/comments", response=list[CommentOut])
@paginate(CursorPagination, ordering=("id",), page_size=20)
def list_comments(request, project_id: Path[int], task_id: int):
    task = get_task_or_404(request.auth, project_id, task_id)
    return task.comments.select_related("author")
orderingbelongs to the paginator now. It sorts the queryset itself, and uses the first field to record the position in the cursor. That field should be unique, or close to it. The comment id is unique and grows with time, so the oldest comments come first.- The parameters are
cursorandpage_size. There is no page number and nocount.
Ask for two comments at a time:
$ curl "http://127.0.0.1:8000/taskflow/api/projects/1/tasks/2/comments?page_size=2" -H "Authorization: Bearer $TOKEN"
{
    "previous": null,
    "next": "http://127.0.0.1:8000/taskflow/api/projects/1/tasks/2/comments?cursor=cD00&page_size=2",
    "results": [
        {
            "author": {
                "display_name": "Alice Martin",
                "id": 1,
                "username": "alice"
            },
            "id": 2,
            "body": "Good catch, thanks!",
            "created_at": "2026-09-28T11:08:55.863Z"
        },
        {
            "author": {
                "display_name": "bob",
                "id": 2,
                "username": "bob"
            },
            "id": 3,
            "body": "Found three more on the pricing page.",
            "created_at": "2026-09-28T11:08:55.867Z"
        }
    ]
}
The items are under results, not items. The next link keeps the other query parameters and adds a cursor. cD00 is base64 for p=4: the next page starts at comment id 4. Follow the link:
{
    "previous": "http://127.0.0.1:8000/taskflow/api/projects/1/tasks/2/comments?cursor=cD00JnI9VHJ1ZSZvPTE%3D&page_size=2",
    "next": null,
    "results": [
        {
            "author": {
                "display_name": "bob",
                "id": 2,
                "username": "bob"
            },
            "id": 4,
            "body": "Fixed on staging.",
            "created_at": "2026-09-28T11:08:55.869Z"
        },
        {
            "author": {
                "display_name": "bob",
                "id": 2,
                "username": "bob"
            },
            "id": 5,
            "body": "Looks good, closing.",
            "created_at": "2026-09-28T11:08:55.870Z"
        }
    ]
}
nextisnullon the last page, andpreviousleads back to comments 2 and 3.- The cursor is a position, not an offset. If someone adds a comment and the client follows the same
nextlink again, it still gets comments 4 and 5, now with anextlink to the new comment. Nothing is skipped or shown twice. - The paginator fetches one row more than the page size to know whether there’s a next page, so it needs no
COUNTquery. That keeps it fast on large tables, but a UI can’t show “page 3 of 5”. - The cursor is only encoded, not signed. A client can craft one, but it can only move the position inside the queryset the view returns, which is already limited to the task’s comments. A cursor that isn’t valid base64 returns a
422with{"detail": [{"cursor": "Invalid Cursor"}]}.
Go deeper: Pagination
Recap
- A
FilterSchemadeclares filters as typed fields, andfilters.filter(queryset)turns the fields that were sent into aQexpression. Use it withQuery[...]. FilterLookupmaps a short parameter name to any ORM lookup. A list of lookups is combined withOR, which is all a simple search needs.- Accept a sort order only from a
Literalof allowed values, and add a unique field such asidas a tie-breaker. @paginate(PageNumberPagination)wraps a view that returns a queryset. It slices the query and addscount. Clients get page numbers and totals.@paginate(CursorPagination, ordering=...)givesnext/previouslinks that stay correct while data is added, without aCOUNTquery. Use it for feeds such as comments.
Next
Tasks can have comments, but not files. In Part 6: File uploads & forms, you’ll attach files to tasks with multipart uploads, validate their size and type, and return absolute URLs for them.
3.6 - Part 6: File uploads & forms
Tasks often come with files: a design mockup, a screenshot of a bug, a PDF from the client. In this part you’ll let members attach files to tasks. An upload is a multipart/form-data request instead of JSON, so you’ll combine a file parameter with form fields, validate the file’s size and type, store it with a plain FileField, and return an absolute URL for it.
- How to accept a file together with form fields using
File[...]andForm[...] - How to validate an upload with a reusable annotated type, so errors come back as
422 - How to configure
MEDIA_ROOTand serve uploaded files during development - How to build absolute URLs in a response with a resolver that reads the request
- How to delete a file together with its database row, behind a permission check
Time: about 15 minutes
Storing files
An attachment belongs to a task and remembers who uploaded it. Add the model at the end of tasks/models.py:
# tasks/models.py
class Attachment(models.Model):
    task = models.ForeignKey(Task, related_name="attachments", on_delete=models.CASCADE)
    file = models.FileField(upload_to="attachments/%Y/%m/")
    name = models.CharField(max_length=200)
    uploaded_by = models.ForeignKey(
        settings.AUTH_USER_MODEL, related_name="attachments", on_delete=models.CASCADE
    )
    uploaded_at = models.DateTimeField(auto_now_add=True)

    def __str__(self):
        return self.name
fileis aFileField, not anImageField.ImageFieldneeds Pillow, and attachments aren’t only images.upload_toputs files in a folder per month, such asattachments/2026/09/. The database stores only that relative path. The file itself goes to the storage, which is the local disk by default.nameis the display name. The client can choose it, or it defaults to the uploaded file’s name.
$ uv run python manage.py makemigrations
Migrations for 'tasks':
  tasks/migrations/0005_attachment.py
    + Create model Attachment
$ uv run python manage.py migrate
Django needs to know where to put uploads and under which URL to serve them. Add two settings below STATIC_URL in locallibrary_config/settings.py:
# locallibrary_config/settings.py
STATIC_URL = 'static/'

# User-uploaded files
MEDIA_URL = 'media/'
MEDIA_ROOT = BASE_DIR / 'media'
runserver doesn’t serve MEDIA_ROOT on its own. Your locallibrary_config/urls.py already uses Django’s static() helper to serve static files, in the block you added in the MDN tutorial. Add one line to that block, for media files:
# locallibrary_config/urls.py
# Use static() to add URL mapping to serve static files during development (only)
from django.conf import settings
from django.conf.urls.static import static

urlpatterns += static(settings.STATIC_URL, document_root=settings.STATIC_ROOT)
urlpatterns += static(settings.MEDIA_URL, document_root=settings.MEDIA_ROOT)
static() returns no URL patterns when DEBUG is off. In production, the web server or a storage service such as S3 serves the files.
Uploaded files never belong in git. The original tutorial says its .gitignore already excludes media/, but the one you started from in Prep 01 doesn’t. Add this line to your .gitignore:
media/
Validating the upload
Django Ninja passes an uploaded file to your view as an UploadedFile, which is Django’s own class. It already has a name and a size. Validation rules for it can live in the type, like any other Pydantic rule. Add the new imports and code to tasks/schemas.py:
# tasks/schemas.py
from datetime import date
from pathlib import Path
from typing import Annotated, Literal

from ninja import FilterLookup, FilterSchema, ModelSchema, Schema, UploadedFile
from pydantic import AfterValidator, Field, field_validator, model_validator
from pydantic_core import PydanticCustomError

from accounts.schemas import UserOut
from projects.schemas import LabelOut

from .models import Attachment, Comment, Priority, Task, TaskStatus

...


MAX_UPLOAD_SIZE = 5 * 1024 * 1024  # 5 MB
ALLOWED_EXTENSIONS = {".pdf", ".png", ".jpg", ".jpeg", ".txt", ".md"}


def check_upload(file: UploadedFile) -> UploadedFile:
    if file.size > MAX_UPLOAD_SIZE:
        raise PydanticCustomError("file_too_large", "Files can be at most 5 MB")
    if Path(file.name).suffix.lower() not in ALLOWED_EXTENSIONS:
        raise PydanticCustomError("file_type", "Only PDF, PNG, JPEG and text files are allowed")
    return file


AttachmentFile = Annotated[UploadedFile, AfterValidator(check_upload)]


class AttachmentIn(Schema):
    name: str = Field("", max_length=200)
check_uploadis a normal Pydantic validator. It runs after the file is parsed, and raisesPydanticCustomErrorlike the validators from Part 3, so a rejected file is a422with its owntypeand message.AttachmentFilebundles the type and its rules. Any endpoint that takes an attachment can use it, and the view only ever sees a valid file.- The extension check uses the file name. The
content_typeof an upload comes from the client too, so neither proves what’s inside the file. What they do prevent is storing, say, an.htmlfile that your media server would then serve as a web page. - Django has no size limit for uploaded files.
DATA_UPLOAD_MAX_MEMORY_SIZEdoesn’t count them, andFILE_UPLOAD_MAX_MEMORY_SIZEonly decides when Django switches from memory to a temporary file. The check runs after the whole file has arrived, so in production also cap the request size in the web server, such asclient_max_body_sizein nginx. AttachmentInholds the form fields that come with the file. There is only one here, the optional display name.
Go deeper: File Uploads, Errors & Exception Handling
The upload endpoint
A file can’t travel inside a JSON body, so the whole request is multipart/form-data: one part per form field, and one for the file. Add the imports and two endpoints to tasks/api.py:
# tasks/api.py
from django.shortcuts import get_object_or_404
from ninja import File, Form, PatchDict, Path, Query, Router, Status
from ninja.errors import HttpError
from ninja.pagination import CursorPagination, PageNumberPagination, paginate

from projects.models import Role
from projects.permissions import get_project_or_404

from .models import ALLOWED_TRANSITIONS, Priority, Task
from .schemas import (
    AttachmentFile,
    AttachmentIn,
    AttachmentOut,
    CommentIn,
    CommentOut,
    StatusIn,
    TaskFilter,
    TaskIn,
    TaskOrdering,
    TaskOut,
    TaskUpdate,
)

...


@router.get("/{task_id}/attachments", response=list[AttachmentOut])
def list_attachments(request, project_id: Path[int], task_id: int):
    task = get_task_or_404(request.auth, project_id, task_id)
    return task.attachments.select_related("uploaded_by").order_by("id")


@router.post("/{task_id}/attachments", response={201: AttachmentOut})
def upload_attachment(
    request,
    project_id: Path[int],
    task_id: int,
    details: Form[AttachmentIn],
    file: File[AttachmentFile],
):
    task = get_task_or_404(request.auth, project_id, task_id)
    attachment = task.attachments.create(
        file=file, name=details.name or file.name, uploaded_by=request.auth
    )
    return Status(201, attachment)
Form[AttachmentIn]reads the schema’s fields from the form data, the same wayQuery[TaskFilter]read them from the query string in Part 5. The client sends anamefield, not adetailsfield.File[AttachmentFile]reads thefilepart fromrequest.FILESand runscheck_upload. With aFileparameter present, Django Ninja documents the whole request body asmultipart/form-data, and the interactive docs show a file picker.- Passing the
UploadedFiletocreate()is enough. TheFileFieldsaves it to the storage underupload_to, and the row gets the stored path. - The file name comes from the client, but Django keeps only its last part. A file sent as
../../evil.pdfis stored asattachments/2026/09/evil.pdf. If a file with the same name exists, the storage adds a random suffix, as infooter_42rBBEz.png, and the display name staysfooter.png. - Both endpoints start with
get_task_or_404from Part 4, so only members of the project can list or upload files.
Django only fills request.FILES for POST requests. Django Ninja raises a ConfigError if you declare a File parameter on a PUT or PATCH operation, unless you add its compatibility middleware. The File Uploads guide explains how.
Go deeper: File Uploads, Form Data
Absolute file URLs
A FileField listed in Meta.fields is serialized as its URL, such as /media/attachments/2026/09/sitemap.pdf. That’s a path, not a URL. A mobile app or a frontend on another domain doesn’t know which host to put in front of it. The request does, so AttachmentOut builds the full URL in a resolver:
# tasks/schemas.py
class AttachmentOut(ModelSchema):
    uploaded_by: UserOut
    url: str

    class Meta:
        model = Attachment
        fields = ["id", "name", "uploaded_at"]

    @staticmethod
    def resolve_url(obj, context):
        return context["request"].build_absolute_uri(obj.file.url)
- A resolver that takes a
contextargument receives{"request": ..., "response_status": ...}when the schema is used as aresponse.build_absolute_uri()adds the scheme and host of the current request. urlis a new field that doesn’t exist on the model. The model’sfilefield isn’t inMeta.fields, so the response has no relative path next to the absolute one.- Declared fields come first in the output, so the keys are
uploaded_by,url, thenid,nameanduploaded_at.
Go deeper: Schemas: accessing context, Schemas: files and images
Try it
Start runserver and set TOKEN to an access token for alice, as in Part 4. With any small PDF saved as sitemap.pdf, upload it to task 1. curl -F sends a multipart/form-data request, and @ reads the file from disk:
$ curl http://127.0.0.1:8000/taskflow/api/projects/1/tasks/1/attachments \
    -H "Authorization: Bearer $TOKEN" \
    -F "name=Sitemap draft" \
    -F "file=@sitemap.pdf"
{
    "uploaded_by": {
        "display_name": "Alice Martin",
        "id": 1,
        "username": "alice"
    },
    "url": "http://127.0.0.1:8000/media/attachments/2026/09/sitemap.pdf",
    "id": 1,
    "name": "Sitemap draft",
    "uploaded_at": "2026-09-28T11:12:57.878Z"
}
Don’t set a Content-Type header yourself. curl -F sets it to multipart/form-data together with the boundary string that separates the parts. The URL works in the browser, and curl -I shows that Django serves it with the right type. Use the url from your own upload response, because the folder is named after the month you upload in:
$ curl -I http://127.0.0.1:8000/media/attachments/2026/09/sitemap.pdf
HTTP/1.1 200 OK
...
Content-Type: application/pdf
Content-Length: 2025
Content-Disposition: inline; filename="sitemap.pdf"
...
The media URL needs no token. Anyone who has the link can download the file. That’s fine for this tutorial, but for private files you’d return the file from an endpoint that checks permissions first, or use signed URLs from your storage service.
Now try a file type that isn’t allowed, such as -F "file=@setup.exe":
{
    "detail": [
        {
            "type": "file_type",
            "loc": [
                "file",
                "file"
            ],
            "msg": "Only PDF, PNG, JPEG and text files are allowed"
        }
    ]
}
A 6 MB scan.pdf gets "type": "file_too_large" with the message "Files can be at most 5 MB". Errors in the form fields and the file are collected together. A 201-character name with no file returns both:
{
    "detail": [
        {
            "type": "string_too_long",
            "loc": [
                "form",
                "name"
            ],
            "msg": "String should have at most 200 characters",
            "ctx": {
                "max_length": 200
            }
        },
        {
            "type": "missing",
            "loc": [
                "file",
                "file"
            ],
            "msg": "Field required"
        }
    ]
}
The first item of loc is where the value was read from: form for form fields, file for files. A JSON body sent to this endpoint gets the same missing error for file.
Deleting attachments
Deleting follows the rule from Part 4’s comments, with one difference: the uploader can delete their own file, and so can the project’s owners and admins. Add the endpoint to tasks/api.py:
# tasks/api.py
@router.delete("/{task_id}/attachments/{attachment_id}", response={204: None})
def delete_attachment(request, project_id: Path[int], task_id: int, attachment_id: int):
    task = get_task_or_404(request.auth, project_id, task_id)
    attachment = get_object_or_404(task.attachments, id=attachment_id)
    if attachment.uploaded_by != request.auth:
        get_project_or_404(request.auth, project_id, roles=[Role.OWNER, Role.ADMIN])
    attachment.file.delete(save=False)
    attachment.delete()
    return Status(204, None)
get_object_or_404(task.attachments, ...)looks the attachment up within the task. An attachment id from another task is a404.- For anyone but the uploader,
get_project_or_404withrolesdoes the role check, and raises a403for a plain member. - Deleting the row doesn’t delete the file. Django never removes files from the storage on its own, not even on a cascade.
attachment.file.delete(save=False)removes it first.save=Falseskips saving the row, which is deleted on the next line anyway.
Bob is a member of the project, not an owner. Get a token for him (password builder-42) and put it in BOB_TOKEN. When he tries to delete alice’s sitemap:
$ curl -X DELETE http://127.0.0.1:8000/taskflow/api/projects/1/tasks/1/attachments/1 -H "Authorization: Bearer $BOB_TOKEN"
{
    "detail": "This needs the owner or admin role"
}
His own uploads, or alice deleting any attachment in her project, return 204 and remove the file from media/. Files deleted with the whole task, by the cascade, stay on disk. Cleaning those up takes a periodic job or a post_delete signal.
Go deeper: Authentication
Recap
- A
File[...]parameter makes the requestmultipart/form-data. Combine it withForm[Schema]to read the other fields, which are validated like a JSON body. Annotated[UploadedFile, AfterValidator(...)]puts size and type rules into a reusable type. A bad file is a422withloc["file", ...], next to any form errors.- Store uploads with a
FileFieldandMEDIA_ROOT, and serve them withstatic()in development only. - A resolver with a
contextargument can read the request, andbuild_absolute_uri()turns a file’s path into a full URL. - Delete the stored file together with the row. Django won’t do it for you.
Next
TaskFlow now has most of its features, and each part checked them by hand. In Part 7: Testing, you’ll turn those checks into a pytest suite with Django Ninja’s TestClient, covering CRUD, validation, permissions, filters and uploads.
3.7 - Part 7: Testing
So far you’ve checked every feature by hand, with curl and the shell. In this part you’ll turn those checks into a pytest suite that runs in about half a second. Django Ninja’s TestClient calls your operations directly, so tests send JSON, form data, files and tokens without a running server.
- How to set up pytest and pytest-django for a Django Ninja project
- How to write fixtures for users, projects with memberships, and logged-in clients
- How
TestClientcalls an API, and how to send tokens, query strings and files with it - How to test validation errors, permissions and filters, and cover many cases with
parametrize - How to keep uploads and password hashing from slowing down or littering your tests
Time: about 15 minutes
Setting up pytest
The tests need two packages. They’re only used in development, so they don’t join Django and Django Ninja as runtime dependencies:
$ uv add --dev pytest pytest-django
Like Selenium in Part 4 of the Channels tutorial, they go into the development dependency group in pyproject.toml. Commit pyproject.toml and uv.lock.
pytest-django creates a test database for every run, applies your migrations to it, and wraps each test in a transaction that is rolled back afterwards. It needs to know your settings module. Create pytest.ini next to manage.py:
# pytest.ini
[pytest]
DJANGO_SETTINGS_MODULE = locallibrary_config.settings
testpaths = tests
Part 1 deleted the tests.py files from the apps. The tests go into a top-level tests/ folder instead, because most of them cross app boundaries: a task test needs users from accounts and a project from projects. testpaths tells pytest to look there. The folder needs no __init__.py. pytest-django puts the folder with manage.py on the import path, so from taskflow.api import api works in tests.
testpaths also keeps pytest away from catalog and chat. Their tests are written for Django’s own test runner, and chat/tests.py opens Chrome. Keep running those with uv run python manage.py test, which in turn doesn’t look in tests/, because that folder isn’t a Python package.
In the original tutorial, the SQLite test database lives in memory. Yours doesn’t: in Part 4 of the Channels tutorial you gave it its own file, test_db.sqlite3, in the TEST entry of DATABASES. pytest-django uses that setting too. Either way, your db.sqlite3 and the data from earlier parts are never touched.
Go deeper: Testing
Fixtures
Almost every test needs the same things: a few users, a project with an owner and a member, and a client that sends a token. pytest fixtures build them on demand. Fixtures in tests/conftest.py are available to every test file without an import:
# tests/conftest.py
import pytest
from django.contrib.auth.models import User
from ninja.testing import TestClient

from accounts.tokens import create_token_pair
from projects.models import Project, Role
from taskflow.api import api


@pytest.fixture(autouse=True)
def test_settings(settings, tmp_path):
    settings.MEDIA_ROOT = tmp_path  # uploads go to a temporary folder
    settings.PASSWORD_HASHERS = ["django.contrib.auth.hashers.MD5PasswordHasher"]


@pytest.fixture
def alice(db):
    return User.objects.create_user("alice", password="wonderland-42")


@pytest.fixture
def bob(db):
    return User.objects.create_user("bob", password="builder-42")


@pytest.fixture
def carol(db):
    return User.objects.create_user("carol", password="sunflower-77")


@pytest.fixture
def project(alice, bob):
    """Alice owns the project, bob is a member."""
    project = Project.objects.create(name="Website redesign", description="New marketing site")
    project.memberships.create(user=alice, role=Role.OWNER)
    project.memberships.create(user=bob, role=Role.MEMBER)
    return project


@pytest.fixture
def client_for():
    """Return a TestClient that is logged in as the given user."""

    def make_client(user):
        token = create_token_pair(user.id)["access"]
        return TestClient(api, headers={"Authorization": f"Bearer {token}"})

    return make_client
test_settingsruns for every test because ofautouse=True. It uses pytest-django’ssettingsfixture, which restores the original values after each test.MEDIA_ROOTpoints totmp_path, a fresh temporary folder per test, so upload tests don’t write into yourmedia/folder.- Django’s default password hasher is slow on purpose. Every
create_user()and every login pays for it. The MD5 hasher is unsafe for real passwords, but fine for test users. On the machine used for this tutorial, the suite takes 51 seconds without that line and half a second with it. - The user fixtures take pytest-django’s
dbfixture, which allows database access.projectdepends onaliceandbob, so asking forprojectcreates all three. client_foris a factory fixture. A test can call it for any user, even several times, as inclient_for(alice)andclient_for(bob). It creates the token withcreate_token_pair()from Part 4 instead of calling/auth/token, which keeps the tests of other endpoints independent of the login endpoint.TestClient(api, headers=...)sends those headers with every request. You used the same client in the shell in Part 5.
TestClient doesn’t go through urls.py or Django’s middleware. It finds the operation in the NinjaAPI and calls it with a fake request. Paths are therefore relative to the API: /projects/, not /taskflow/api/projects/. Everything that is part of the operation still runs: authentication, validation, your view, the response schema and the error handlers. A path that matches no operation raises an exception instead of returning 404, so a typo in a test fails loudly.
Go deeper: Testing
Testing authentication
The auth tests use a plain client without a token, because getting one is what they test. Create tests/test_auth.py:
# tests/test_auth.py
from ninja.testing import TestClient

from accounts.tokens import create_token
from taskflow.api import api

client = TestClient(api)


def test_obtain_token(alice):
    response = client.post("/auth/token", json={"username": "alice", "password": "wonderland-42"})
    assert response.status_code == 200
    token = response.json()["access"]

    response = client.get("/projects/", headers={"Authorization": f"Bearer {token}"})
    assert response.status_code == 200


def test_wrong_password(alice):
    response = client.post("/auth/token", json={"username": "alice", "password": "nope"})
    assert response.status_code == 401
    assert response.json() == {"detail": "Invalid username or password"}


def test_missing_token():
    response = client.get("/projects/")
    assert response.status_code == 401


def test_expired_token(alice):
    token = create_token(alice.id, "access", lifetime=-1)
    response = client.get("/projects/", headers={"Authorization": f"Bearer {token}"})
    assert response.status_code == 401


def test_refresh_token_is_not_an_access_token(alice):
    response = client.post("/auth/token", json={"username": "alice", "password": "wonderland-42"})
    refresh = response.json()["refresh"]
    response = client.get("/projects/", headers={"Authorization": f"Bearer {refresh}"})
    assert response.status_code == 401
json=serializes the body, like a client sendingContent-Type: application/json.response.json()decodes the answer.headers=on a single request adds to the client’s default headers, or overrides them.- Waiting 15 minutes for a token to expire isn’t an option.
create_token()takes the lifetime as an argument, so a negative one creates a token that expired a second ago. test_missing_tokenneeds no database.HttpBearerrejects a request without anAuthorizationheader beforeauthenticate()runs.
Go deeper: Testing
Projects and permissions
Most of the value of an API test suite is in the permission rules, because a missing check doesn’t show up when you try the happy path. Create tests/test_projects.py:
# tests/test_projects.py
from projects.models import Role


def test_create_project(alice, client_for):
    response = client_for(alice).post(
        "/projects/", json={"name": "Launch", "description": "Product launch"}
    )
    assert response.status_code == 201
    data = response.json()
    assert data["name"] == "Launch"
    assert data["task_count"] == 0
    assert alice.memberships.get(project_id=data["id"]).role == Role.OWNER


def test_list_only_my_projects(alice, carol, project, client_for):
    client_for(carol).post(
        "/projects/", json={"name": "Carol's garden", "description": "Vegetables"}
    )

    response = client_for(alice).get("/projects/")
    assert [p["name"] for p in response.json()] == ["Website redesign"]


def test_non_member_gets_404(carol, project, client_for):
    response = client_for(carol).get(f"/projects/{project.id}")
    assert response.status_code == 404


def test_member_cannot_delete(bob, project, client_for):
    response = client_for(bob).delete(f"/projects/{project.id}")
    assert response.status_code == 403
    assert response.json() == {"detail": "This needs the owner role"}


def test_owner_can_update(alice, project, client_for):
    response = client_for(alice).put(
        f"/projects/{project.id}", json={"name": "Website v2", "description": "Round two"}
    )
    assert response.status_code == 200
    project.refresh_from_db()
    assert project.name == "Website v2"


def test_add_member_twice(alice, bob, project, client_for):
    response = client_for(alice).post(f"/projects/{project.id}/members", json={"username": "bob"})
    assert response.status_code == 409
    assert response.json() == {"detail": "bob is already a member"}
- The highlighted tests pin down the two sides of
get_project_or_404from Part 4: a non-member gets404, a member without the right role gets403. - Tests can check the database as well as the response.
test_create_projectconfirms that the creator became the owner, andtest_owner_can_updatereloads the project withrefresh_from_db(). - Each test starts with an empty database. Carol’s project in
test_list_only_my_projectsis gone before the next test runs.
Tasks: validation, workflows and filters
The task tests share one more fixture, a task in the project. Create tests/test_tasks.py:
# tests/test_tasks.py
from datetime import date

import pytest
from django.core.files.uploadedfile import SimpleUploadedFile

from tasks.models import Priority, Task, TaskStatus


@pytest.fixture
def task(project, alice):
    return project.tasks.create(title="Draft the sitemap", assignee=alice)


def test_create_task(alice, bob, project, client_for):
    label = project.labels.create(name="design")
    response = client_for(alice).post(
        f"/projects/{project.id}/tasks/",
        json={"title": "  Pick fonts ", "assignee_id": bob.id, "label_ids": [label.id]},
    )
    assert response.status_code == 201
    data = response.json()
    assert data["title"] == "Pick fonts"
    assert data["assignee"]["username"] == "bob"
    assert data["labels"] == [{"id": label.id, "name": "design", "color": "#808080"}]
    assert data["status"] == "todo"


def test_blank_title(alice, project, client_for):
    response = client_for(alice).post(f"/projects/{project.id}/tasks/", json={"title": "   "})
    assert response.status_code == 422
    assert response.json()["detail"] == [
        {"type": "blank", "loc": ["body", "payload", "title"], "msg": "Title can't be blank"}
    ]


def test_urgent_task_needs_due_date(alice, project, client_for):
    response = client_for(alice).post(
        f"/projects/{project.id}/tasks/", json={"title": "Fix login", "priority": Priority.URGENT}
    )
    assert response.status_code == 422
    assert response.json()["detail"][0]["msg"] == "Value error, Urgent tasks need a due date"


def test_assignee_must_be_member(alice, carol, project, client_for):
    response = client_for(alice).post(
        f"/projects/{project.id}/tasks/", json={"title": "Pick fonts", "assignee_id": carol.id}
    )
    assert response.status_code == 400


def test_non_member_cannot_see_tasks(carol, task, client_for):
    response = client_for(carol).get(f"/projects/{task.project_id}/tasks/{task.id}")
    assert response.status_code == 404


def test_patch_changes_only_sent_fields(alice, task, client_for):
    response = client_for(alice).patch(
        f"/projects/{task.project_id}/tasks/{task.id}", json={"due_date": "2026-10-15"}
    )
    assert response.status_code == 200
    task.refresh_from_db()
    assert task.due_date == date(2026, 10, 15)
    assert task.title == "Draft the sitemap"
- Fixtures can live in a test file too.
taskis only used here, so it doesn’t need to be inconftest.py. test_blank_titlecompares the wholedetaillist. It holds the sameblankerror you saw in Part 3. A change to the error’s type, location or message breaks the test, which is what you want once clients depend on it.test_create_taskalso checks that the title was stripped and that the nestedassigneeandlabelsfrom Part 2 are in the response.Priority.URGENTcan go straight intojson=.IntegerChoicesmembers are integers, so it’s sent as4.
Many cases, one test
The status workflow from Part 3 has a table of allowed moves. @pytest.mark.parametrize turns a table of cases into one test each. Add it to tests/test_tasks.py:
# tests/test_tasks.py
@pytest.mark.parametrize(
    "old, new, status_code",
    [
        (TaskStatus.TODO, TaskStatus.IN_PROGRESS, 200),
        (TaskStatus.IN_PROGRESS, TaskStatus.DONE, 200),
        (TaskStatus.TODO, TaskStatus.DONE, 409),
        (TaskStatus.DONE, TaskStatus.TODO, 409),
    ],
)
def test_status_transitions(alice, task, client_for, old, new, status_code):
    Task.objects.filter(id=task.id).update(status=old)
    response = client_for(alice).post(
        f"/projects/{task.project_id}/tasks/{task.id}/status", json={"status": new}
    )
    assert response.status_code == status_code
The test sets the starting status directly in the database. Going through the API would make a test for done depend on two earlier moves working.
Filters work the same way: one fixture with a few tasks, and a table of query strings with the titles each should return. Add both:
# tests/test_tasks.py
@pytest.fixture
def sample_tasks(project, bob):
    bug = project.labels.create(name="bug")
    project.tasks.create(
        title="Fix mobile menu", assignee=bob, priority=Priority.URGENT, due_date=date(2026, 10, 1)
    ).labels.add(bug)
    project.tasks.create(
        title="Set up analytics",
        description="Page views",
        status=TaskStatus.IN_PROGRESS,
        due_date=date(2026, 10, 20),
    )
    project.tasks.create(
        title="Compress images",
        assignee=bob,
        priority=Priority.HIGH,
        due_date=date(2026, 10, 3),
        status=TaskStatus.DONE,
    )


@pytest.mark.parametrize(
    "query, titles",
    [
        ("", ["Fix mobile menu", "Set up analytics", "Compress images"]),
        ("status=todo&status=in_progress", ["Fix mobile menu", "Set up analytics"]),
        ("assignee=bob&label=bug", ["Fix mobile menu"]),
        ("due_before=2026-10-05", ["Fix mobile menu", "Compress images"]),
        ("search=VIEWS", ["Set up analytics"]),
        ("ordering=-priority", ["Fix mobile menu", "Compress images", "Set up analytics"]),
    ],
)
def test_filter_tasks(alice, project, sample_tasks, client_for, query, titles):
    response = client_for(alice).get(f"/projects/{project.id}/tasks/?{query}")
    assert response.status_code == 200
    assert [t["title"] for t in response.json()["items"]] == titles
    assert response.json()["count"] == len(titles)
- The query string goes straight into the path, including a repeated
statusparameter.TestClientalso takesquery_params={"status": ["todo", "in_progress"]}if you prefer a dict. - The titles are compared as a list, so each case also checks the order:
created_atby default, or theorderingparameter from Part 5. search=VIEWSfinds a match in the description and checks that the search ignores case.- The paginated response wraps the tasks in
items. Checkingcountas well makes sure the total that pagination reports agrees with the filtered list.
Go deeper: Testing
Comments and attachments
The last tests cover the object-level rules from Parts 4 and 6, and file uploads. Add them to the end of tests/test_tasks.py:
# tests/test_tasks.py
def test_only_author_can_edit_comment(alice, bob, task, client_for):
    comment = task.comments.create(author=bob, body="Looks good")
    url = f"/projects/{task.project_id}/tasks/{task.id}/comments/{comment.id}"

    response = client_for(alice).put(url, json={"body": "Changed"})
    assert response.status_code == 403

    response = client_for(alice).delete(url)  # the owner may delete it
    assert response.status_code == 204


def test_upload_attachment(alice, task, client_for, settings):
    file = SimpleUploadedFile("notes.txt", b"Remember the footer")
    response = client_for(alice).post(
        f"/projects/{task.project_id}/tasks/{task.id}/attachments",
        data={"name": "Meeting notes"},
        FILES={"file": file},
    )
    assert response.status_code == 201
    data = response.json()
    assert data["name"] == "Meeting notes"
    assert data["url"].startswith("http://testlocation/media/attachments/")

    attachment = task.attachments.get()
    assert (settings.MEDIA_ROOT / attachment.file.name).read_bytes() == b"Remember the footer"


def test_upload_rejects_file_type(alice, task, client_for):
    file = SimpleUploadedFile("setup.exe", b"MZ")
    response = client_for(alice).post(
        f"/projects/{task.project_id}/tasks/{task.id}/attachments", FILES={"file": file}
    )
    assert response.status_code == 422
    assert response.json()["detail"][0]["type"] == "file_type"
    assert not task.attachments.exists()


def test_delete_attachment(alice, bob, task, client_for, settings):
    file = SimpleUploadedFile("plan.pdf", b"%PDF-1.4")
    attachment = task.attachments.create(file=file, name="plan.pdf", uploaded_by=alice)
    url = f"/projects/{task.project_id}/tasks/{task.id}/attachments/{attachment.id}"

    response = client_for(bob).delete(url)
    assert response.status_code == 403

    response = client_for(alice).delete(url)
    assert response.status_code == 204
    assert not (settings.MEDIA_ROOT / attachment.file.name).exists()
SimpleUploadedFileis Django’s in-memory upload. It has a name, a size and content, which is all thatcheck_uploadand theFileFieldneed.data=fills the form fields andFILES=the files, the two halves of themultipart/form-datarequest thatcurl -Fsent in Part 6.TestClient’s fake request answersbuild_absolute_uri()with the hosttestlocation, so the resolver from Part 6 returnshttp://testlocation/media/....- The
settingsfixture gives the test theMEDIA_ROOTthattest_settingsset, so it can check the stored file on disk, and thatdelete_attachmentremoved it.
Go deeper: Testing
Running the tests
Run pytest from the folder with manage.py. As with every other command, run it through uv:
$ uv run pytest
============================= test session starts ==============================
...
django: version: 6.1.1, settings: locallibrary_config.settings (from ini)
...
collected 31 items

tests/test_auth.py ....                                                  [ 12%]
tests/test_projects.py ......                                            [ 32%]
tests/test_tasks.py ....................                                 [ 96%]
tests/test_auth.py .                                                     [100%]

============================== 31 passed in 0.52s ==============================
tests/test_auth.py shows up twice because pytest-django runs the tests that don’t use the database last. That’s test_missing_token. Each parametrized case is a test of its own, so the 12 test functions in test_tasks.py make 20 tests.
-k picks tests by name, and -v lists them. Each parametrized case gets an id built from its parameters:
$ uv run pytest tests/test_tasks.py -k filter -v
...
collecting ... collected 20 items / 14 deselected / 6 selected

tests/test_tasks.py::test_filter_tasks[-titles0] PASSED                  [ 16%]
tests/test_tasks.py::test_filter_tasks[status=todo&status=in_progress-titles1] PASSED [ 33%]
tests/test_tasks.py::test_filter_tasks[assignee=bob&label=bug-titles2] PASSED [ 50%]
tests/test_tasks.py::test_filter_tasks[due_before=2026-10-05-titles3] PASSED [ 66%]
tests/test_tasks.py::test_filter_tasks[search=VIEWS-titles4] PASSED      [ 83%]
tests/test_tasks.py::test_filter_tasks[ordering=-priority-titles5] PASSED [100%]

======================= 6 passed, 14 deselected in 0.31s =======================
When a check goes missing
A test suite proves its worth when someone breaks a rule by accident. Delete the author check from update_comment in tasks/api.py:
# tasks/api.py
    if comment.author != request.auth:
        raise HttpError(403, "Only the author can edit a comment")
Every other test still passes, and the endpoint still works for its author. Only the permission test notices:
$ uv run pytest
...
tests/test_tasks.py ................F...                                 [ 96%]
tests/test_auth.py .                                                     [100%]

=================================== FAILURES ===================================
______________________ test_only_author_can_edit_comment _______________________

alice = <User: alice>, bob = <User: bob>, task = <Task: Draft the sitemap>
client_for = <function client_for.<locals>.make_client at 0x7f6059af7a60>

    def test_only_author_can_edit_comment(alice, bob, task, client_for):
        comment = task.comments.create(author=bob, body="Looks good")
        url = f"/projects/{task.project_id}/tasks/{task.id}/comments/{comment.id}"

        response = client_for(alice).put(url, json={"body": "Changed"})
>       assert response.status_code == 403
E       assert 200 == 403
E        +  where 200 = <ninja.testing.client.NinjaResponse object at 0x7f6059b9a990>.status_code

tests/test_tasks.py:127: AssertionError
=========================== short test summary info ============================
FAILED tests/test_tasks.py::test_only_author_can_edit_comment - assert 200 ==...
========================= 1 failed, 30 passed in 0.59s =========================
pytest shows the fixtures the test received, the failing line, and the actual value: alice’s edit of bob’s comment returned 200. Put the two lines back before you continue.
TestClient skips urls.py and middleware to stay fast. To test the full stack, such as a custom middleware or the URL prefix, use Django’s own django.test.Client with the /taskflow/api/... URLs. Django Ninja views are normal Django views and work with it unchanged.
Go deeper: Testing
Recap
- pytest-django needs
DJANGO_SETTINGS_MODULEinpytest.ini. It creates a fresh test database and rolls back each test. - Fixtures in
conftest.pybuild users, a project with memberships, and aclient_for(user)factory that sends a JWT with every request. TestClient(api)calls operations directly, with paths relative to the API. Auth, validation and error handling still run.- Send bodies with
json=, form fields withdata=, files withFILES=andSimpleUploadedFile, and query strings in the path. parametrizeturns a table of cases, such as status moves or filter queries, into separate tests.- Point
MEDIA_ROOTattmp_pathand use a fast password hasher, so tests stay clean and take under a second.
Next
TaskFlow is complete and tested. In Part 8: OpenAPI polish & versioning, you’ll improve the generated docs with summaries, descriptions and examples, and run a second API version next to the first.
3.8 - Part 8: OpenAPI polish & versioning
TaskFlow works and is tested. Other people will build against it, though, and for them the interactive docs are the API. In this last part you’ll make the generated schema say more: what the API is for, what each operation does, and what each field expects. Then you’ll ship a breaking change the safe way, as a version 2 that runs next to version 1.
- How to set the API’s title, version and description
- How summaries, docstrings and
Field(description=..., examples=...)show up in the schema - How to hide an internal endpoint and mark old ones as deprecated
- How to run two
NinjaAPIversions side by side, sharing the routers that didn’t change - How URL namespaces keep
reverse()working with more than one API
Time: about 15 minutes
Describing the API
Open taskflow/api.py. NinjaAPI takes a version and a description next to the title you set in Part 1:
# taskflow/api.py
from ninja import NinjaAPI

from accounts.auth import JWTAuth

DESCRIPTION = (
    "Track the tasks of your team's projects: members, labels, comments and attachments.\n\n"
    "Get a token from `POST /auth/token`, then click **Authorize** and paste it."
)

api = NinjaAPI(
    title="TaskFlow API",
    version="1.0",
    description=DESCRIPTION,
    urls_namespace="taskflow",
    auth=JWTAuth(),
)
...
Leave the add_router() calls below it as they are for now. You’ll see the complete file once version 2 is in place.
The three values end up in the info block of /taskflow/api/openapi.json:
{
    "title": "TaskFlow API",
    "version": "1.0",
    "description": "Track the tasks of your team's projects: members, labels, comments and attachments.\n\nGet a token from `POST /auth/token`, then click **Authorize** and paste it."
}
- The docs page shows the title with the version next to it, and renders the description as Markdown, so
**Authorize**comes out bold. versionis a plain string. Django Ninja doesn’t parse it, but it does use it for the default URL namespace, as you’ll see at the end of this page. TaskFlow setsurls_namespace=itself, as it has since Part 1.
Go deeper: The NinjaAPI Instance
Summaries and descriptions
Every operation gets a summary, the one-line name in the docs. By default it’s the function name in title case: list_tasks becomes “List Tasks”, and create_task becomes “Create Task”. Good function names already give good summaries. When they don’t, pass summary=. A docstring becomes the operation’s description:
# tasks/api.py
@router.get("/", response=list[TaskOut])
@paginate(PageNumberPagination, page_size=20)
def list_tasks(
    request,
    project_id: Path[int],
    filters: Query[TaskFilter],
    ordering: TaskOrdering = "created_at",
):
    """List the tasks of a project, 20 per page. Filters combine with AND."""
    project = get_project_or_404(request.auth, project_id)
    tasks = filters.filter(project.tasks.select_related("assignee").prefetch_related("labels"))
    return tasks.order_by(ordering, "id")


...


@router.post("/{task_id}/status", response=TaskOut, summary="Move a task to another status")
def change_status(request, project_id: Path[int], task_id: int, payload: StatusIn):
    """
    Allowed moves:

    - `todo` to `in_progress`
    - `in_progress` to `todo` or `done`
    - `done` to `in_progress`

    Any other move returns **409 Conflict**.
    """
    task = get_task_or_404(request.auth, project_id, task_id)
    if payload.status not in ALLOWED_TRANSITIONS[task.status]:
        raise HttpError(409, f"Can't move a task from {task.status} to {payload.status}")
    task.status = payload.status
    task.save()
    return task
“Change Status” would be a fine summary too, but it doesn’t say what it changes. Here is the operation in /taskflow/api/openapi.json, with the parameters and responses left out:
{
    "operationId": "tasks_api_change_status",
    "summary": "Move a task to another status",
    "description": "Allowed moves:\n\n- `todo` to `in_progress`\n- `in_progress` to `todo` or `done`\n- `done` to `in_progress`\n\nAny other move returns **409 Conflict**.",
    "tags": [
        "tasks"
    ]
}
- The docstring’s indentation is removed, and the docs render the list and the bold text as Markdown.
- The docstring is the place for rules a client can’t see in the schema, such as the transitions from Part 3. The schema already says that
statusis one of three values. It can’t say which moves are allowed. operationIdis built from the module and function name. Client generators typically use it to name the generated method. Passoperation_id="..."to an operation to choose your own. It must be unique across the schema.tagscomes fromRouter(tags=["tasks"])in Part 1.
Go deeper: Operations: summary, Operations: operation_id
Describing fields
Field names like title and due_date explain themselves. assignee_id and label_ids have rules the schema can’t show on its own: they must point to a member and to labels of the same project. Pydantic’s Field() adds a description and example values:
# tasks/schemas.py
class TaskIn(TaskUpdate):
    assignee_id: int | None = Field(None, description="A member of the project", examples=[2])
    label_ids: list[int] = Field([], description="Labels of the same project", examples=[[1]])

...


class TaskFilter(FilterSchema):
    status: Annotated[list[TaskStatus] | None, FilterLookup("status__in")] = None
    assignee: Annotated[str | None, FilterLookup("assignee__username")] = None
    label: Annotated[str | None, FilterLookup("labels__name")] = None
    due_before: Annotated[date | None, FilterLookup("due_date__lt")] = None
    search: Annotated[
        str | None, FilterLookup(["title__icontains", "description__icontains"])
    ] = Field(None, description="Text to find in the title or the description")
The first argument of Field() is the default, the same value the fields had before. Field is already imported in tasks/schemas.py from Part 6. The two fields in the TaskIn schema:
{
    "assignee_id": {
        "anyOf": [
            {
                "type": "integer"
            },
            {
                "type": "null"
            }
        ],
        "description": "A member of the project",
        "examples": [
            2
        ],
        "title": "Assignee Id"
    },
    "label_ids": {
        "default": [],
        "description": "Labels of the same project",
        "examples": [
            [
                1
            ]
        ],
        "items": {
            "type": "integer"
        },
        "title": "Label Ids",
        "type": "array"
    }
}
examplesis a list of complete values. For a list field, each example is itself a list, hence[[1]].- The same works in a
FilterSchema.searchis a query parameter, and its description appears next to it in the docs:
{
    "in": "query",
    "name": "search",
    "schema": {
        "anyOf": [
            {
                "type": "string"
            },
            {
                "type": "null"
            }
        ],
        "description": "Text to find in the title or the description",
        "title": "Search"
    },
    "required": false,
    "description": "Text to find in the title or the description"
}
Go deeper: Query Parameters, Request Body
Hiding an internal endpoint
A load balancer or an uptime monitor needs a URL that answers without a token. It’s not part of the API you offer to clients, so it doesn’t belong in the docs. Register it on api directly, with no auth and include_in_schema=False:
# taskflow/api.py
@api.get("/health", auth=None, include_in_schema=False)
def health(request):
    return {"status": "ok"}
GET /taskflow/api/health works without a token:
{
    "status": "ok"
}
/taskflow/api/health isn’t in the paths of /taskflow/api/openapi.json, so the docs don’t show it. Hiding an operation is not a security measure: anyone who knows the URL can still call it. Protect it with auth if it returns anything private.
Go deeper: Operations: include_in_schema
A second version
A mobile team wants to use TaskFlow with a standard OAuth2 client library. The library expects the token response to use OAuth2’s field names: access_token, refresh_token, token_type and expires_in. TaskFlow returns access and refresh. Renaming the fields would break every client that already logs in, so the new shape goes into a version 2 of the API. Version 1 stays as it is.
The new schemas go into accounts/schemas.py:
# accounts/schemas.py
from typing import Literal

from django.contrib.auth.models import User
from ninja import ModelSchema, Schema
from pydantic import Field

...


class OAuthTokenOut(Schema):
    access_token: str
    refresh_token: str
    token_type: Literal["bearer"]
    expires_in: int = Field(description="Seconds until the access token expires", examples=[900])


class OAuthRefreshIn(Schema):
    refresh_token: str
The version 2 endpoints go into a new module:
# accounts/api_v2.py
from ninja import Router

from . import api as v1
from .schemas import OAuthRefreshIn, OAuthTokenOut, RefreshIn, TokenIn
from .tokens import ACCESS_TOKEN_LIFETIME

tokens = Router(tags=["auth"], auth=None)


def oauth_response(pair):
    return {
        "access_token": pair["access"],
        "refresh_token": pair["refresh"],
        "token_type": "bearer",
        "expires_in": ACCESS_TOKEN_LIFETIME,
    }


@tokens.post("/token", response=OAuthTokenOut)
def obtain_token(request, payload: TokenIn):
    """Exchange a username and password for an access and a refresh token."""
    return oauth_response(v1.obtain_token(request, payload))


@tokens.post("/refresh", response=OAuthTokenOut)
def refresh_token(request, payload: OAuthRefreshIn):
    """Exchange a refresh token for a new pair of tokens."""
    return oauth_response(v1.refresh_token(request, RefreshIn(refresh=payload.refresh_token)))
- Only the shape changes, so version 2 calls the version 1 views. An operation decorator registers the function and returns it unchanged, so
v1.obtain_tokenis still a plain Python function. - The
HttpError(401, ...)raised inside a v1 view propagates to the v2 operation and becomes the same401response. - The login request body,
TokenIn, doesn’t change. The refresh body does, fromrefreshtorefresh_token.
Splitting the auth router
A router is the unit you mount into an API. You can’t mount a router without some of its operations, so everything that differs between versions must live in a router of its own. In accounts/api.py, signup stays on router, and the two token endpoints move to a new tokens router that only version 1 mounts:
# accounts/api.py
from django.contrib.auth import authenticate
from django.contrib.auth.models import User
from django.contrib.auth.password_validation import validate_password
from django.core.exceptions import ValidationError
from ninja import Router, Status
from ninja.errors import HttpError

from .schemas import RefreshIn, SignupIn, TokenIn, TokenOut, UserOut
from .tokens import create_token_pair, decode_token

router = Router(tags=["auth"], auth=None)  # shared by v1 and v2
tokens = Router(tags=["auth"], auth=None)  # v1 only


@router.post("/signup", response={201: UserOut})
def signup(request, payload: SignupIn):
    if User.objects.filter(username=payload.username).exists():
        raise HttpError(409, "This username is taken")
    try:
        validate_password(payload.password)
    except ValidationError as e:
        raise HttpError(400, " ".join(e.messages))
    user = User.objects.create_user(payload.username, password=payload.password)
    return Status(201, user)


@tokens.post("/token", response=TokenOut, deprecated=True)
def obtain_token(request, payload: TokenIn):
    """Use `POST /taskflow/api/v2/auth/token` instead."""
    user = authenticate(username=payload.username, password=payload.password)
    if user is None:
        raise HttpError(401, "Invalid username or password")
    return create_token_pair(user.id)


@tokens.post("/refresh", response=TokenOut, deprecated=True)
def refresh_token(request, payload: RefreshIn):
    """Use `POST /taskflow/api/v2/auth/refresh` instead."""
    claims = decode_token(payload.refresh, "refresh")
    if claims is None or not User.objects.filter(id=claims["sub"], is_active=True).exists():
        raise HttpError(401, "Invalid or expired refresh token")
    return create_token_pair(int(claims["sub"]))
deprecated=True tells clients to move on without breaking them. The endpoints keep working, and the docs show them as deprecated. The docstring says where to go instead. In the v1 schema:
{
    "summary": "Obtain Token",
    "description": "Use `POST /taskflow/api/v2/auth/token` instead.",
    "deprecated": true
}
Go deeper: Operations: deprecated
Mounting both versions
Version 2 is a second NinjaAPI instance. Here is the complete taskflow/api.py:
# taskflow/api.py
from ninja import NinjaAPI

from accounts.auth import JWTAuth

DESCRIPTION = (
    "Track the tasks of your team's projects: members, labels, comments and attachments.\n\n"
    "Get a token from `POST /auth/token`, then click **Authorize** and paste it."
)

api = NinjaAPI(
    title="TaskFlow API",
    version="1.0",
    description=DESCRIPTION,
    urls_namespace="taskflow",
    auth=JWTAuth(),
)

api.add_router("/auth", "accounts.api.router")
api.add_router("/auth", "accounts.api.tokens")
api.add_router("/projects", "projects.api.router")
api.add_router("/projects/{project_id}/tasks", "tasks.api.router")


@api.get("/health", auth=None, include_in_schema=False)
def health(request):
    return {"status": "ok"}


api_v2 = NinjaAPI(
    title="TaskFlow API",
    version="2.0",
    description=DESCRIPTION + "\n\nNew in 2.0: token responses use OAuth2 field names.",
    urls_namespace="taskflow-v2",
    auth=JWTAuth(),
)

api_v2.add_router("/auth", "accounts.api.router")
api_v2.add_router("/auth", "accounts.api_v2.tokens")
api_v2.add_router("/projects", "projects.api.router")
api_v2.add_router("/projects/{project_id}/tasks", "tasks.api.router")
- Both APIs mount the same
signup, projects and tasks routers. Each mount gets its own copy of the router’s operations, bound to that API, so the two versions don’t interfere. A bug fix intasks/api.pyreaches both versions at once. - Only the
tokensrouters differ:accounts.api.tokensfor version 1, andaccounts.api_v2.tokensfor version 2. healthis registered onapionly.GET /taskflow/api/v2/healthreturns404.- Mounting two routers at the same prefix, like the two
/authmounts, is fine as long as their paths don’t overlap.
Mounting the same router twice on one API is different. Every operation’s URL name must be unique within an API, so Django Ninja refuses the second mount:
ninja.errors.ConfigError: Router is already mounted to this API. When mounting the same router multiple times, you must provide unique url_name_prefix for each mount.
Pass url_name_prefix="..." to the second add_router() call if you really need both mounts.
Then give version 2 its own URL prefix. Replace the TaskFlow block you added to the end of locallibrary_config/urls.py in Part 1. Version 1 stays at /taskflow/api/, so existing clients don’t notice a thing:
# locallibrary_config/urls.py
# Mount the TaskFlow API from the Django Ninja Tutorial
from taskflow.api import api as taskflow_api, api_v2 as taskflow_api_v2

urlpatterns += [
    path('taskflow/api/v2/', taskflow_api_v2.urls),
    path('taskflow/api/', taskflow_api.urls),
]
Go deeper: Versioning, Routers
Try it
Log in through version 2 with POST /taskflow/api/v2/auth/token and {"username": "alice", "password": "wonderland-42"}:
{
    "access_token": "eyJhbGciOiAiSFMyNTYiLCAidHlwIjogIkpXVCJ9.eyJzdWIiOiAiMSIsICJ0eXBlIjogImFjY2VzcyIsICJleHAiOiAxNzkwNTk1OTIyfQ.uKbqv565JqGDjMxFrjzfwEF2zf5mmDv4fiFK2W0lI64",
    "refresh_token": "eyJhbGciOiAiSFMyNTYiLCAidHlwIjogIkpXVCJ9.eyJzdWIiOiAiMSIsICJ0eXBlIjogInJlZnJlc2giLCAiZXhwIjogMTc5MTE5OTgyMn0.sPAI0PFLkazt-NUORo9u7INLum8b9HrTKnqRT1-XEY8",
    "token_type": "bearer",
    "expires_in": 900
}
The tokens are the same JWTs as before, and both APIs check them with the same JWTAuth. So a token from either version works on both: with this access_token, GET /taskflow/api/projects/ and GET /taskflow/api/v2/projects/ both return 200.
The old field name no longer works on version 2. POST /taskflow/api/v2/auth/refresh with {"refresh": "..."} returns 422:
{
    "detail": [
        {
            "type": "missing",
            "loc": [
                "body",
                "payload",
                "refresh_token"
            ],
            "msg": "Field required"
        }
    ]
}
With {"refresh_token": "..."} it returns a new token pair in the version 2 shape.
Now compare the two docs pages. http://127.0.0.1:8000/taskflow/api/docs shows version 1.0, with the two token endpoints marked as deprecated. http://127.0.0.1:8000/taskflow/api/v2/docs shows version 2.0 and the extra line of description, and it loads its schema from /taskflow/api/v2/openapi.json. Both schemas have the same 14 paths. Only POST /auth/token and POST /auth/refresh differ, and the component schemas TokenOut and RefreshIn of version 1 become OAuthTokenOut and OAuthRefreshIn in version 2.
Go deeper: Versioning: multiple NinjaAPI instances
URL namespaces
Each NinjaAPI registers its URLs under its own namespace, api-<version> by default. Since Part 1, TaskFlow has set urls_namespace= instead, and version 2 does the same. The operation names come from the function names, so reverse() needs the namespace to tell the two versions apart:
$ uv run python manage.py shell
>>> from django.urls import reverse
>>> reverse('taskflow:obtain_token')
'/taskflow/api/auth/token'
>>> reverse('taskflow-v2:obtain_token')
'/taskflow/api/v2/auth/token'
>>> reverse('taskflow-v2:openapi-view')
'/taskflow/api/v2/docs'
In the original tutorial, TaskFlow is the only API in the project, so setting version on both APIs is enough to keep their namespaces apart: api-1.0 and api-2.0. Your locallibrary has a third API, the one from the Quickstart, and it still has the default version, "1.0.0", and the default namespace, api-1.0.0. In Parts 1 to 7, TaskFlow had the default version too. Two APIs with the same version share a namespace, and manage.py check warns about it. Without urls_namespace="taskflow", you would have seen this since Part 1:
$ uv run python manage.py check
System check identified some issues:

WARNINGS:
?: (urls.W005) URL namespace 'api-1.0.0' isn't unique. You may not be able to reverse all URLs in this namespace

System check identified 1 issue (0 silenced).
In that setup, reverse() can return a URL from the wrong API. That’s why both TaskFlow APIs set their own urls_namespace=, whatever their versions: if two APIs might share a version, give them distinct urls_namespace= values.
Go deeper: URLs & Reverse
Testing both versions
A version is a promise to its clients, so it deserves its own tests. TestClient takes any NinjaAPI, so each version gets a client:
# tests/test_versions.py
from ninja.testing import TestClient

from taskflow.api import api, api_v2

client_v1 = TestClient(api)
client_v2 = TestClient(api_v2)


def test_v2_token_response(alice):
    response = client_v2.post("/auth/token", json={"username": "alice", "password": "wonderland-42"})
    assert response.status_code == 200
    data = response.json()
    assert data["token_type"] == "bearer"
    assert data["expires_in"] == 900

    # Both versions accept the same access token
    headers = {"Authorization": f"Bearer {data['access_token']}"}
    assert client_v1.get("/projects/", headers=headers).status_code == 200
    assert client_v2.get("/projects/", headers=headers).status_code == 200


def test_v2_refresh(alice):
    tokens = client_v2.post(
        "/auth/token", json={"username": "alice", "password": "wonderland-42"}
    ).json()
    response = client_v2.post("/auth/refresh", json={"refresh_token": tokens["refresh_token"]})
    assert response.status_code == 200
    assert set(response.json()) == {"access_token", "refresh_token", "token_type", "expires_in"}

    response = client_v2.post("/auth/refresh", json={"refresh_token": tokens["access_token"]})
    assert response.status_code == 401
Paths are relative to the API, so /auth/token on client_v2 is /taskflow/api/v2/auth/token. The Part 7 tests run against api and still pass, because version 1 behaves exactly as before:
$ pytest
...
tests/test_auth.py ....                                                  [ 12%]
tests/test_projects.py ......                                            [ 30%]
tests/test_tasks.py ....................                                 [ 90%]
tests/test_versions.py ..                                                [ 96%]
tests/test_auth.py .                                                     [100%]

============================== 33 passed in 0.55s ==============================
pytest-django runs the tests that use the database first, which is why the last test of test_auth.py, test_missing_token, runs at the end.
Go deeper: Testing
Recap
NinjaAPI(title=..., version=..., description=...)fills theinfoblock of the schema. The description is Markdown.- Summaries come from function names unless you pass
summary=. Docstrings become descriptions, andoperationIdcomes from the module and function name unless you passoperation_id=. Field(description=..., examples=[...])documents fields in body schemas and in filter schemas alike.include_in_schema=Falsehides an endpoint from the docs, anddeprecated=Truemarks one as on its way out. Both keep working.- A new version is a second
NinjaAPIat its own URL prefix. Routers that didn’t change are mounted on both, and whatever changed goes into a router of its own. - Different versions get different URL namespaces, so
reverse()andmanage.py checkstay happy.
Next
That’s the whole tutorial. TaskFlow has routers per app, nested schemas and computed fields, validation, JWT auth with roles, filtering and pagination, file uploads, a test suite and two documented API versions. From here, the Guide covers each feature in depth, including the ones this tutorial skipped, such as async views, throttling, custom renderers and parsers, and webhooks.